Week 1 HW: Final Project Idea - Cell-Free Stain Remover
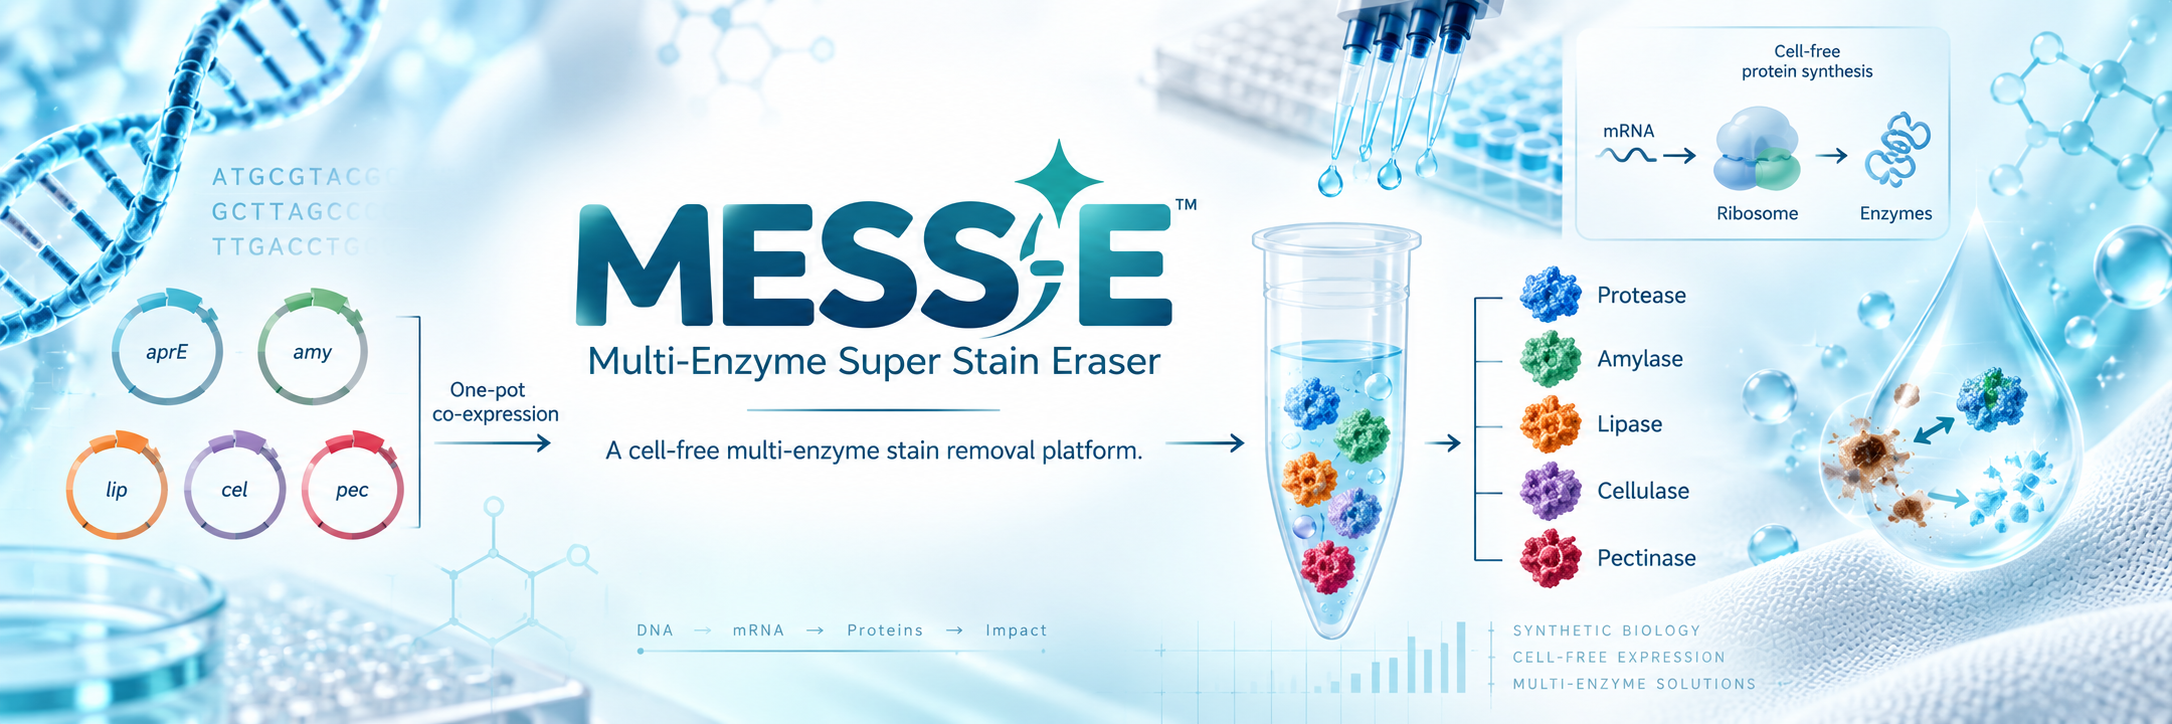 Source: ChatGPT
#1
Imagine that you are at your favorite Italian restaurant, eating your favorite spaghetti bolognese dinner. You are twirling your spoon in the dish, gearing ready for liftoff onto Planet Tastebuds, for what you believe will be one of the best looking bites of the evening. However, one conspicuously lodged noodle stands in the way between you and sensory satisfaction. You think logically to yourself, “Hey, I may have noodle-looking arms, but I’m stronger than an actual noodle”, and you give the tiniest tug possible, immediately dominating your foe, unlodging the foe, and paving the wave for a clear destruction of the foe via tongue and teeth. After you have finished chewing the last bit of the bite, sighing to yourself with happiness, you look down for the next bite, and find yourself utterly shocked at what beholds you on your new white shirt. In the end, despite your seemingly overpowering, simple maneuver to conquer the noodle, it ended up getting the last laugh: tiny red dots scatter the white canvas, and the heinous horrors of the tomato stain have struck you again.
What you need is the Multi-Enzyme Super Stain Eraser (MESS-E) pen! All you need to do is add water to this amazing lyophilized cell-free lysate. With combinatorial co-expression of the right DNA in the right blend, you get the exact optimized blend of protease, amylase, lipase, cellulase, and pectinase to fight your specific stain, leaving you as a worry-free Italian dinner date.
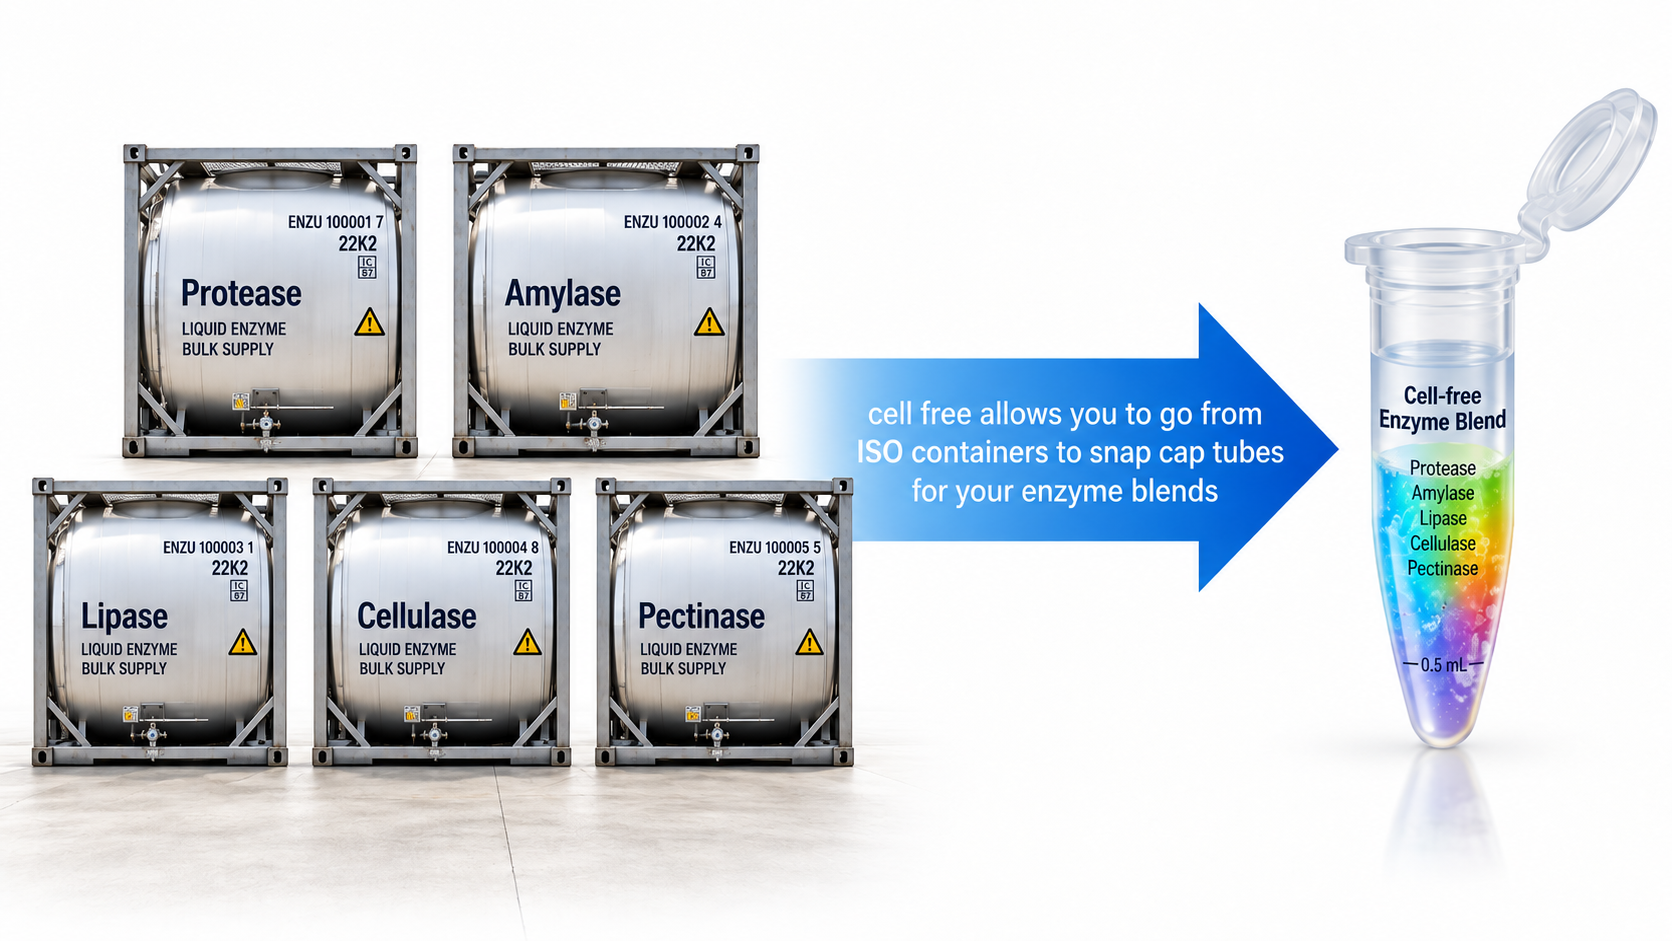
How did I come up with this revolutionary stain fighter? 1) The messy eater in me relates to everyone else in that all of us have begrudgingly confronted stains on our favorite clothes while away from the house. Current portable stain pen options do not carry enzymes in them. When you only have those as an option, you are not only leaving (by far) the best cleaning technology on the shelf at home, but you are also subjecting your clothes and skin to harsh and bleaching chemicals. I’d be remiss not to mention 2) The enzyme biomanufacturer in me is not only fascinated by the mundane power of enzymes to clean our clothes, but I have also seen first-hand how cumbersome and carbon-carbon-intensive it is to manufacture enzymes via legacy single-fermentation, single-enzyme fermentation. While there are significant benefits to economies of scale, the blending process needed to create enzyme blends for products such as laundry detergent and stain removers is far from efficient and optimized, requiring significant isotanker storage space, large scale machinery, and lead time. A cell-free system can accomplish a specific blend with high sustainability for the volumes required.
Aside from the relatability, I also believe that this is a remarkably practical project to assay for results, and success in this project will help tackle the challenge of single-pot co-expression of enzyme blends via . Moreover, it has real commercial viability at the current state of the cell-free technology, particularly because stain volumes are often very small, matching the current phase of the technology.
Finally, trying to conquer this goal of single-pot cell free co-expression has huge implications for the future of the field. While this is historically difficult with microbial manufacturing, these cell-free systems could help to produce tailored enzyme cocktails necessary to valorize various feedstocks for biomanufacturing, develop cascades in metabolic pathways for small molecule product (as seen in Reading #3 Rasor, et al. 2021), or true recycling from complex waste resources.
#2
As mentioned in question number one, the Multi-Enzyme Super Stain Eraser (MESS-E) pen will run on a cell-free chassis! Getting one microbe, or a co-culture of microbes, to express multiple types of enzymes in the right blend ratio is very difficult. However, by combinatorially adjusting the concentrations of various enzyme DNA-templates (as described in Lim et al., 2026), a cell-free system should be able to accomplish this task.
At a high level, my chassis will start with the guts of a E. coli crude-lysate, using the optimized cost-effective reagent protocols developed in recent work between Open AI and Ginkgo Bioworks (Smith et al., 2026). Then, I will add 5 DNA templates for well-known bacterial proteases, amylases, lipases, cellulases, and pectinases, as well as other necessary cofactors or amino acids needed to optimize the protocol.
The biological process that occurs inside a cell free system is relatively simple. Since this is a one-pot reaction, the main process includes the use of the E. coli transcription (RNA polymerase) and translation (ribosomes and tRNA) machinery to start expressing the multi-enzyme blend. What comes out of the reaction is a crude mixture, and for the application of stain removal in a small quantity, luckily no downstream purification is necessary. However, hopefully the enzyme proteins are stable and in high enough concentration to each show individual enzyme activity, as well as combined activity against common household stains.
#3
I plan to use a desktop liquid-handling robot. The desktop liquid handling robot will help me in two key areas: First, I will follow Lim et al., 2026 to optimize my blend of the enzymes. The liquid handler will set up a high-throughput screening protocol for dozens of single-pot multi-enzyme cell free reactions with varied DNA template concentrations. Second, I will use the liquid handler to combinatorially assay each of these replicates. After the cell-free reaction is complete, the robot will transfer the single pot onto standardized assays (ex. fabric swatches) that correspond to each enzyme type, including protein, starch, oil, cellulose, and pectin stains, and then one complex stain. Then, I would use image analysis to determine stain removal for each of the isolates. Ideally, given more opportunities to run the experiment, I could optimize the DNA concentrations over multiple iterations.
(AI Used: Chat-GPT. Prompt: How can I use a liquid handler or other lab automation to quantify stain removal in a high-throughput cell-free reaction screen?)
#4
How much: I am lucky for this application for stain spot-treatment removal requires very small volumes of liquid. Assay volumes aside, I will use a Tide Pen to get the volumes necessary for my single-pot MESS-E pen:
Each Tide Pen contains approximately 10 mL of volume, and it is “designed to handle over 100 fresh food and drink stains” - Hannaford.com https://hannaford.com/groceries/product/tide-to-go-instant-stain-remover-pens-3-ct-1-01-oz-pkg/356964
I’ll assume that 100+ = 150 stains, and I am OK with making that general assumption given that I know that enzymes clean better than Tide pen chemicals, so a smaller volume will likely be used for enzymatic spot treatment.
10 mL/150 stains = ~67 microliters/stain.
Thus, each cell free reaction for my single-use MESS-E pen will be 67 microliters.
How long: First, it likely takes at least 1 day to prepare a cell-free lyophilized lysate, so I am looking at a minimum 2 days from start to finish to manufacture the single-use MESS-E pen for the customer.
Second, the customer will consider application time. (This is where we start to get into some of the realism breakdown, and I probably should have checked this before choosing this project…)
Lim et al., 2026 conducted a multi-enzyme cell-free reaction of 35 microliters in 16 hours.
Thus, using their same ratio means that MESS-E amount of 67 microliters x (15 hours / 35 microliters) = 28.7 hours for MESS-E to work.
This is definitely a tough realization that my single-pot multi-enzyme cell free reaction might take over an entire day to complete. Therefore, I will now argue that, as well as optimizing the blend, lab automation time should also be dedicated to optimizing the timescale of protocol to balance stain removing efficacy vs. time to yield enough enzyme to get measurable stain removable results.
#5
The first major technical hurdle is whether or not 5 distinct enzymes of different enzyme classes can be successfully co-expressed using one chassis. DNA expression aside, enzymes are also incredibly finicky proteins, all needing the salt conductivity, solvent, and temperature environment to remain active. If my enzymes have mismatched characteristics and I have skewed reaction conditions, only one or a couple enzymes might actually be expressed. To combat this, I first need to make sure that I research in the literature to find enzymes that are cooperative, related, and experimentally shown to be reactive in the same environment. Second, I may need to use the liquid handling to optimize solvent/reagent conditions in a high-throughput screen to address incompatibility issues. Third, if I start to see a breakdown in the 5-enzyme blend, I may need to experimentally measure combinations of enzyme pairs/triplets to see which enzyme/enzyme pairings are the most incompatible. This may cause me to revisit the DNA templates and enzymes that I originally chose.
A second major technical hurdle is the timing of the multi-enzyme cell free protein synthesis. As I mentioned in question #4, to make this a societally valuable product, I will need to focus optimizing energy and attention on shortening the timing of the reaction. Instead of just digging into the literature regarding enzyme-class concentration optimization, I should also dive into the literature regarding protocol changes to speed up the time of cell-free protein expression. I can also measure this using automation high-throughput liquid handling techniques, changing temperature, ratios of reagents, lysate concentration, DNA primers and construct optimization, faster folding enzymes, etc. to shorten the time for stain removers.
(AI Used: Chat-GPT. Prompt: What could I change to optimize the time of cell-free protein expression?)
Sources (Outside of the Readings)
Lim, H., Chae, Y., Nam, D., Jeong, S., Yun, H., Lee, D., & Kang, T. J. (2026). Lycopene pathway rewiring by combinatorial co-expression of constituent enzymes in a cell-free protein synthesis system. New Biotechnology, 95, 1–13. https://doi.org/10.1016/j.nbt.2026.07.001
Smith, A. A., Wong, E. L., Donovan, R. C., et al. (2026). Using a GPT-5-driven autonomous lab to optimize the cost and titer of cell-free protein synthesis [Preprint]. Ginkgo Bioworks & OpenAI.
Week 2 HW: DNA Design
Part 0: Set up in Kernel
Repo is titled CBillingsley. My homework folder is titled Billingsley-HTGAA_Project.
Part 1: Define your expression target
The molecules that I am expressing are 5 separate enzymes: protease, amylase, lipase, cellulase, and pectinase. The sequences will come from the UnitProt database, with the ID numbers listed in the answer to part 2.
The chassis is a cell-free system, derived from an E. coli cell lysate. The end product will ultimately be an application of the direct cell-free reaction, so the product(s) do not need to be secreted or targeted anywhere other than the traditional mixture.
Part 2: Design your genetic parts
For each of my five constructs, I used:
Promoter BBa_J23101. This is from the iGEM Part Registry. The reason this was selected was because it is a standard constitutive promoter that can be expressed in E. coli and does not require any sort of induction or modulation to function.
RBS BBa_B0034, a standard strong E. coli RBS. This is from the iGEM Part Registry. I chose this as a standard strong RBS. This seems like it will translate to my 5 different enzymes.
Terminator BBa_B0015. This is from the iGEM Part Registry. I chose this as a standard Terminator that seems to be effective for simple constructs and will translate well to a simple cell-free expression constructs.
For my 5 constructs, I did use ChatGPT to help me find 5 well-characterized bacterial enzymes that would help give me a good starting point for my project.
Protease: Subtilisin, UniProt P04189
Amylase: Alpha-amylase, UniProt P00691
Lipase: Lipase A / EstA, UnitProt P37957
Cellulase: Endoglucanase EglS, UnitProt P10475
Pectinase: Pectate lyase, UnitProt P39116
Part 3: Assemble your construct
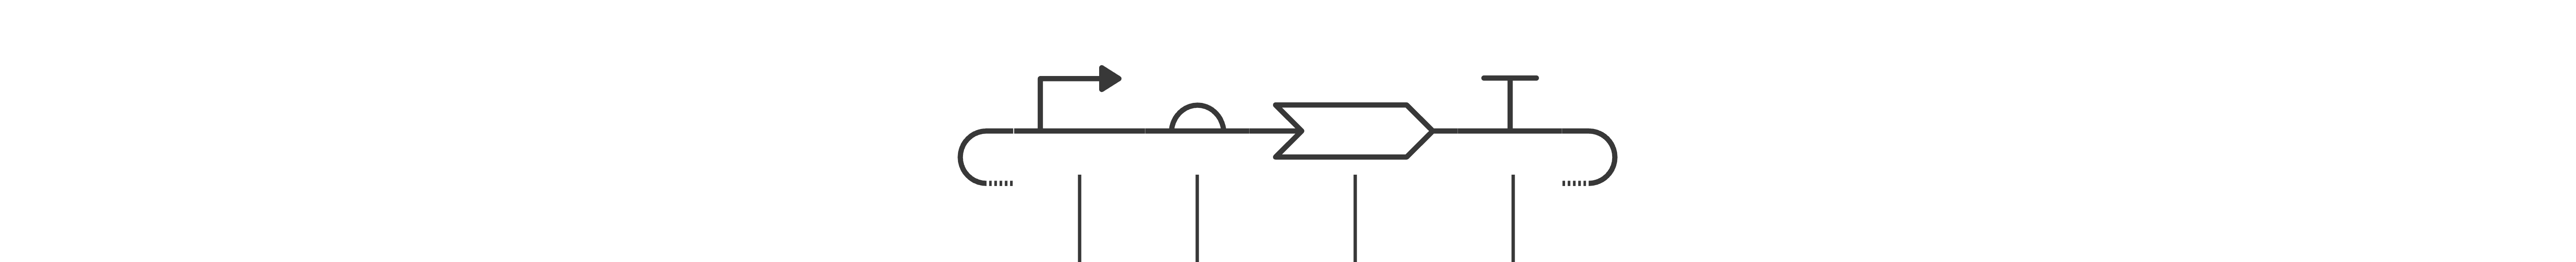
I followed the generic description for each of my 5 constructs, including going from promoter → standard RBS → [variable CDS] → standard strong terminator. Because I am not yet at the point where I am thinking about how I will put the enzymes into my cocktail and if they might have different promoters/relative strength TX/TL machinery, the only difference between the constructs is their CDS, which is a E. coli codon optimized version of the UniProt protein sequences.
Part 4: Optimize and quality-check
Codon-optimize: Because I started from the UniProt protein sequences, all of my constructs were codon optimized already. Since I will have a cell free lysate, I chose not to worry about restriction sites.
Sequence search: Yes, when I blast my sequences, they return the same sequences that ChatGPT helped me to elucidate for the project.
Safety Screen: It looks like the sequence safety scanner does a sequence comparison for flagged sequences of concern. Luckily, nothing flagged for me, since I am using 5 well-characterized, safe bacterial enzymes.
Part 5: From design to build
Since my constructs are relatively small and simplistic, I believe that it would be the most cost effective to order a pool of oligos from a synthetic DNA maker. If I needed more constructs, I could create promoters and amplify the constructs through PCR too.
My sequence does not contain certain sequences that might be hard to synthesize due to the inevitable simplicity of a cell-free protein synthesis system of this scale.
While I would potentially test my idea by synthesizing a bunch of oligos in a one pot reaction, I would have to start the separate them out and dose them in various concentrations to start to mimic the precise control that I would like to have over the reaction and the cocktail of enzymes for proper cleaning efficiency.
Part 6: What don’t you know yet?
I think one of the biggest unknowns that I have yet to figure out is the fact that once an active protease in my reaction, it may start digesting your other four enzymes or even components of the lysate. However, proteases are such important components of cleaning stains that we get on our clothes, so I will have to try to work with my concoction. To check if this happens, I would be able to run a CFPS reaction with and without the protease construct being dosed, and I will evaluate what the end titer is of the reaction and verify if other proteins have been degraded with a technique such as SDS PAGE.
The second unknown is whether or not I will want to have different construct architecture for my different enzymes (e.g. each has a different promoter of a varying strength). I have already decided that I would like to vary the concentrations of these different types of enzymes in my end product, and I know that previous literature has identified that you can vary construct concentration to achieve this end. However, I will want to run various CFPS reactions with different constructs having different promoters and evaluating if I see a resulting difference in protein concentration.
Week 3 HW: Cell-Free Protocols
QUESTION 1: Why does the concentration of potassium glutamate and magnesium glutamate differ between compositions? Which is more sensitive?
K-Glu supports the general conductive/ionic environment of the cell-free lysate, which has a direct effect on ribosome, enzyme, and protein–nucleic acid binding (ex. transcription) function. The concentration range for effectiveness is broad. Mg-Glu supplies magnesium ions that directly bind to ribosomes, tRNAs, TX/TL enzymes, and ATP/NTPs. Mg-Glu concentration is highly sensitive, and this concentration is far more sensitive.
QUESTION 2: Explain how a PEP+NTP reaction formulation is different from a Ribose+NMP reaction formulation.
A PEP+NTP is the definition of paying a lot of money upfront for highly energetically charged intermediates that can supercharge a CFPS reaction to get high titer/yields. However, the cost is prohibitively expensive to support sustainable, realistic biomanufacturing production.
Meanwhile, a Ribose+NMP fed reaction is an example of a CFPS reaction where you feed relatively inexpensive reagents and rely on a well-balanced, well-stabilized, and energy-regenerating metabolic network to still power a CFPS reaction. Many reaction conditions come into play here, such as salt and pH buffering reagents, dissolved oxygen supply, and other cellular compositions.
QUESTION 3: Choose two cell-free reaction compositions from the literature, compare and contrast the choice of reagents and the concentration of reagents.
I’ll choose to compare the first major reaction formulation, PANOx-SP with the AI-optimized formulation from Ginkgo/Open-AI. For one, PANOx-SP used expensive PEP as the energy-charged intermediate/phosphate donor and directly supplied expensive NTPs. The AI formulation provides less-expensive ribose and NMPs and relies on the CF metabolism to recharge these molecules.
Another difference is that the Ginkgo/Open-AI formulation has very high K-Glu concentrations and allows for some HEPES-KOH pH buffer solution, supporting the idea that salt requirements and pH conditions greatly affect protein production and energy regeneration. PANOx-SP had zero HEPES and much lower K-Glu conditions.
A final difference is that the AI formulation was able to supply zero ATP or NTs, nor any NAD/CoA, all of which are very expensive and were used in PANOx-SP. This is a big breakthrough for allowing the cell’s metabolism to build up a robust protein production environment.