Week 2 HW: DNA Design
Lactate oxidase for a sweat biosensor
Project overview
For this assignment, I designed a DNA construct that could be used to produce L-lactate oxidase (LOx), the enzyme component of a future sweat-lactate biosensor. The important distinction is that the engineered bacteria are a manufacturing system: they would make the enzyme in the laboratory, after which the enzyme would be purified and incorporated into a wearable electrochemical patch. No living genetically modified bacteria are intended to be placed in the wearable or on the user’s skin.
The work is saved in the Kernel repository chiun-lactate-sweat-patch, inside the folder lee-lactate-oxidase-hw2. The final draft construct is named Biosensor-LOx-expression-draft-v1.
Open the actual Kernel construct
In the terminology used here, a part is one reusable DNA element, such as a promoter, ribosome binding site, coding sequence, or terminator. A construct is the complete DNA molecule created by arranging those parts in a defined order. I saved the native reference gene, the optimized and tagged gene, the promoter, and the RBS as separate project parts. The terminator and plasmid backbone were referenced from Kernel’s iGEM library.
1. What the enzyme does and what the patch would measure
The expression target is L-lactate oxidase from Aerococcus viridans. Its verified reference protein is 374 amino acids long and is recorded as UniProt Q44467. I traced the corresponding native DNA to GenBank D50611.1, bases 316–1440 of the coding sequence, which encodes protein BAA09172.1. Verifying both the protein record and the nucleotide record was important because the design should begin from a known biological sequence rather than an untraceable sequence copied from a secondary source.
LOx catalyzes this reaction:
L-lactate + oxygen → pyruvate + hydrogen peroxide
The enzyme uses flavin mononucleotide (FMN) as a cofactor. In a proposed electrochemical patch, the purified LOx would react with lactate in sweat. The reaction produces hydrogen peroxide, or another reaction-linked change, that can be detected electrically at an electrode. Calibration with known lactate standards would then relate electrical signal to lactate concentration. The DNA plasmid is therefore not itself the sensor; it is the manufacturing instruction used to produce the sensing enzyme.
The proposed production host is E. coli BL21(DE3). This strain is commonly used for recombinant protein expression because the DE3 system supplies T7 RNA polymerase, which recognizes the T7 promoter in this construct. The enzyme is designed to remain in the cytoplasm, so no secretion signal was added. After cell growth and expression, the cells would be collected and lysed, and the enzyme would be recovered and purified.
This design is only one component of a possible sweat-lactate sensor. It does not yet prove that sweat lactate directly measures muscle strain, predicts injury, or determines when someone should stop exercising. Sweat-gland metabolism, collection method, sweat rate, oxygen availability, temperature, pH, electrode chemistry, and interfering molecules can all affect the measurement. A separate uricase-based wound-monitoring idea is not part of this construct.
2. Design requirements
Before assembling parts, I translated the project idea into a short list of design requirements:
- The construct should express the verified A. viridans LOx protein in E. coli.
- Expression should be controlled by a T7-compatible promoter and a bacterial ribosome binding site.
- The protein should include a purification handle so that it can be separated from other bacterial proteins.
- The LOx amino-acid sequence should remain identical to the natural reference, apart from the deliberately added purification tag and linker.
- The DNA should include a terminator and an E. coli plasmid backbone for propagation and selection.
- The final sequence should be checked for reading-frame errors, unexpected stop codons, identity to the reference protein, and biosecurity flags.
These requirements explain why each part is present and provide criteria for checking whether the digital construct matches the intended biological function.
3. Parts in the final construct
Coordinates below are 1-based and inclusive in the final GenBank export. All five top-level parts were placed in the forward orientation. The imported backbone contains its own internal features; those features are not additional pieces inserted between the five parts listed here.
| Position | Kernel part / type | Length | Function and design reason |
|---|---|---|---|
| 1–69 | T7-lacO-promoter-K2406020 / Promoter | 69 bp | Starts T7-driven transcription and includes a lac operator for repression. It requires appropriate host machinery, including T7 RNA polymerase. |
| 70–84 | T7-RBS-7nt-spacer / Ribosome binding site | 15 bp | Recruits the bacterial ribosome and creates spacing between the RBS and start codon. |
| 85–1242 | His6-GSG-AvLOx-Ecoli-CDS / CDS with upstream tag | 1,158 bp | Encodes the N-terminal purification tag, short linker, complete LOx protein, start codon, and two terminal stop codons. |
| 1243–1290 | BBa_K923004 / Terminator | 48 bp | Provides a defined end to the intended T7 transcript. |
| 1291–3360 | pSB1C3 / Backbone | 2,070 bp | Provides plasmid replication and chloramphenicol selection in E. coli. |
Promoter
The promoter sequence comes from BBa_K2406020. Kernel’s library labeled the record as “Miscellaneous,” so I created a sequence-identical project copy with the correct Promoter type. Kernel detected that the sequence already existed, which helped confirm that I had not accidentally changed it.
This promoter was chosen because the planned BL21(DE3) host can supply T7 RNA polymerase. The lac operator offers a possible layer of repression, but repression should not be assumed to be perfect. Host genotype, LacI availability, culture conditions, and plasmid copy number can all influence background expression.
Ribosome binding site and spacer
The translation-start region uses GAAGGAGA from BBa_K2906017, followed by the selected seven-base spacer TATACAT.
The RBS helps the bacterial ribosome find the transcript, while the spacer places the start codon at a usable distance from the RBS. The combined sequence also matched the existing Kernel registry part BBa_K3096000, so it is not claimed as a new sequence. Its actual expression strength was not computationally predicted or experimentally measured; the presence of an RBS alone does not guarantee an optimal protein yield.
Coding sequence and purification tag
The final coding sequence begins with a designed 30-base N-terminal extension:
This sequence encodes MHHHHHHGSG. The six histidines form a proposed affinity-purification handle, and GSG is a short flexible linker intended to separate that handle from LOx. The complete original LOx protein follows the linker, including LOx’s own starting methionine. The final fusion is therefore 384 amino acids long: 10 added residues plus the 374-amino-acid LOx reference protein.
The tag makes purification easier in principle, but it is still a design hypothesis. Even a short tag can affect protein folding, oligomerization, FMN binding, catalytic activity, or stability. A tagged-versus-untagged activity comparison is therefore one of the most important follow-up experiments. The tag extension itself was not codon-optimized separately.
Terminator
The terminator is BBa_K923004, a T7 terminator sourced from pET14b.
The terminator helps define the end of the transcript and reduces transcription into downstream plasmid sequence. I verified the part identity in Kernel because BBa_K923004 is not the same part as BBa_B0011, even though both may appear in general terminator searches.
Backbone
The backbone is pSB1C3, a high-copy BioBrick plasmid containing a pUC/pMB1-type origin and chloramphenicol resistance. Its purpose is to allow the circular DNA to be maintained and selected in E. coli. Background on BioBrick/Golden Gate engineering is available in iGEM’s engineering documentation, and plasmid copy number and expression burden are discussed in this primary study.
This is a simple teaching prototype, not a pET vector and not an optimized manufacturing backbone. A high-copy plasmid combined with strong T7 expression may produce metabolic burden, leaky expression, or instability. I did not add an extra plasmid-borne lacI cassette, so host LacI availability and actual repression would need to be checked before laboratory use.
4. Step-by-step Kernel workflow
Step 1: establish a traceable native reference
I began with the GenBank nucleotide record and confirmed that its translation matched UniProt Q44467. This created a reference pair: one verified DNA sequence and one verified protein sequence. Keeping that native reference separate made it possible to check later whether optimization changed the protein.
Step 2: codon-optimize the LOx gene for E. coli
I ran Kernel’s codon optimizer as AvLOx-D50611-Ecoli-HW2. The input was the native LOx DNA, the selected host was Escherichia coli, the optimizer was SIMPLE_0_3, and the preset was None. I did not specify restriction-enzyme exclusions, CpG avoidance, or a signal peptide. The saved result is available here: Kernel codon-optimizer result.
The native CDS was 1,125 bp, including one stop codon. The optimized untagged output was 1,128 bp, including two terminal stop codons. Across the 1,122 protein-coding bases, excluding stops, optimization introduced 258 nucleotide substitutions. Whole-CDS GC content changed from 41.511% to 43.794%.
Codon optimization changes synonymous DNA codons while preserving the amino-acid sequence. The goal is to make the gene more compatible with the host’s translation machinery, but an optimized sequence does not automatically produce more soluble or active protein. Kernel reported N/A, rather than a numeric value, for both codon usage index and RNA structure score, so those metrics should not be invented or interpreted as successful scores.
Step 3: add the purification extension
I placed the His6-GSG sequence immediately upstream of the optimized LOx coding sequence and kept the reading frame continuous. I then checked that the combined CDS began with ATG, had a length divisible by three, and ended with the intended TGA–TAA stop sequence. This step matters because a single missing or extra nucleotide at the junction would shift the reading frame and change every downstream amino acid.
Step 4: assemble the expression cassette and plasmid
The biological order is:
T7-lacO promoter → RBS/spacer → His6-GSG-LOx CDS → T7 terminator → pSB1C3 backbone
The expression cassette is 1,290 bp, and the backbone is 2,070 bp, giving a total circular construct length of 3,360 bp.
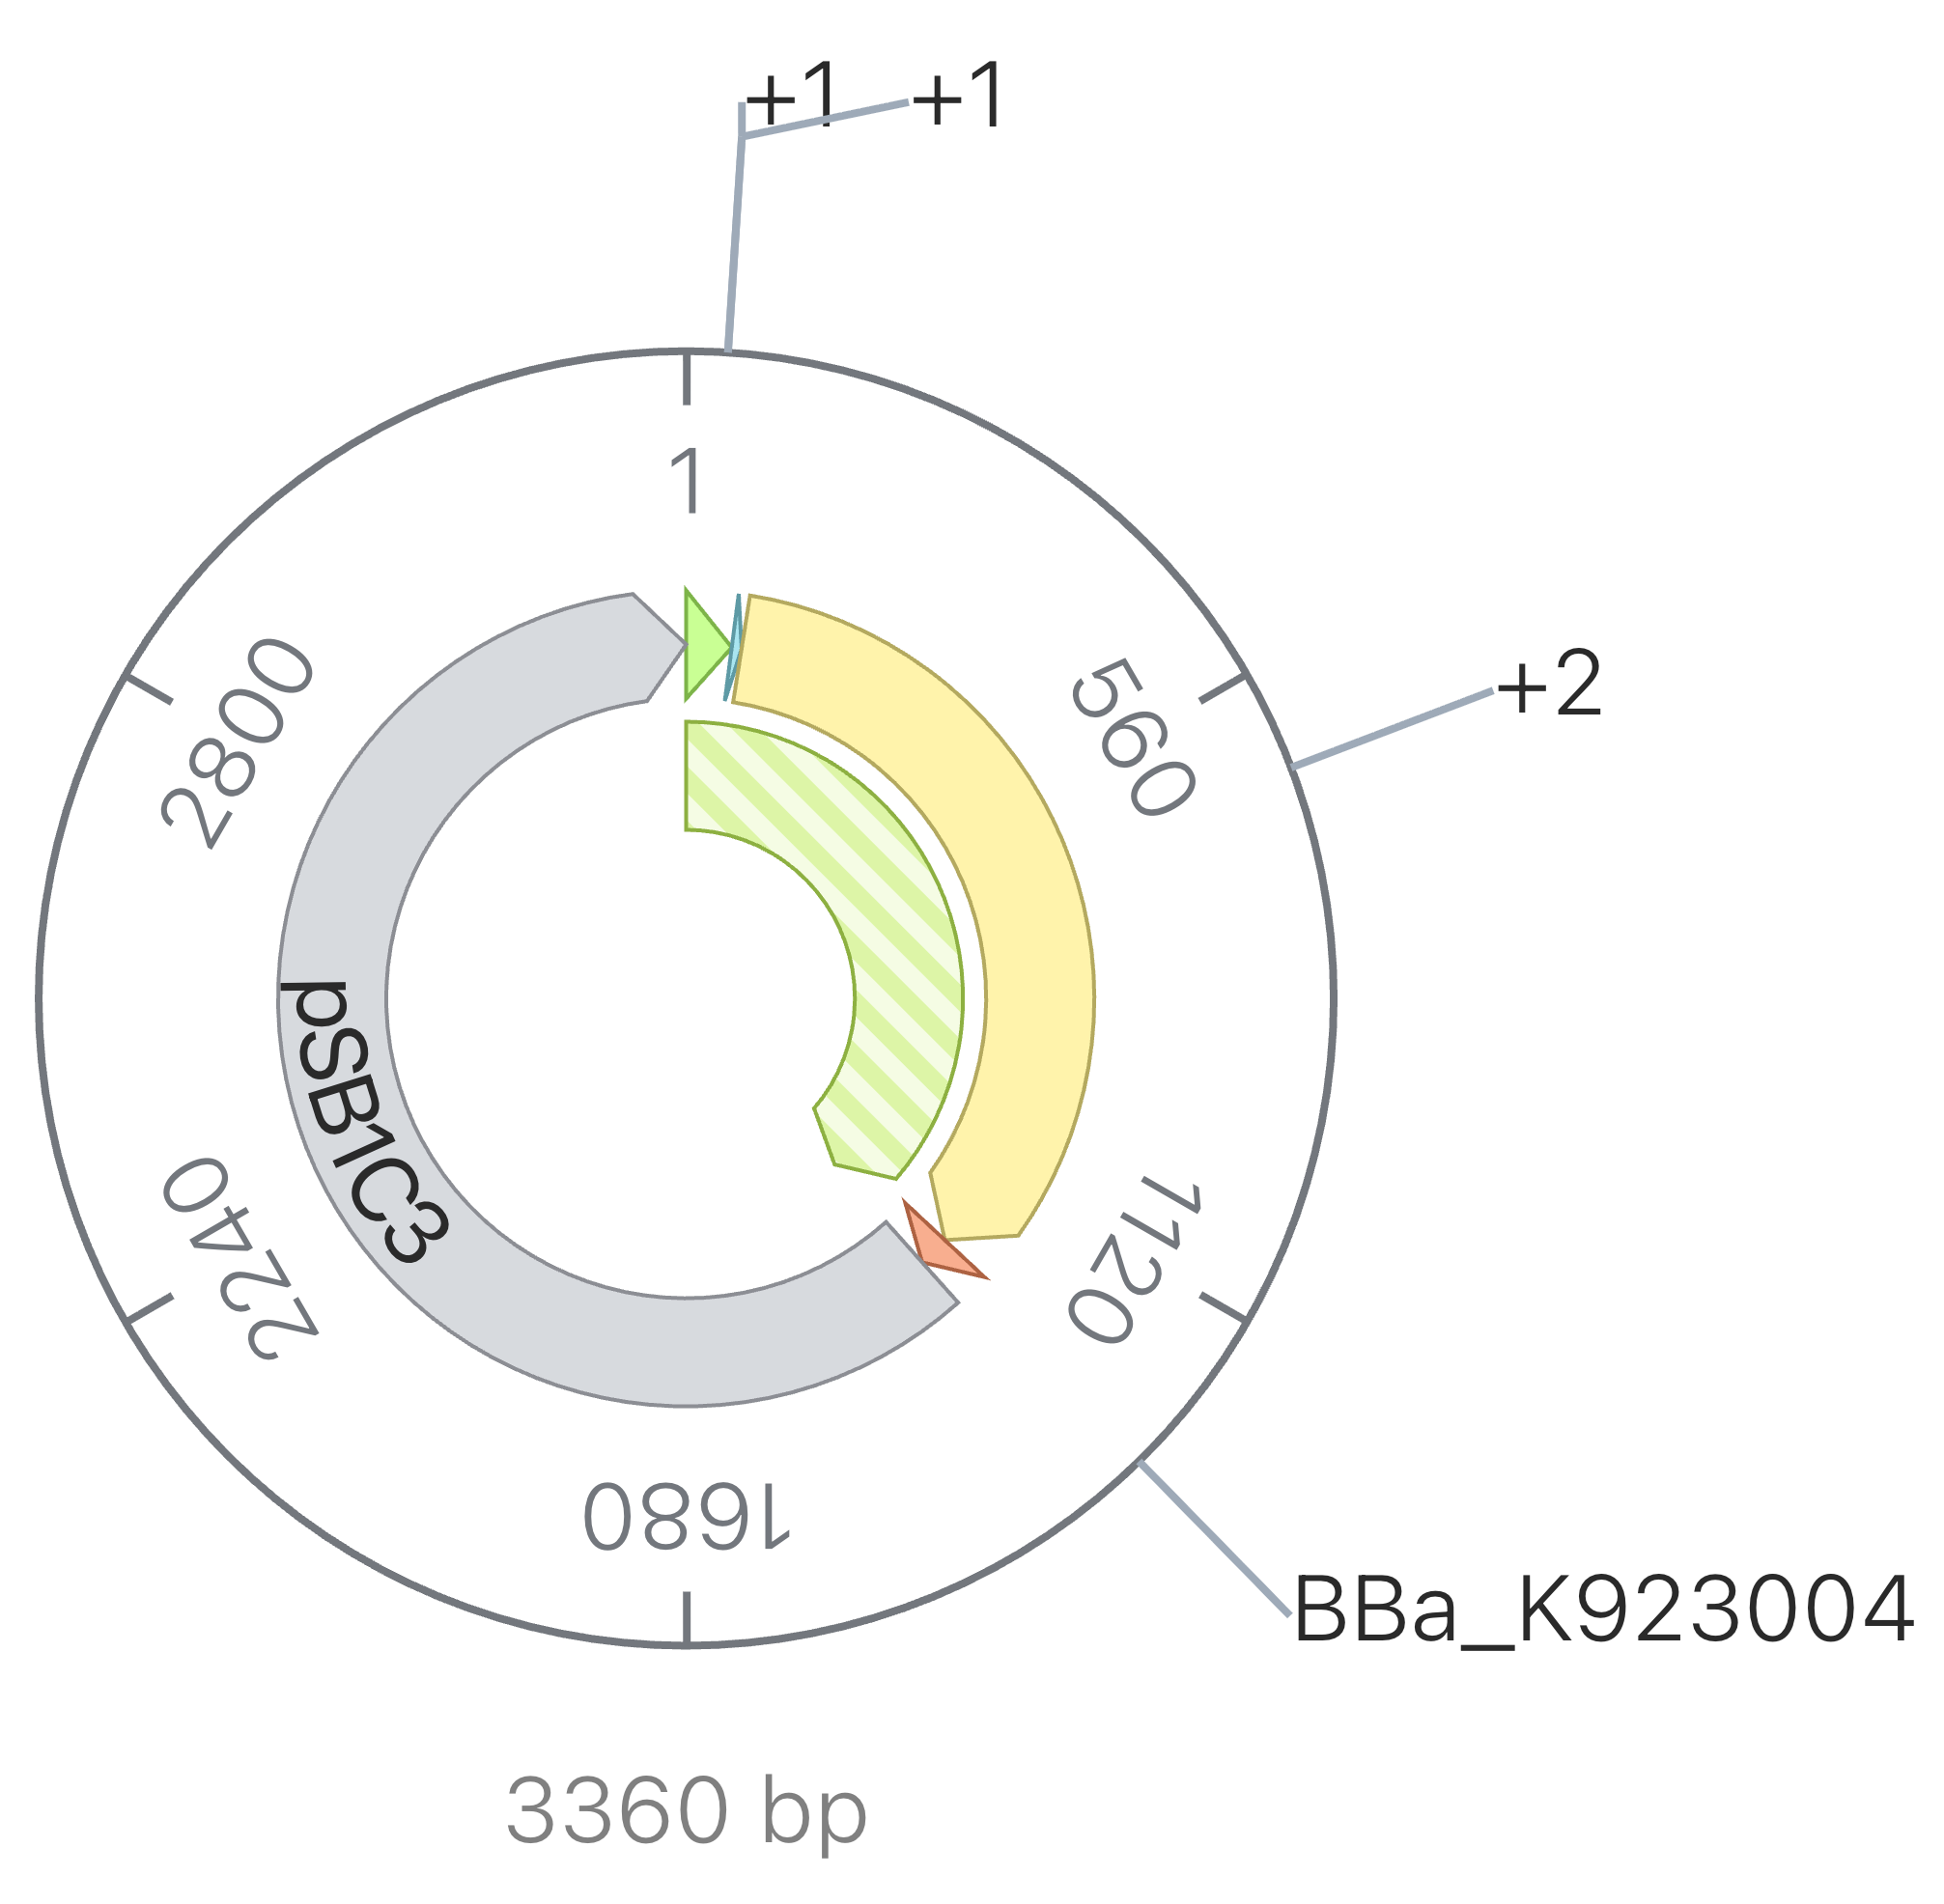
In the circular map, the gray arc is the backbone, the large yellow arc is the tagged LOx gene, and the inner green arc is Kernel’s inferred transcription-unit annotation rather than an extra DNA part. The raw exported image uses a transparent background and compresses crowded labels into “+1” and “+2,” so the coordinate table above is the reliable legend.

Step 5: verify sequence integrity and protein identity
Kernel showed 0 errors and 0 warnings after assembly. I also checked the exported sequence independently. The checks confirmed that:
- the final construct is 3,360 bp;
- the tagged CDS is 1,158 bp and begins with ATG;
- translation produces 384 amino acids followed by the two intended stop codons;
- there are no internal stop codons;
- the 374-amino-acid LOx domain is unchanged from the verified native reference; and
- all part lengths and junction coordinates match the intended order.
Kernel’s GenBank translation qualifier displays two trailing asterisks. Those asterisks represent the two terminal stop codons; they are not extra amino acids. The protein FASTA provided below omits them.
Kernel pairwise alignment of native and optimized LOx returned 374/374 matches, 100.00% identity, zero mismatches, zero insertions, and zero deletions. This confirms that synonymous recoding did not alter the protein sequence, but it is a pairwise comparison rather than a database search.
I therefore also ran NCBI BLASTP against Swiss-Prot using the actual optimized 374-amino-acid LOx domain and excluding the artificial tag. The top match was Q44467.1, L-lactate oxidase from Aerococcus viridans ATCC 11563, with 100% query coverage, 100.00% identity, E-value 0.0, and score 770. The temporary result was saved under RID BPUMBBN1016, although BLAST RIDs can expire.
Together, the pairwise alignment and BLAST result support two different conclusions: the optimized gene still translates to the intended reference protein, and that protein is a known natural lactate oxidase rather than a newly invented protein variant. The final tagged fusion is different from the untagged natural protein only because of its deliberate N-terminal purification extension.
Step 6: run a biosecurity sequence screen
Kernel’s Biosecurity sequence scanner describes using SecureDNA to compare nucleotide sequences with a database of potential biosecurity threats while protecting the submitted sequence cryptographically. I first screened the expression cassette and then repeated the screen on the entire 3,360-bp construct, including the backbone. Both runs returned “No flagged sequences detected.”
This result means that the tool did not report a flagged match for those submitted sequences. It is not a general certification of biological safety, antibiotic-marker acceptability, environmental safety, skin safety, or clinical usefulness. Laboratory handling, institutional biosafety review, waste disposal, strain choice, and product testing remain separate responsibilities. A sequence should never be changed simply to evade a screening result; an unexpected flag should instead be reviewed with an instructor or biosafety professional.
5. From digital design to a physical build
For a first prototype, I would propose ordering a sequence-verified synthetic 1.3-kb expression cassette and joining it to a verified, linearized pSB1C3 backbone using overlap-based assembly. This keeps the functional cassette as one traceable fragment and is simpler for this single design than managing a large oligonucleotide pool. Exact primer and overlap sequences have not been finalized; when they are designed, they must preserve every junction in the coordinate table and avoid duplicating vector sequence.
Gibson et al. (2009) describes assembling overlapping DNA fragments using coordinated exonuclease, polymerase, and ligase activities. That mechanism supports a cassette-plus-backbone strategy without requiring a restriction site at every junction.
The final construct has approximately 46.0% overall GC content, but an acceptable average GC percentage is not enough to guarantee easy synthesis. The sequence also contains short repeated histidine-tag codons, a structured terminator, and an eight-adenine homopolymer. A DNA supplier should evaluate local sequence context, repeats, and secondary-structure risk. If necessary, the cassette could be divided into smaller sequence-verified fragments, but functional regulatory parts should not be rewritten casually.
Carr et al. (2004) demonstrated MutS mismatch binding as a method to reduce errors in synthesized DNA. The practical lesson for this project is that a correct digital file does not guarantee a correct physical molecule. Vendor quality control and sequencing of the assembled plasmid are still necessary. The historical error rates in that paper are not assumed to represent a current commercial supplier.
A reasonable laboratory validation sequence would be:
- assemble the plasmid and transform an appropriate cloning or expression strain;
- confirm the recovered plasmid by sequencing across all functional junctions and the complete LOx CDS;
- test small-scale expression under more than one induction condition;
- separate soluble and insoluble protein fractions;
- purify the His-tagged protein and verify its apparent size;
- measure LOx activity with lactate standards and appropriate negative controls; and
- test the purified enzyme after immobilization on the planned electrode material.
At larger scale, a new plasmid would not be synthesized for every patch. After a construct and production strain were validated, controlled cell banks and fermentation would supply enzyme batches, followed by purification, activity testing, immobilization, and sensor quality control. A manufacturing version may need a lower-copy backbone, tighter expression control, or an alternative selection system.
6. The three largest unresolved questions
| Question | Why it matters | What I would measure next |
|---|---|---|
| Does this expression architecture produce soluble, active LOx without excessive burden or leakage? | A correct sequence can still yield insoluble protein, poor growth, or low activity. | Compare native and optimized genes; measure growth, total and soluble protein yield, and enzyme activity; compare against a lower-copy or established expression-vector version. |
| Does the His6-GSG extension preserve folding, FMN-dependent activity, and useful stability? | The tag helps purification but may interfere with the enzyme. | Compare tagged and untagged LOx using lactate standards; assess cofactor-dependent activity and retained activity after storage and immobilization. |
| Does the enzyme work reliably in the intended sweat patch? | Performance in purified buffer may not translate to sweat or a wearable electrode. | Measure calibration, response time, drift, oxygen dependence, and interference across relevant pH, temperature, and artificial-sweat conditions. Validate any physiological interpretation separately. |
7. How I would explain the project aloud
I designed DNA to manufacture the enzyme component of a sweat-lactate sensor. The bacteria are the production factory, not part of the wearable. A T7 promoter and ribosome binding site control production of tagged lactate oxidase; a terminator ends the transcript, and a plasmid backbone maintains the DNA in E. coli. I verified the source sequence, optimized the DNA for the host, checked that the protein sequence stayed unchanged, confirmed its identity with BLAST, and screened the full construct. The next questions are whether the construct produces enough soluble, active enzyme and whether the immobilized enzyme gives a reliable signal in sweat. I am not yet claiming that this design predicts injury.
8. AI assistance and limitations
AI clients used: OpenAI Codex and Kernel AI.
Kernel AI was asked to help identify parts and an assembly approach for cytoplasmic, tagged A. viridans LOx production in E. coli. The description here summarizes those interactions rather than reproducing a verbatim transcript; the Kernel conversation should be preserved if exact wording is required. Suggested parts were checked against the actual Kernel library records and primary sequence databases. Inappropriate backbone or terminator suggestions were not accepted.
AI-generated claims about expression, purification, sensing performance, or commercialization remain hypotheses unless experimentally tested. No DNA was ordered, no wet-lab experiment was performed, and no assignment was submitted automatically. The existing project name and work were preserved.
Downloadable project files
- Final annotated GenBank construct
- Complete 3,360-bp construct FASTA
- Verified native LOx CDS
- Codon-optimized untagged LOx CDS
- His6-GSG-tagged LOx CDS
- His6-GSG-tagged LOx protein FASTA
- Independent sequence-check calculations
- Kernel circular map
- Kernel schematic
The GenBank and FASTA files contain the complete sequences. This explanatory page is not a substitute for a final sequence review, manufacturability check, biosafety review, or experimental protocol.