Week 2 HW: DNA Design
 Obs.: Since i’m really new to the world of genetic engineering and never had any strong prior experience, i used AI to help me during the entire proccess. ChatGPT helped me on how to create the cassete and construct, and Claude (Anthrophic) was used to give me a “script” to follow, aside from help on what to analyse and how to write.
1. Defining My Expression Target
What Molecule Are You Expressing
I will express a gene responsible for the production of CAHS 8 protein on E. coli.
What is the sequence?
The protein aminoacid sequence code is:
MSGRNVESHMERNEKVVVNNSGHADVKKQQQQVEHTEFTHTEVKAPLIHPAPPIISTGAAGLAEEIVGQGFTASAARISGGTAEIHLQPSAAMTEEARRDQERYRQEQESIAKQQEREMEKKTEAYRKTAEAEAEKIRKELEKQHARDVEFRKDLIESTIDRQKREVDLEAKMAKRELDREGQLAKEALERSRLATNVEVNFDSAAGHTVSGGTTVSTSDKMEIKRN
with the accession code P0CU50 on Uniprot, although i had to back translate it to a DNA sequence:
ATGTCCGGCCGTAACGTTGAGTCCCATATGGAACGTAATGAAAAAGTGGTGGTAAACAACTCAGGGCATGCAGATGTCAAAAAACAGCAGCAGCAAGTGGAGCATACCGAGTTTACCCATACTGAAGTGAAAGCACCGCTAATTCACCCTGCCCCCCCAATCATTAGTACAGGTGCGGCGGGTCTGGCAGAGGAAATTGTTGGCCAGGGCTTTACGGCGAGCGCCGCCAGAATCAGCGGTGGCACCGCAGAAATTCACTTGCAGCCGAGCGCCGCCATGACTGAGGAAGCTCGGCGCGACCAGGAGCGCTACCGACAAGAACAAGAAAGTATTGCAAAACAGCAAGAACGCGAAATGGAGAAAAAAACCGAAGCGTATCGCAAGACCGCTGAGGCGGAAGCGGAAAAAATCCGTAAAGAACTTGAGAAACAACATGCGCGTGATGTGGAATTCCGGAAAGACCTGATAGAGTCAACGATCGATCGTCAGAAACGCGAAGTTGATCTCGAAGCCAAGATGGCTAAACGCGAATTAGACCGTGAAGGGCAGCTGGCGAAGGAAGCGCTGGAACGTTCGAGGCTGGCAACGAATGTCGAAGTCAACTTCGATTCTGCCGCTGGCCACACGGTATCTGGAGGTACTACAGTTTCGACCAGCGATAAGATGGAGATTAAACGCAAT
where a stop codon “TAA” was put in the end of the sequence by me. The sequence has been codon-optimized for E. Coli too
What host or chassis?
The host and chassis will be E. Coli
Where does the product need to go?
The product is, in the moment, mean to be intracelular (Although i may or not change this later), so the target location for now is the citosol, and no signal peptide is needed. The reason for this is that the idea, in the moment, is that the E. coli will work as a “mini factory”, producing CAHS 8 all the time, for then it be extracted. (But, as i said: This may or not change in the future)
2. Design Of My Genetic Parts
| Layer | Prokaryotic host (E. coli) | Justification |
|---|---|---|
| Transcription Start | BBa_J23108 (Promoter) | It’ a medium-strength constitutive promoter that will give a reliable continuous expression. |
| Translation Start | BBa_BOO34 (Ribosome Binding Site) | It’s a well-characterized RBS that is commonly paired with constitutive promoters in BioBrick-based designs. |
| Coding Sequence | CAHS D / CAHS 94063 | Will encode the tardigrade protein associated with desiccation tolerance. |
| Transcription Stop | BBa_B0015 (Terminator) | A double terminator will give a more reliable transcript end than a single terminator. Aside from being a standard choice in BioBrick cassette design. |
| Backbone | Psb1c3 | Standard empty BioBrick vector (ColE1-type origin, chloramphenicol resistance). Chloramphenicol is gonna be used as the selection marker because it’s what pSB1C3 already carries. |
3. Assembling My Construct
The genetic cassette was primarly assembled in Benchling (due to the fact that the kernel access was conceived only later on) in the 5’-3’ order of promoter, RBS, CAHS D coding sequence, and transcription terminator. The CAHS D CDS contains a start codon and a stop codon (Added by me). The orientation of the genetic parts was checked to ensure that the cassette follows the transcriptional and translational architecture for expression in E. coli. Later on the cassete was imported into Kernel.
 Schematic of the cassete
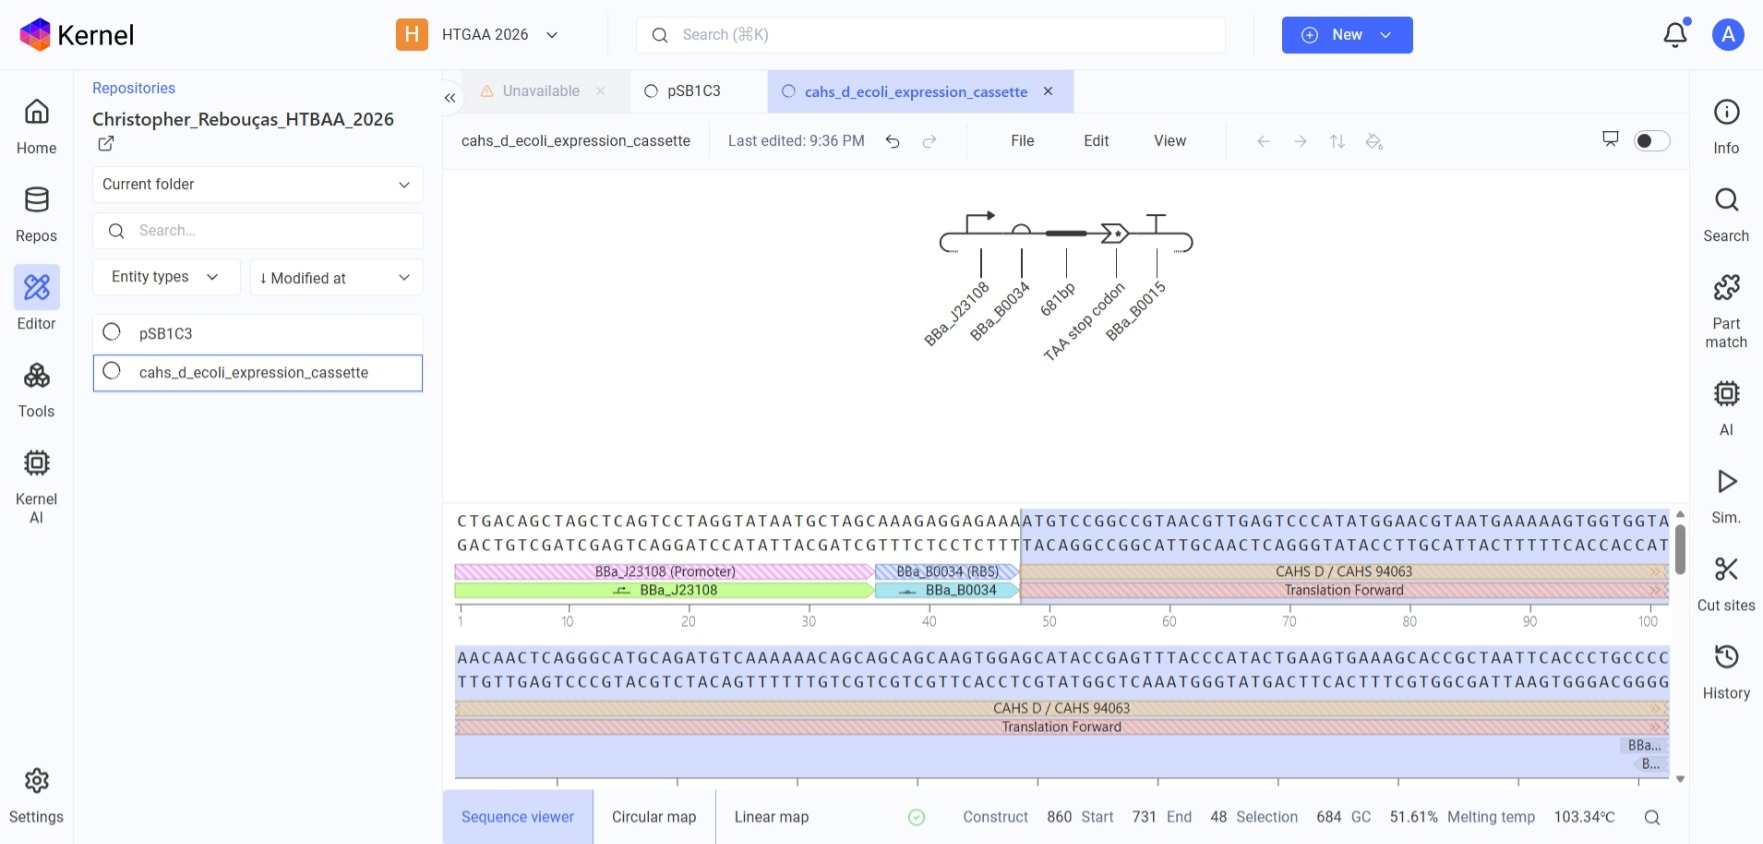 Cassete imported into Kernel
The construct was build later on, using the plasmid pSB1C3 as the backbone, wwhere the cassete was inserted between the biobrick preffix and biobrick suffix. This step was made in Benchling too and later on imported into Kernel.
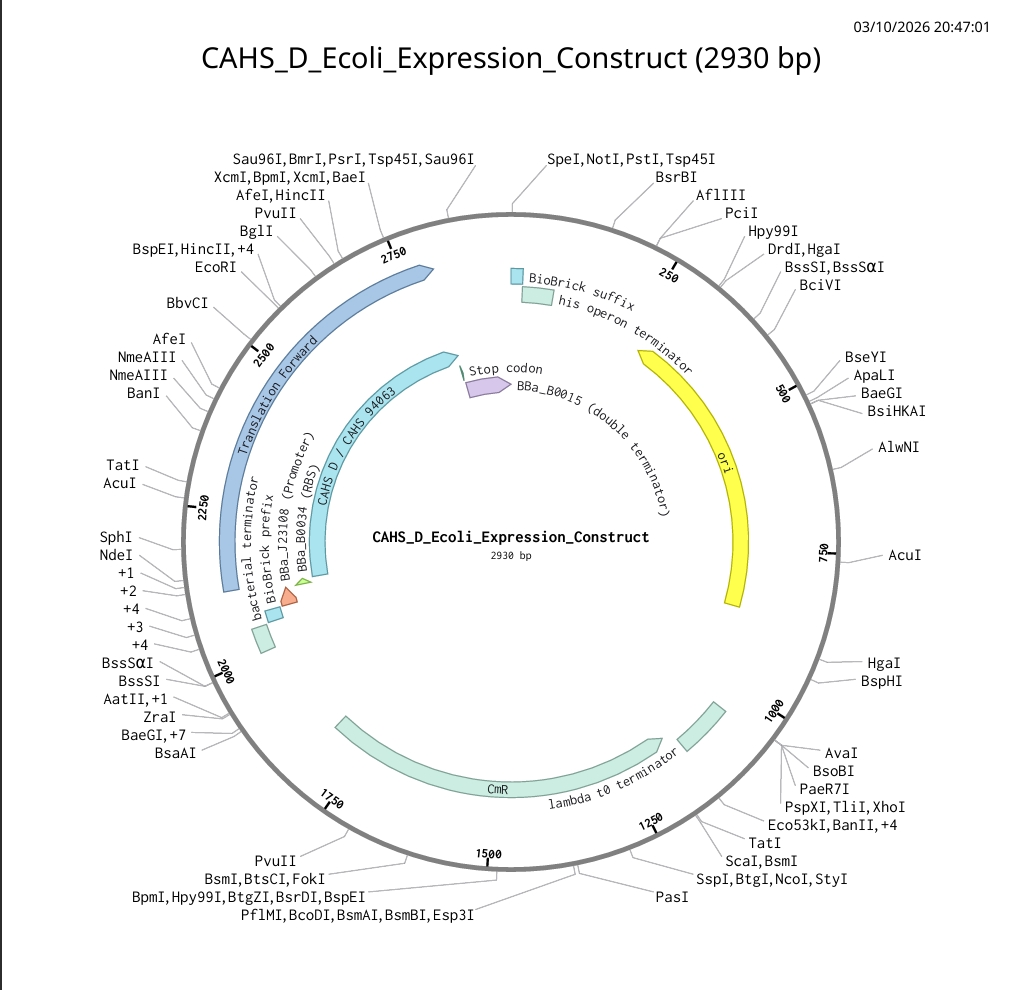 Construct schematic given by benchling
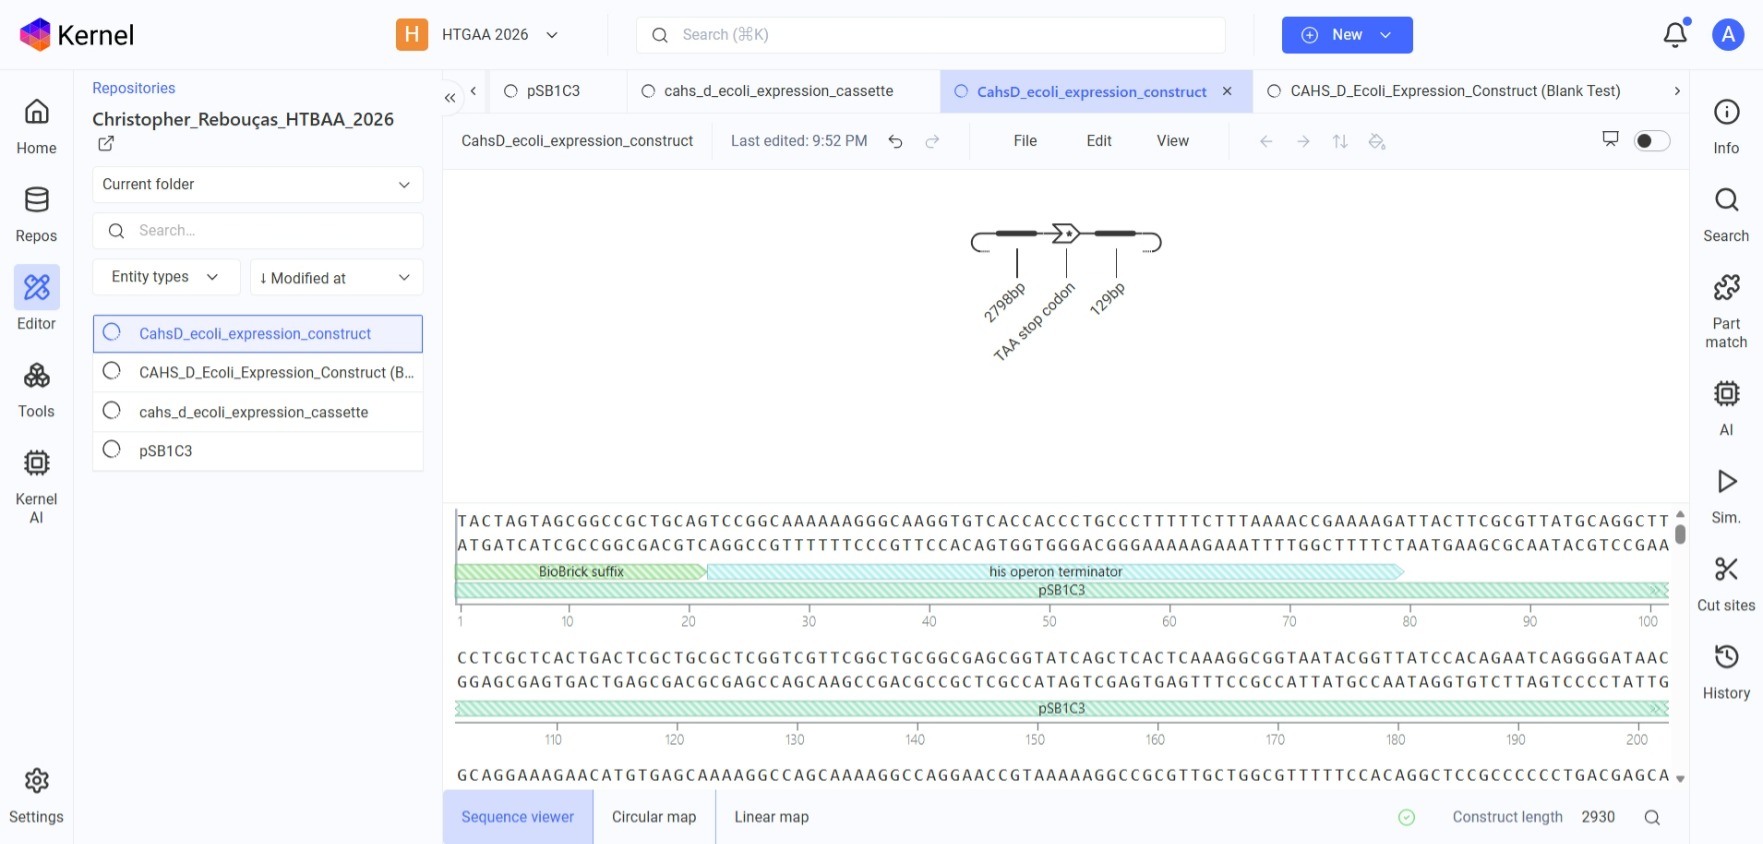 Construct imported into Kernel (Obs.: Since it was my first time accessing Kernel and i didn’t knew how much on how to use it and the Kernel AI wasn’t working properly, i didn’t knew why the construct schematic stayed kinda messy on the software)
4. Optimization And Quality Check
The CAHS 8 CDS was blasted using blastx to confirm the translated sequence was correct and able to syntesize the CAHS 8 protein
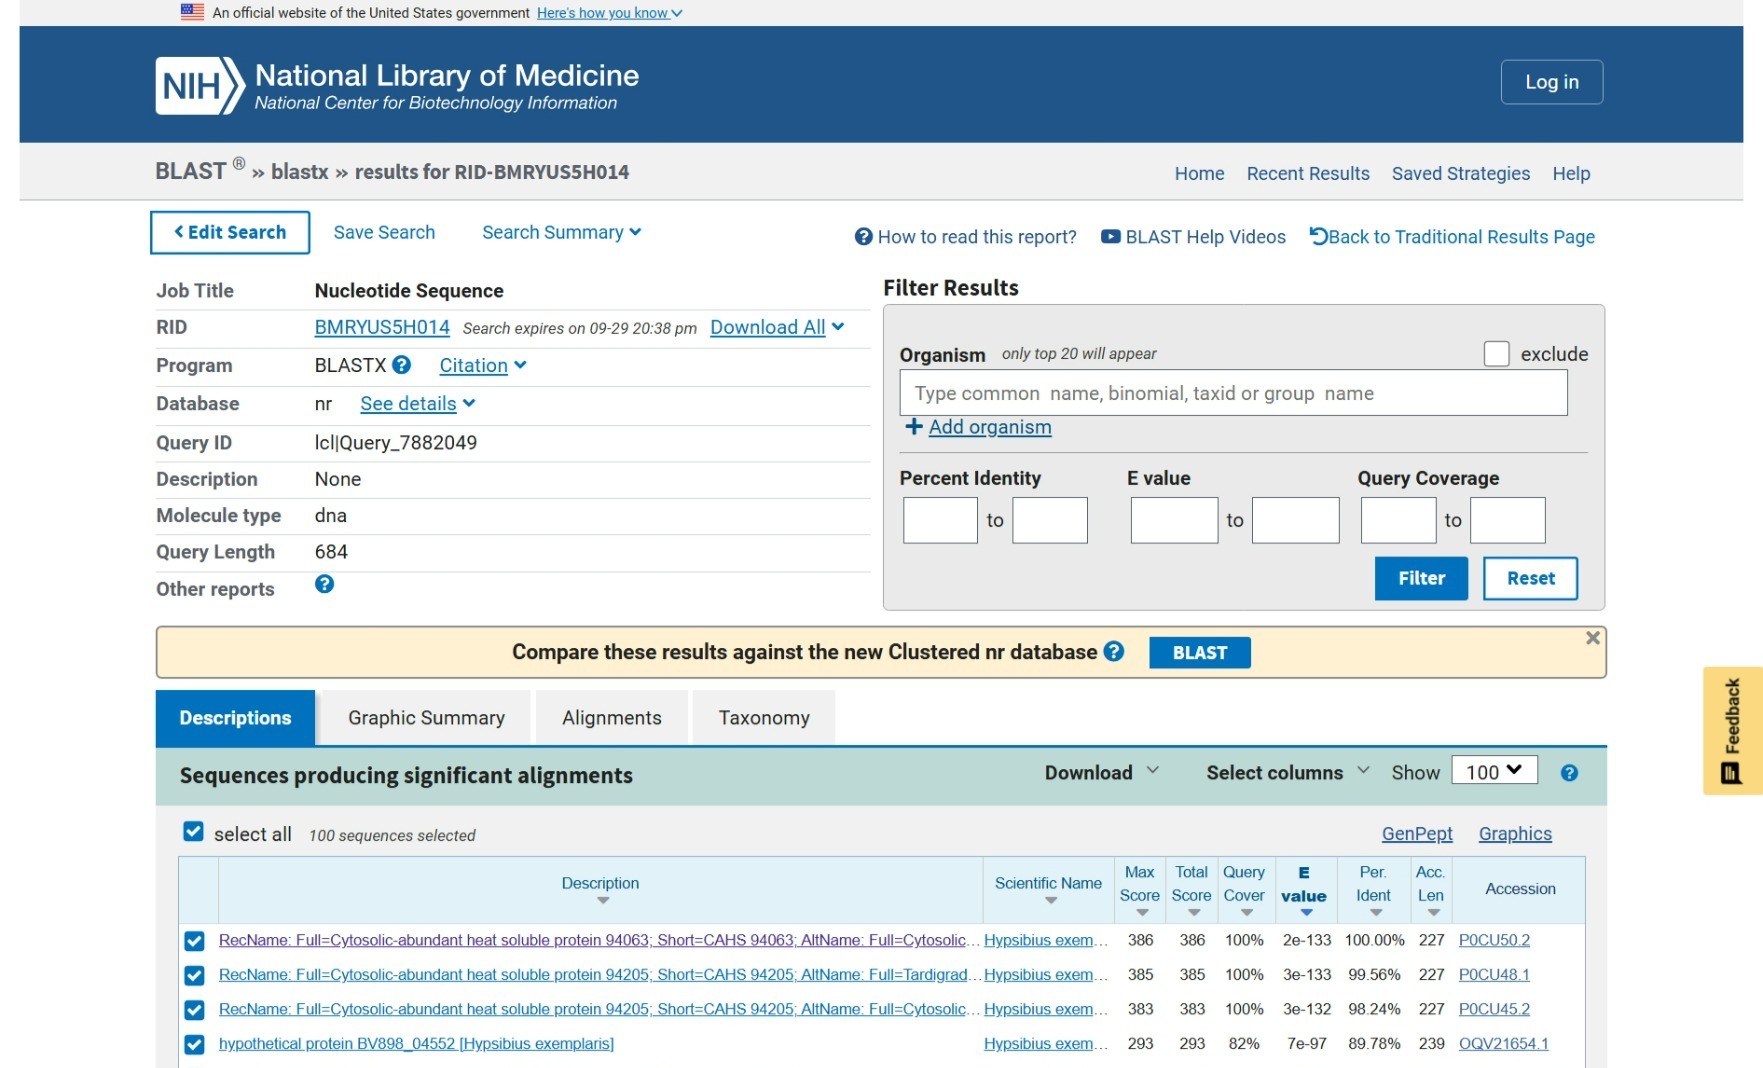
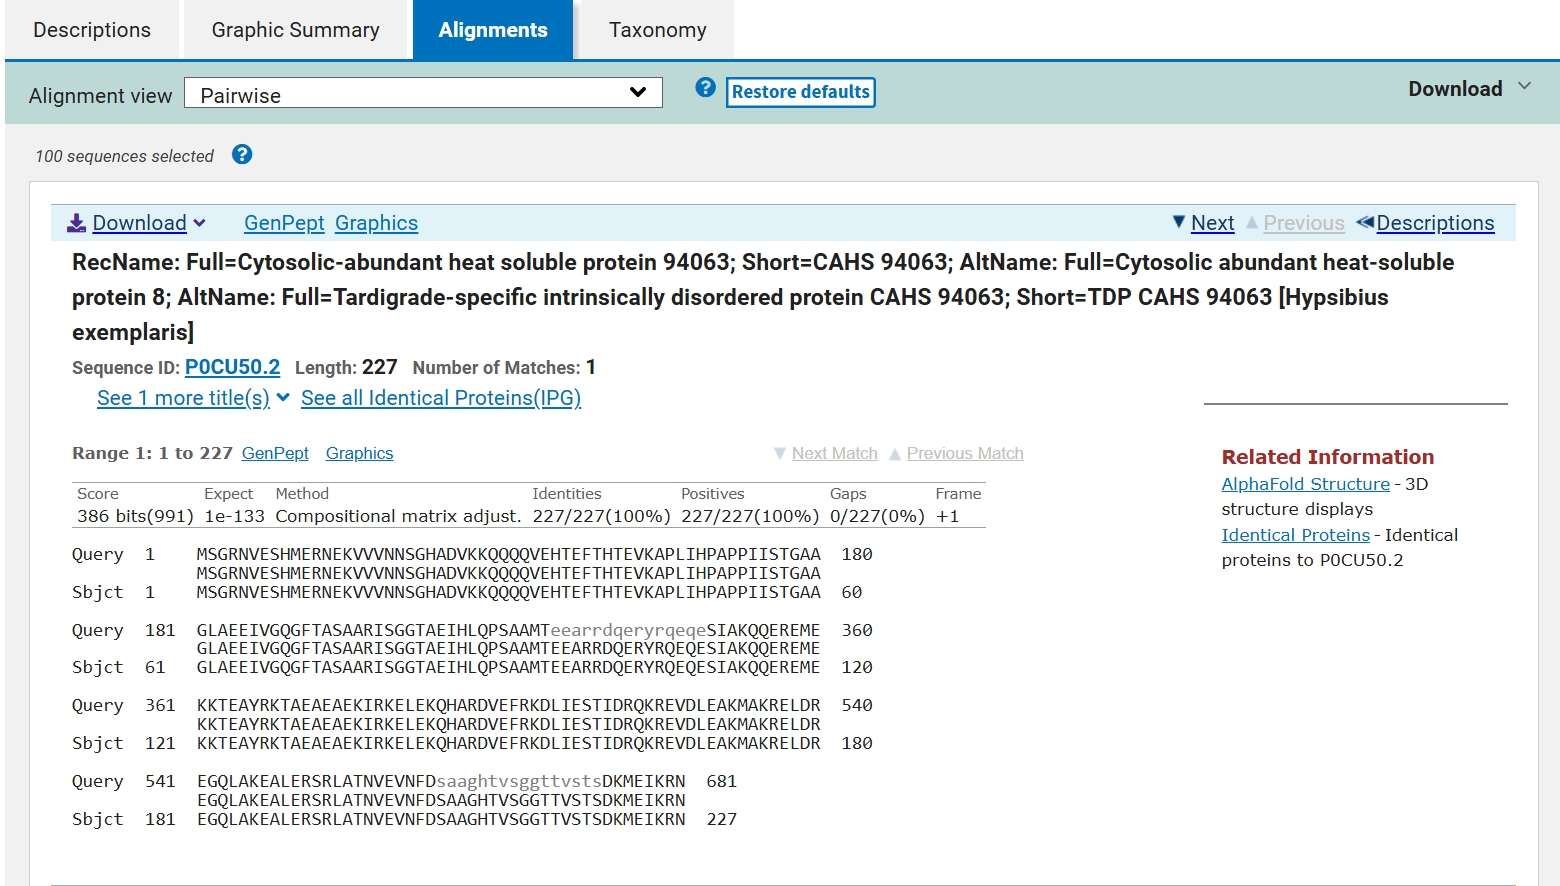 Blastx results screenshot
Later on the Safety Screening was runned in Kernel
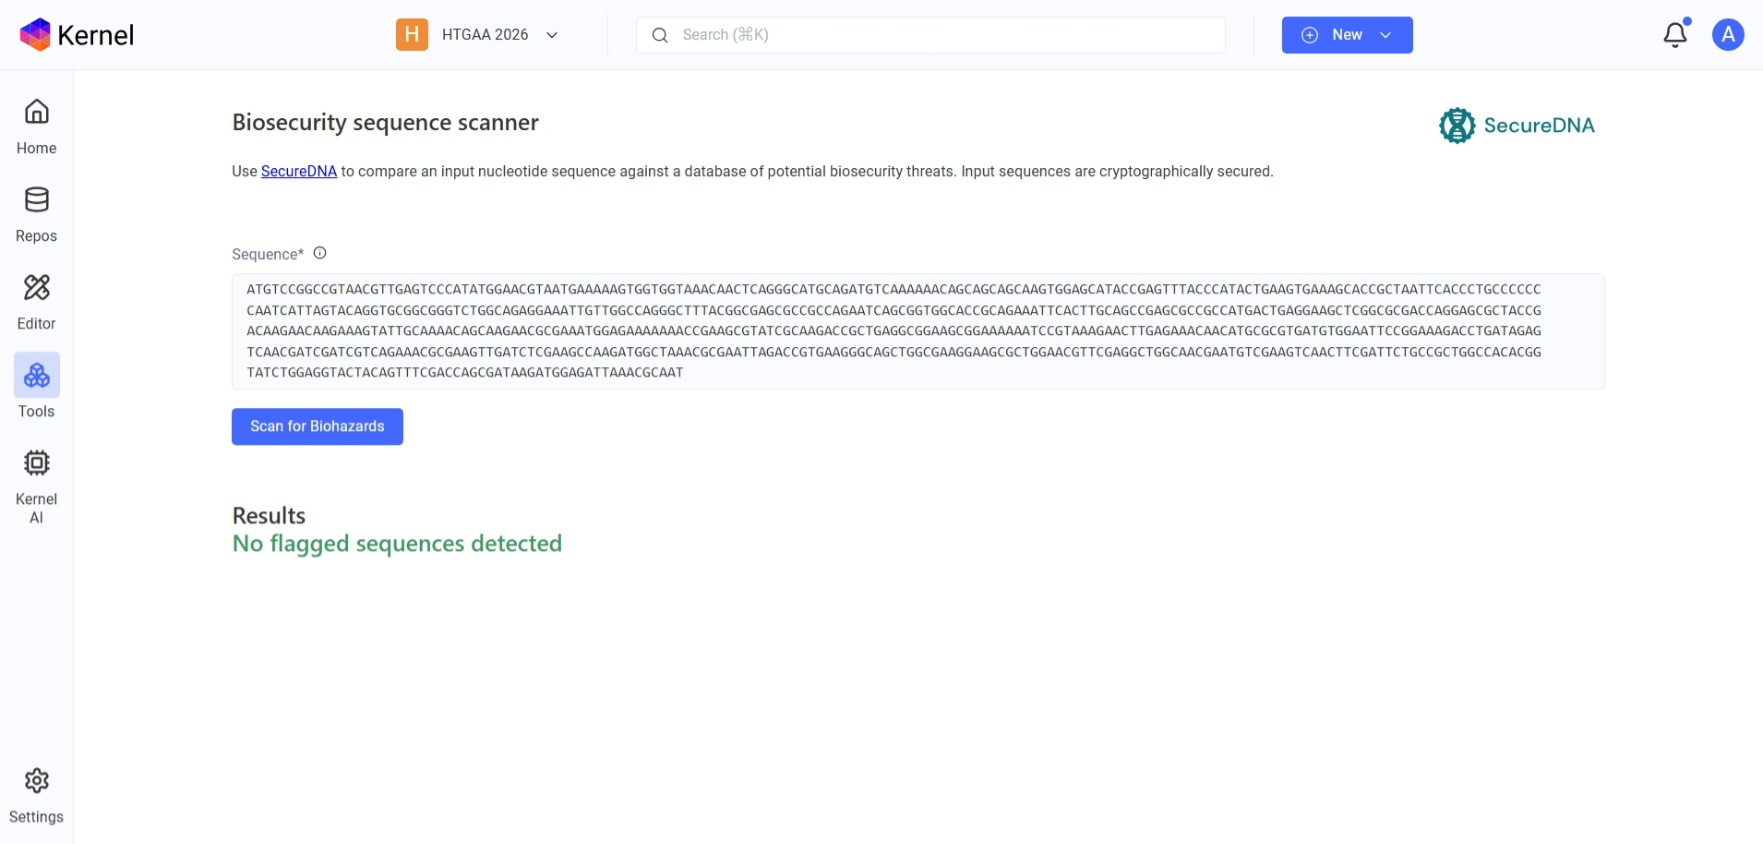 Safety Screening results in Kernel
5. From Design To Build
How i’d build?
For an initial prototype, i would order the ~860 bp cassete as synthetic DNA and assemble it with the pSB1C3, since my construct is relatively simple.
What does synthesis constrain?
Prototype vs Scale
For the first prototype the goal is to achieve a verified construct and have the confirmation that CAHS 8 is being produced in E. coli. While in production scale the main goal is reproducibility at large scale
6. What i don’t know yet?
Will CAHS D be properly expressed and syntesized in E. coli?
Since CAHS D is native to a very different organism and codon optimization doesn’t guarantee correct folding, there will be a need to test the protein production and stability
Must be more things to be analysed
As i said, since i’m really new to the world of genetic engineering and i’m still learning, must be much more topics to cover and much more thing to analyse