Wolf B, Mathony J, Niopek D. Bioswitches: Towards programmable, on-demand control of therapeutic proteins. Clin Transl Med. 2026 Feb;16(2):e70612. doi: 10.1002/ctm2.70612. PMID: 41630504; PMCID: PMC12865224.
About me
My name is Jose Sanchez, 27. I’ve lived in the Rogers Park Area in Chicago with my wife for a few years and have loved it. I am passionate about citizen science, community and organizing. I graduated UChicago BA 2021 Biological Sciences. I currently work in the biotech space as a technical sales professional.
Fun fact: I share a birthday with Mario J. Molina Nobel Prize in Chemistry 1995
See the nav bar on the left to look through my work for How To
Biomanufacture Almost Anything (Fall 2026)!
Subsections of Jose Sanchez — HTBAA Fall 2026
Week 1 HW: Final Project Ideas
HTBAA Homework #1
(1) What I would like to biomanufacture and why
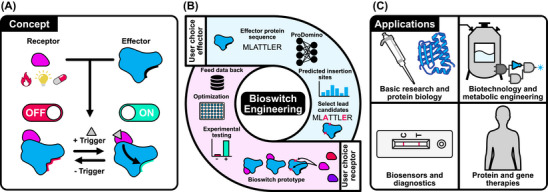
My long-term vision is an allosteric “Bioswitch” version of an immune checkpoint inhibitor: pembrolizumab (Keytruda) that can be turned off on demand using light, to address chronic immune-related adverse effects associated with checkpoint blockade therapy. As Wolf, Mathony, and Niopek (Heidelberg University) describe in their 2026 Clinical and Translational Medicine invited letter, “Bioswitches: Towards programmable, on-demand control of therapeutic proteins,” most protein therapeutics act continuously for as long as they remain in the body, and “adverse effects such as off-target activity and toxicity may arise in consequence of prolonged drug activity and are difficult to mitigate once a patient has received the therapeutic” [1]. A light-switchable checkpoint inhibitor could shut off the inhibitor if severe adverse effects are observed without waiting for the drug to clear naturally.
Cancer is a large global health burden: GLOBOCAN 2024 (IARC / American Cancer Society) estimates approximately 21 million new cancer cases and roughly 10 million deaths worldwide in 2024 [2]. Checkpoint inhibitors are among the most effective immunotherapies available, but their continuous immune activation can produce adverse effects.
This is a difficult, several year goal and I am not proposing to build the full therapeutic switch this semester. Instead, my project is to replicate and quantitatively extend a validated building block of this technology. A light-controlled protein switch in E. coli as a step toward eventually being able to design and calibrate controllable protein therapeutics.
(2) What living system would I use?
I would use E. coli as the chassis, replicating the CAT-LOV2 system described by Wolf et al. (Nature Methods, 2025) in their ProDomino paper [3]. CAT (chloramphenicol acetyltransferase) is an enzyme that inactivates the antibiotic chloramphenicol, conferring antibiotic resistance. In this construct, the AsLOV2 photoreceptor domain is inserted into a permissive surface loop of CAT — a site identified computationally by ProDomino, a published machine-learning tool for predicting domain-insertion sites — creating a fusion protein whose chloramphenicol-resistance activity is light-dependent.
E. coli transformed with a plasmid encoding the CAT-LOV2 fusion gene, grown in standard LB medium with chloramphenicol selection.
AsLOV2 adopts a conformation that allows CAT to fold and function, conferring resistance; under blue light, AsLOV2 undergoes a conformational change that disrupts CAT’s activity, acting as a light-triggered “off switch.” The original paper reports roughly a 20-fold difference in bacterial growth (by optical density) between dark and light conditions [3].
Results: quantitative, light-dose-dependent growth/survival signal (OD600 and colony counts) I can use to characterize the switch’s dynamic range and light sensitivity.
Assumption: the CAT-LOV2 construct (or one reconstructed from the published insertion site and linker sequences) is available or reproducible for this project.
(3) How would I use automation?
I would automate two parts of the workflow:
Design: ProDomino is open-source and publicly available. I would use it computationally, before any wet-lab work, to confirm the previously identified CAT insertion site and, time permitting, screen additional candidate sites not tested in the original paper [3].
Execution — the core of this semester’s contribution: I would use a desktop liquid-handling robot (e.g., an Opentrons) together with a programmable LED light array to run a parallel light-intensity dose-response experiment. The robot would dispense identical E. coli/CAT-LOV2 cultures across a 96-well plate; the LED array would expose different wells to a defined gradient of blue-light intensities, from darkness to a saturating high-intensity control; a plate reader would then automate OD600 measurement across all conditions simultaneously. This automates the parts of the workflow — precise, repeatable liquid handling and precise, repeatable light-dose delivery across many parallel conditions — that would be slow and error-prone to reproduce by hand.
(4) How much would I need to make, and how long would it take?
(a) How much
For this semester’s experiment, the relevant scale is the number of conditions needed for a statistically defensible dose-response curve. I would test 8–10 light intensities in triplicate, giving 24–30 cultures comfortably within one 96-well plate alongside blank and control wells.
For context on the longer-term therapeutic motivation (not this semester’s actual target): pembrolizumab is dosed at approximately 200 mg per session; assuming roughly 13 sessions per patient [4], that is about 2.6 g per patient. Scaled to a 500-person cohort study, that is approximately 1.3 kg of drug. Before that is animal studies to characterize the pharmacokinetics and safety of it, probably half — ~650g.
(b) How long
For the CAT-LOV2 dose-response experiment: E. coli grown from a dilute starting culture typically reaches saturating density in approximately 12–16 hours under standard conditions, so a full cycle — culture setup, overnight growth under the light-intensity gradient, next-day OD600/plate readout — is realistically a 1–2 day turnaround. With automation, this could be repeated across additional parameters (e.g., a linker-length variant) within the same week. To get it right I could see taking several weeks.
For the longer-term technology-development timeline: the original ProDomino model required approximately 6 months of training and validation to produce the results in the Nature Methods paper [3]. Extending and validating this approach on more complex target proteins would likely take 1–2 years of iterative work, and developing a validated switch for a specific oncology target (e.g., a checkpoint inhibitor) is more realistically a 5–6 year, PhD-scale research program. This semester’s project is a small, bounded first step within that timeline, not a replication of the full pipeline.
(5) What don’t I know yet?
Whether ProDomino’s predicted insertion site generalizes as reported, and how CAT-LOV2 behaves under a continuous light-dose gradient rather than the binary light/dark conditions tested in the original paper. I don’t yet know the exact AsLOV2 activation/saturation intensity thresholds for this specific construct (needs to be pulled from the ProDomino paper’s supplementary methods/data before finalizing the experimental light-intensity range — I have deliberately not guessed at precise mW/cm² values without that source).
Whether inserting a photoreceptor domain into a full-length antibody (the long-term pembrolizumab goal) preserves antigen binding and produces a controllable signal at all. This has not been demonstrated in any source I reviewed — every validated domain-insertion switch to date has been built in a smaller, structurally simpler effector (an enzyme, or Cas9/Cas12a), not a full immunoglobulin. This is the largest unresolved technical leap between this semester’s project and the long-term vision.
How light would actually be delivered to a systemically circulating drug in a living patient, if the long-term vision were pursued further. My E. coli dose-response system is entirely external-light-accessible in culture; an in vivo application would need to solve tissue-penetration and light-delivery problems this semester’s work does not address.
AI assistance disclosure: this proposal was developed through an extended conversation with Claude (Anthropic). I used it to check my understanding of the assigned readings and cited papers, stress-test and eliminate several earlier candidate ideas (an extremophile chassis platform, a non-GMO/allergen-free food enzyme, a non-thermal food-enzyme deactivation switch, a therapeutic peptide, and initially a therapeutic switch applied directly to pembrolizumab), correct factual errors in my draft (the institutional affiliation of the Bioswitches letter’s authors, and a conceptual error conflating CRISPR gene-editing with the standard molecular cloning actually used to build domain-insertion switches), and verify current global cancer statistics via web search. Target selection, scoping decisions, and final wording are my own.
Citations
[1] Wolf B, Mathony J, Niopek D. Bioswitches: Towards programmable, on-demand control of therapeutic proteins. Clin Transl Med. 2026 Feb;16(2):e70612. doi:10.1002/ctm2.70612. PMID: 41630504; PMCID: PMC12865224.
[3] Wolf B, Shehu P, Brenker L, von Bachmann AL, Kroell AS, Southern N, Holderbach S, Eigenmann J, Aschenbrenner S, Mathony J, Niopek D. Rational engineering of allosteric protein switches by in silico prediction of domain insertion sites. Nat Methods. 2025;22(8):1698–1706. doi:10.1038/s41592-025-02741-z.
In Homework #1 you proposed what to biomanufacture. In this assignment you design the DNA
that makes it, the actual genetic construct, using Kernel, Asimov’s computer-aided genetic
design software.
You will take the product and living system you proposed and turn them into a concrete
expression design: the biological parts, the assembled construct, and the sequence-level
decisions a lab would need to order and build it. Along the way you will run Kernel’s design tools
and reason about how your construct would actually be synthesized and assembled.
Your goal is to move from concept to sequence and to make, and defend, a real design choice
at each layer. You are not expected to produce a perfect, lab-ready plasmid. Where you have to
guess, guess reasonably and say so.
Part 0: Set up in Kernel
Get oriented in the software tool before you design anything.
Log in to Kernel and join the HTBAA 2026 workspace.
Create a repository for your project, and inside it a folder named for you and your
project, e.g. lastname-project.
Spend some time exploring: open an existing part and an existing construct and notice
the difference. Check out the different tools and ask Kernel AI some questions!
Deliverable for this part: a one-sentence note in your write-up with the name of your repository
and folder, so we can find your work.
Part 1: Define your expression target
Start from the project you proposed in Homework #1 and pin down exactly what your cells need
to make. Answer in your write-up:
● What molecule are you expressing? A protein, an RNA, or an enzyme (or small set of
enzymes) for a pathway. If your HW1 product is a material, food, or chemical, identify the
protein(s) that produce it and design for those.
● What is the sequence? Give the protein or RNA sequence, or the specific gene, you will
encode, and say where it comes from (a database accession such as UniProt or NCBI, a
known part, or de novo). Cite it.
● What host or chassis? The living system from HW1, for example E. coli, S. cerevisiae,
CHO or another mammalian line, or a cell-free system. Your host drives almost every part
choice that follows.
● Where does the product need to go? Cytoplasm, secreted, membrane, or a
compartment? This decides whether you need a signal peptide or targeting sequence.Part 2: Design your genetic parts
Every construct is built from parts. Decide which parts your target needs, then create or import
each one in Kernel with the correct part type. At minimum, choose the elements below for your
host.
Layer Prokaryotic host
(e.g. E. coli)
Eukaryotic host (e.g.
yeast, CHO)
What you’re
choosing
Transcription start Promoter (constitutive
or inducible)
Promoter (+ enhancer
/ intron if used)
Strength and control
of expression
Translation start Ribosome binding site
(RBS)
5’ UTR with Kozak Efficient, correct
initiation
Coding sequence CDS (+start +stop) CDS (+start +stop) Your gene of interest
Targeting (if needed) Signal peptide / tag Signal peptide
(secretion), tag
Where the protein
ends up
Transcription stop Terminator Terminator + Poly(A)
signal
Clean end of the
transcript
Vector context Backbone: origin of
replication + selection
marker
Backbone appropriate
to host
Replication and
selection
For each part you use, record in Kernel (and note in your write-up):
The part type and a short name.
Its sequence and where it came from (a Kernel part, a database, or designed).
One sentence of justification, why this part, for this host, for this product.
You do not need to hand-design a backbone from scratch; you may reuse an existing one and
say what it provides.
Part 3: Assemble your construct
Now put the parts together into a single construct in Kernel.
Create a new construct in your folder and add your parts in the correct 5’→3’ order for
your host (for a basic expression cassette: promoter → RBS or 5’ UTR/Kozak → CDS →
terminator, plus any signal peptide or tag, in the vector backbone).
Check the assembled sequence: the reading frame is intact, the start and stop codons are
where you expect, and there are no accidental internal stops.
Look at the construct map Kernel renders and confirm the parts sit in the order and
orientation you intended.Deliverable for this part: your assembled construct in Kernel, plus an exported schematic of it
in your write-up, with a brief description of the design.
Part 4: Optimize and quality-check
Use Kernel’s design tools on your coding sequence and construct, and interpret the results
rather than just running them.
● Codon-optimize your CDS for your chosen host. Compare before and after: what
changed, and why does codon usage matter for expression in this organism? Note any
constraints you applied (e.g. avoiding certain restriction sites, GC content).
● Search your sequence (BLAST / sequence search) against known sequences. Is your
CDS what you think it is? Is it identical to a natural gene, or novel? What is the closest
match?
● Run the safety screen on your construct. Summarize what it checks for and what it
reports. If it flags something, explain whether it is expected for your design and how you
would respond.
Deliverable for this part: a short paragraph per tool covering what you ran, what it returned,
and what you concluded. Screenshots welcome.
Part 5: From design to build
A sequence in software is not yet DNA. Using this week’s readings, reason about how your
construct would actually be made. Answer in your write-up:
● How would you build it? Would you order it as synthetic DNA, assemble it from smaller
fragments (e.g. Gibson assembly), or build it from a pool of oligos synthesized on a chip?
Justify your choice given your construct’s length and complexity.
● What does synthesis constrain? Synthesis has error rates and struggles with certain
sequences. Does your design contain anything hard to synthesize? How would error
correction or fragment-based assembly change your approach?
● Prototype vs. scale. Mirroring HW1: the way you’d build one construct to test your idea
may differ from how you’d produce DNA at the scale your product needs. Briefly describe
both if they differ.
Ground this in at least two of the assigned readings and cite them.
Part 6: What don’t you know yet?
As in Homework #1, close by naming the edges of your design. Identify the 2–3 biggest
unknowns or risks in your construct. For example: Will the promoter give the right expression
level? Will the protein fold and be active in this host? Will it be secreted? Is codon optimization
enough, or do you need to tune it empirically?For each, state how you would find out: the measurement, experiment, or design variant you
would try next. A good answer here shows you know which decisions are still bets.
AI