Hi, I’m Naufal Tsabitul Azmi, a Biotechnology graduate from Universitas Teknologi Sumbawa, Indonesia. My background includes laboratory and field experience in environmental microbiology, water-quality testing, aquaculture, and agriculture.
I am interested in how microorganisms can contribute to practical solutions for water pollution and agricultural challenges. I currently work as a boarding school mentor in Central Java while continuing to learn and prepare for further study in biotechnology.
My background
During my undergraduate research at BRIN in Bandung, I studied coliform contamination in dug-well water. My work involved water sampling, aseptic preparation, serial dilution, bacterial cultivation, and colony counting using Petrifilm and EMB agar. I also worked with water-quality measurements and field observations to understand the conditions surrounding the sampling sites.
Later, I worked as an Agricultural Specialist on an agrivoltaic project in Sumbawa. I assessed soil and water conditions and helped develop cultivation strategies with researchers, industry staff, and field teams. Working with difficult soil and limited water availability strengthened my interest in agriculture under environmental stress.
Why I joined HTBAA
These experiences gave me a starting point in laboratory and fieldwork, but I am still new to biomanufacturing and automation.
I joined HTBAA to learn how to turn an initial biological idea into a process that can be measured, tested, and repeated. I want to understand how microbial cultivation, formulation, and quality checks fit together, and how automation can support this work.
For my project, I am exploring a biochar-supported microbial inoculant for maize under water limitation. My first goal is to understand whether a suitable microorganism can be formulated with consistent viable-cell loading and remain viable during handling and storage.
I hope to use what I learn to strengthen my future environmental biotechnology research and bring more practical examples of biotechnology into educational settings.
My project idea: RootGuard
For my first project concept, I am exploring a biochar-supported microbial inoculant for maize under water limitation in Sumbawa.
The proposed carrier would be made from cocoa pod husk and okara. I am considering a strain-selected Bacillus subtilis candidate and would like to investigate whether it can attach to the carrier and remain viable during formulation and storage.
This is an early-stage proposal. Biofilm formation, storage stability, and benefits to maize still need experimental validation.
My first question is: Can I develop a formulation with a consistent, measurable viable-cell loading?
Homework, labs, and projects
This website documents my work for How to Biomanufacture (Almost) Anything — Fall 2026.
Use the navigation menu to explore my homework and project pages. I will use these pages to record:
My understanding of each assignment.
Design choices and the assumptions behind them.
Calculations, references, and proposed experiments.
Questions, limitations, and changes made as I learn.
Research interests
Microbial approaches to water remediation.
Biofilms and microbial attachment to carriers.
Biochar-supported inoculants for agriculture.
Accessible biotechnology learning in educational settings.
Contact
You can find me on the HTGAA course forum as Naufal Tsabitul Azmi.
I would be happy to exchange ideas with others learning about environmental biotechnology and microbial manufacturing.
Subsections of Naufal Tsabitul Azmi — HTBAA Fall 2026
Week 1 HW: Final Project Ideas
Week 2 HW: DNA Design — RootGuard TasA Prototype
Naufal Tsabitul Azmi · HTBAA Fall 2026 · Homework #2 Revised 2 October 2026. Kernel evidence was captured on 29 September–1 October; recovered sequence files were rechecked on 2 October. No wet-lab results are reported.
I designed a TasA expression prototype for my Homework 1 RootGuard concept. The assembled baseline is RootGuard_pHT01_Pveg_TasA_v2_DRAFT, an 8,734-bp pHT01-based construct containing native TasA CDS. Its actual Kernel GenBank export matches the prepared DNA. A separate 786-bp DNA Chisel candidate is a synonymous codon-usage comparison; it has not replaced the baseline.
This report answers Parts 0–6 and documents the available evidence. Host-specific codon optimization inside Kernel remains unresolved, and the exact course-workspace naming/membership also needs confirmation. The observed optimizer form did not offer Bacillus subtilis. I report the external alternative and its limits; instructor acceptance is not assumed. The assignment permits an imperfect design with explicit reasonable assumptions, but that does not waive this tool requirement.
Design brief: connecting HW1 to HW2
HW1 proposes RootGuard, a microbial inoculant carried on co-pyrolyzed cocoa pod husk and okara biochar, for eventual evaluation with maize under water limitation in Sumbawa. Its first goal is reproducible viable-cell loading and survival. Attachment, biofilm formation and plant benefit remain hypotheses. HW2 narrows that concept to a matrix-protein expression design; TasA is one component to investigate, not the complete inoculant.
Agenda item
Design decision
Evidence or assumption
Chassis
Bacillus subtilis; production strain not selected
Proposed host from HW1; NCIB 3610 is a sequence reference
Input
Constitutive Pveg-driven transcription
DNA design choice; biochar, nutrients and water limitation are conditions, not an encoded sensor input
Output
Full TasA protein, intended for extracellular matrix
Coding sequence checked; expression, processing and localization untested
Assay
Transcript/protein/localization, then matrix and viable-cell retention
Proposed measurements; no biological assay data
Part comparison
Pveg versus original Pgrac context; two RBS candidates; native versus synonymous CDS
Decisions below; no measured performance ranking
Minimum construct
Pveg–RBS–spacer–TasA–terminator, within retained vector context
953-bp cassette in an 8,734-bp computational construct
Annotation and order
Typed parts, coordinates, strand, frame and junction checks
Actual Kernel GenBank and local QC
PNG export
Actual Kernel schematic plus a labeled editor screenshot
Included below
Homework Review
Workspace, optimizer alternative and host/vector assumptions
Questions at the end
Part 0 — Set up in Kernel
My Kernel repository is RootGuard-HTBAA2026, and my folder is azmi-rootguard-tasa. The baseline construct is RootGuard_pHT01_Pveg_TasA_v2_DRAFT, ID 306fda68-569a-4502-9a08-7cf18035d57e.
I explored existing parts and constructs. A part has an assigned biological role, such as promoter or CDS; a construct holds an assembled sequence and its annotations. A CDS imported into a construct container is still CDS-only unless vector DNA is actually present. I used the editor, functional part linking, sequence search, checker, sequence statistics, schematic export, Biosecurity sequence scanner and Kernel AI.
The screenshots show a workspace called HTGAA 2026, whereas the handout asks for HTBAA 2026. Repository and folder creation are documented; membership in the exact requested workspace needs course-team confirmation. The process documentation records the sequence of decisions and errors; the Notion journal retains the broader screenshot history.
Part 1 — Define the expression target
What molecule am I expressing?
TasA, a protein, is the selected expression target. The proposed role is to investigate one protein component of extracellular matrix in the RootGuard chassis. I am not encoding biochar synthesis, a complete biofilm pathway, drought sensing or a proven plant-growth effect.
What is the sequence, and where does it come from?
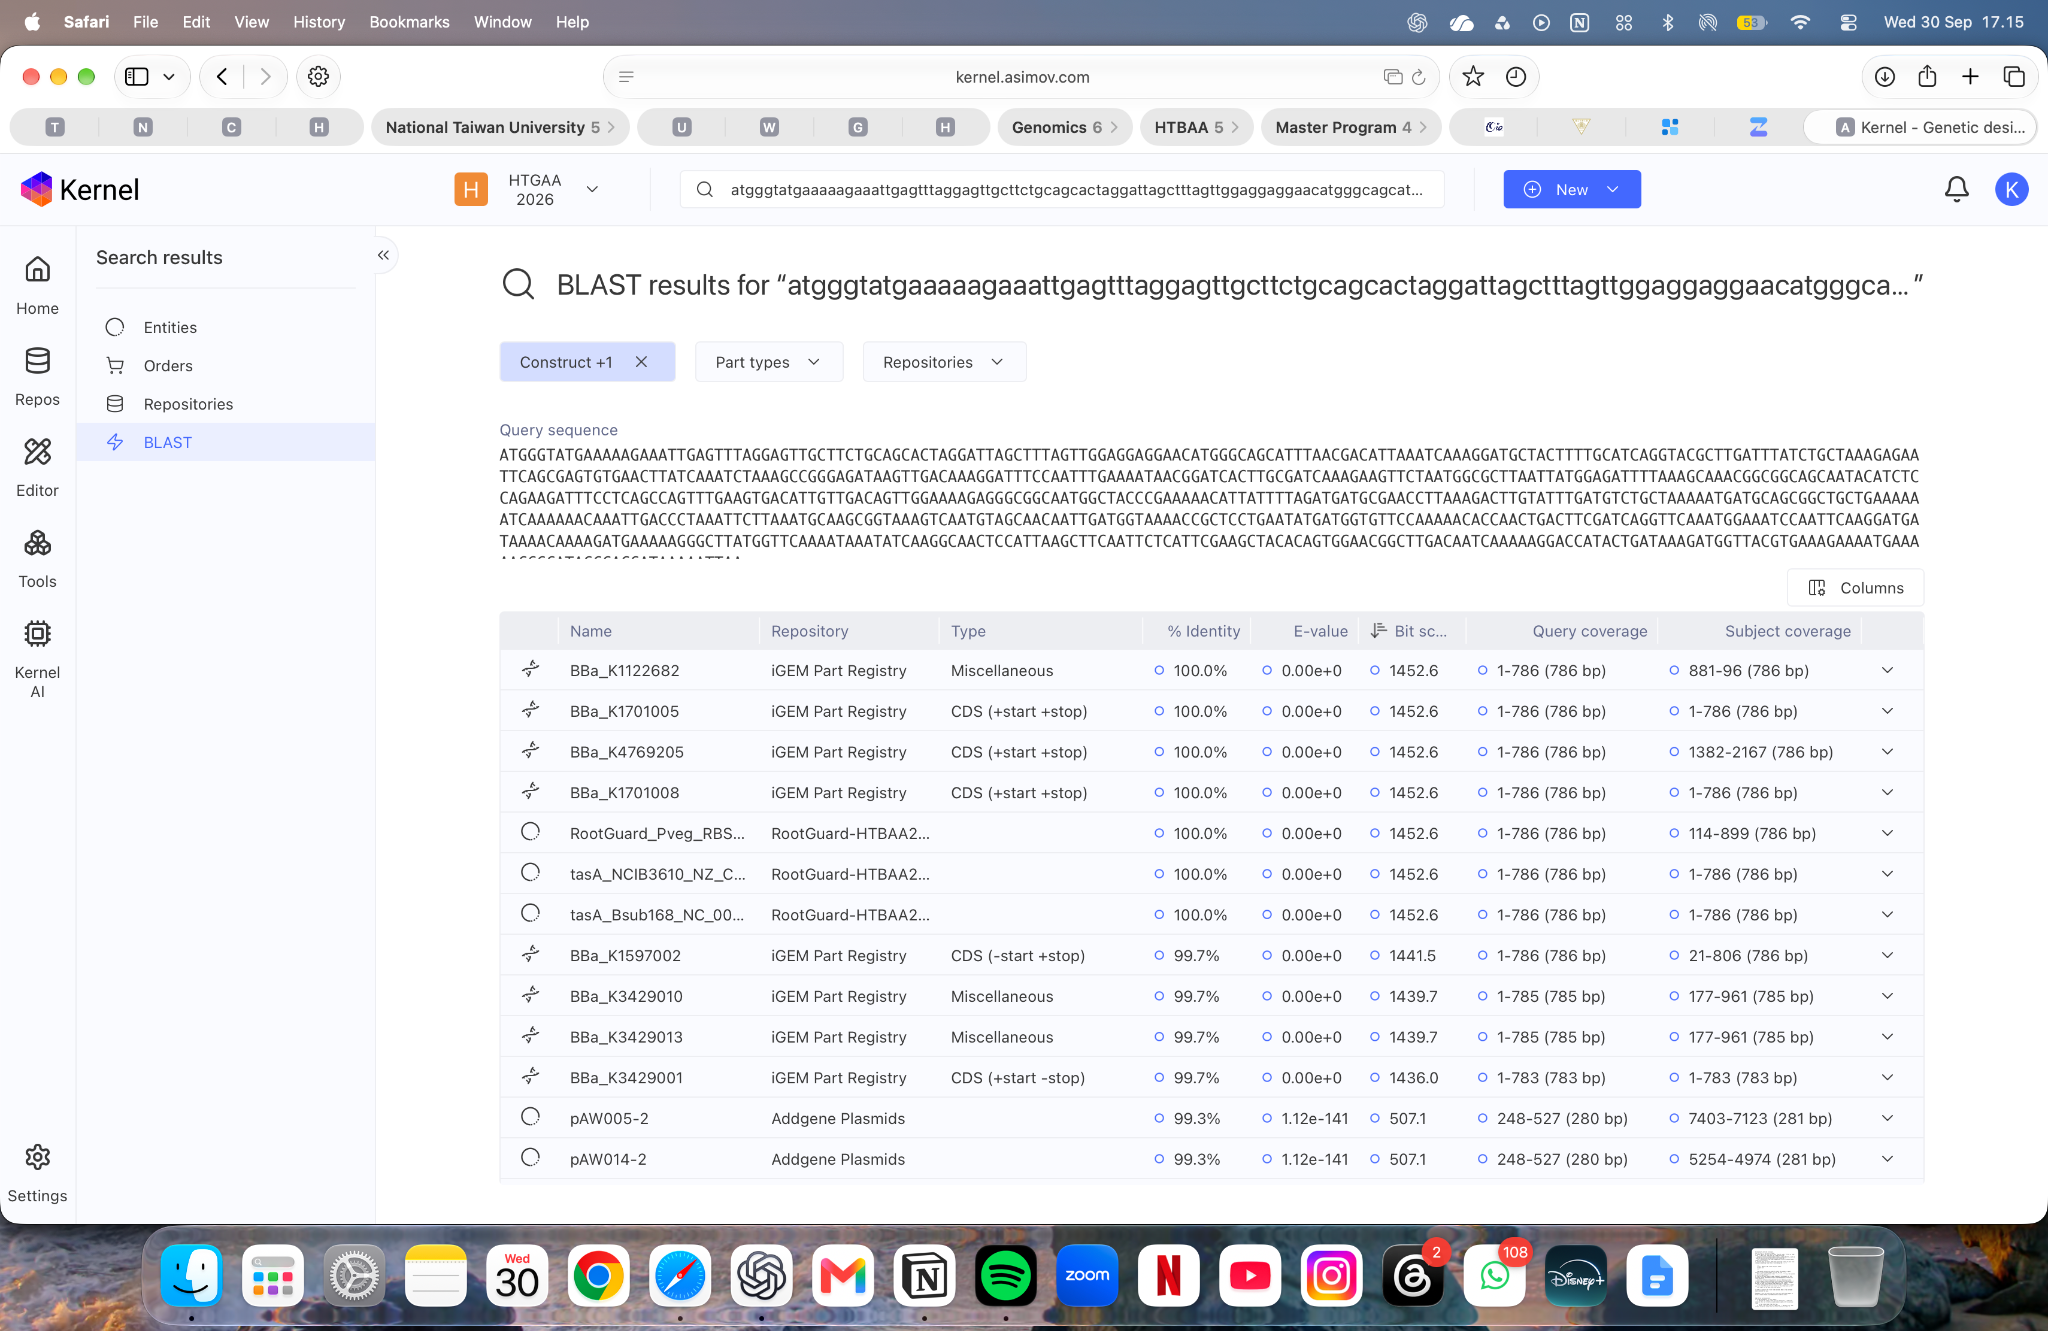
The sequence reference is B. subtilisNCIB 3610, chromosome NCBI NZ_CP020102.1, annotated feature complement(2553102..2553887), protein WP_004398632.1. The 786-bp native TasA CDS, including start and stop, matches iGEM BBa_K1701005 in the recorded full-length search. Download the complete native CDS and 261-aa protein sequence.
The imported strain-168 CDS is identical in this comparison. Consequently, the CDS match does not identify a strain background or prove that NCIB 3610 is the best production strain. NCIB 3610 remains the documented sequence source.
The chromosome feature lies on the reverse strand. For the construct, the CDS is represented in its own 5′→3′ coding direction, using the reverse complement of that chromosome interval. It starts ATG, ends TAA, contains 262 codons including the stop, and translates to 261 amino acids with no internal in-frame stop.
What is the chassis?
The intended expression host remains B. subtilis, consistent with HW1. An actual production strain still needs selection and qualification. I therefore do not claim that a named strain has been engineered, cultured or validated. Kernel metadata uses Other, with the intended Bacillus host stated in the description; a generic menu choice does not establish biological compatibility.
Where should the protein go?
The desired destination is extracellular matrix. I retain the full native N-terminal region and add no separate signal peptide or tag. Processing/export and the relevant SipW/TapA/matrix context must be checked in the eventual strain. The biological literature describes SipW-associated processing and matrix regulation in this system; it does not demonstrate performance of my construct. Terra et al. (2012), DOI 10.1128/JB.06780-11.
Part 2 — Design and compare the parts
Selected parts: type, sequence, source and justification
All expression-cassette sequences are supplied in the functional-parts FASTA. The annotation TSV pairs each sequence with its type, source, direction and coordinates. The complete reused vector context is included in the actual GenBank and reference FASTA.
Supplies a Bacillus/E. coli shuttle-vector context; retained regions require physical-vector and boundary review before construction
The Pveg and terminator sequences, extracted from the actual Kernel export in forward orientation, are:
Pveg — 97 bp
AATTTTGTCAAAATAATTTTATTGACAACGTCTTATTAACGTTGATATAATTTAAATTTTATTTGACAAAAATGGGCTCGTGTTGTACAATAAATGT

Terminator — 54 bp
AAGAAGAAGTGTGAAAAAGCGCAGCTGAAATAGCTGCGCTTTTTTGTGTCATAA
There is no extra targeting element, because the full native N-terminal sequence is retained. There is no eukaryotic Kozak or poly(A) design: this is a bacterial expression cassette.
Candidate part comparison
Layer
Selected candidate
Alternative
Decision and remaining uncertainty
Transcription
Constitutive Pveg
Original pHT01 Pgrac/lac-controlled expression context
Keep Pveg for continuity with v1 and a simple prototype; constitutive expression may cause burden, and no strength comparison has been measured
Keep K090505 as the initial candidate; test otherwise matched RBS/spacer variants rather than infer strength from the name
Coding sequence
Native 786-bp TasA CDS
External synonymous codon-usage candidate, also 786 bp
Native remains in assembled v2; the candidate tests a codon-usage hypothesis and is not a proven expression improvement
The selected RBS has a nominal AAAGGAGG core followed by TGT; with the designed AATTA spacer, this gives a nominal eight-base interval before ATG. This is a sequence description, not proof of optimal initiation spacing or mRNA structure.
Replication and selection context
The copied 7,956-bp pHT01 DNA matches the archived Addgene vector sequence. This verifies the digital sequence relationship, not a physical clone or present-day purchasing availability. The MoBiTec Bacillus vector manual describes shuttle-vector use and chloramphenicol/ampicillin selection context. The design retains reference-mapped cat/CmR, bla/AmpR, lacI and replication-associated regions outside the replacement.
ColE1 is the E. coli replication-origin annotation. Minimal Bacillus origin boundaries are not assigned here. Marker/regulator annotations remain mapped reference regions, not newly validated complete CDS models. I would confirm the exact vector and its Bacillus replication/selection context before physical construction.
Part 3 — Assemble the minimum construct and check direction
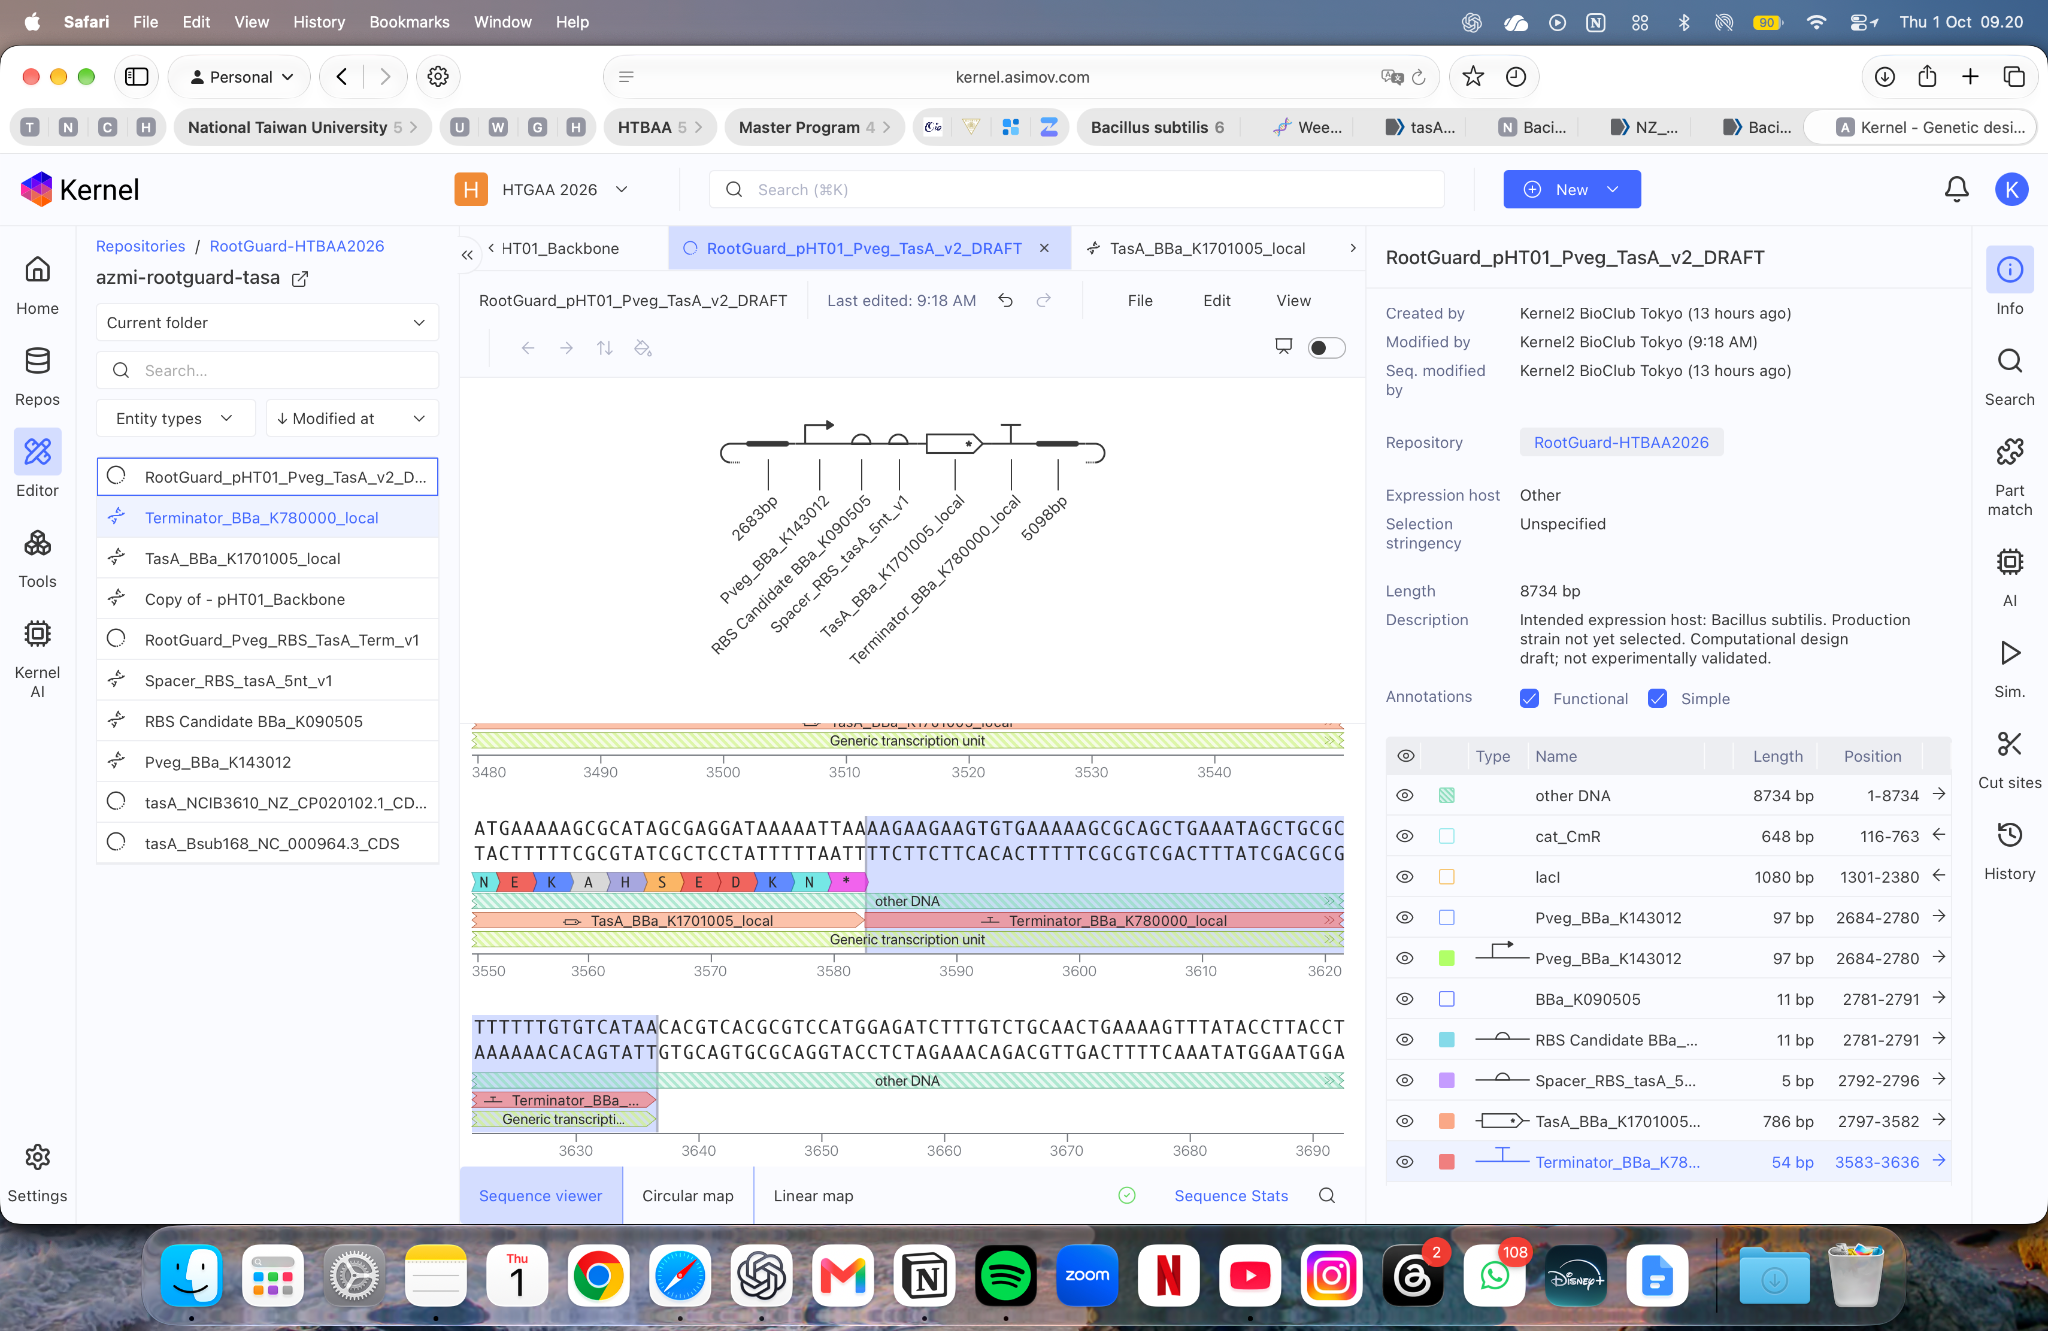
The expression order is Pveg → RBS → spacer → full native TasA CDS → terminator, within the pHT01-derived context. The original 953-bp v1 contained this cassette only. Its circular topology metadata did not supply a replication backbone. Current v2 contains 8,734 bp.
Functional annotation
Coordinates in v2, 1-based inclusive
Length
Direction
Pveg_BBa_K143012
2684–2780
97 bp
Forward
RBS Candidate BBa_K090505
2781–2791
11 bp
Forward
Spacer_RBS_tasA_5nt_v1
2792–2796
5 bp
Forward
TasA_BBa_K1701005_local
2797–3582
786 bp
Forward
Terminator_BBa_K780000_local
3583–3636
54 bp
Forward
I provisionally replaced pHT01 2684–2858, a 175-bp reference-mapped expression interval, with the 953-bp cassette: 7,956 − 175 + 953 = 8,734 bp. The left 2,683 bp and right 5,098 bp are unchanged. The replacement boundaries are engineering assumptions, not validated assembly junctions. Reference annotations were mapped by aligning an annotated NovoPro pHT01 variant to the exact copied DNA; differing variants were not assigned identical coordinates blindly. Residual lacI context remains.
Sequence-level checks and result
The actual Kernel GenBank export was checked against prepared v2 DNA. The original 1 October export QC passed 16 assertions. A separate 2 October re-verification passed 25 local checks, including length, unchanged flanks, cassette/CDS identity, typed forward annotations, start/stop, translation and the native–candidate comparison.
The RBS–spacer–start junction is AAAGGAGGTGT–AATTA–ATG. TasA is divisible by three, starts and stops at the intended positions, and has no accidental internal stop in its reading frame. Whole-v2 GC is 40.26%; native-CDS GC is 37.66%. Normalized v2 DNA SHA-256 is 23c372fad614d39adb670cf5291f002524fd956d518e39186b48047c7d81eba1. This DNA hash is distinct from the hash of the GenBank file bytes.
Figure 1. Actual Kernel PNG export, unchanged. Part-name labels are absent from this transparent export; the table above and labeled editor screenshot below supply the legend.
Figure 2. Original editor screenshot, 1 October 09:20 WIB. The functional definitions coexist with simpler feature labels; this does not mean extra copies of the DNA were inserted.
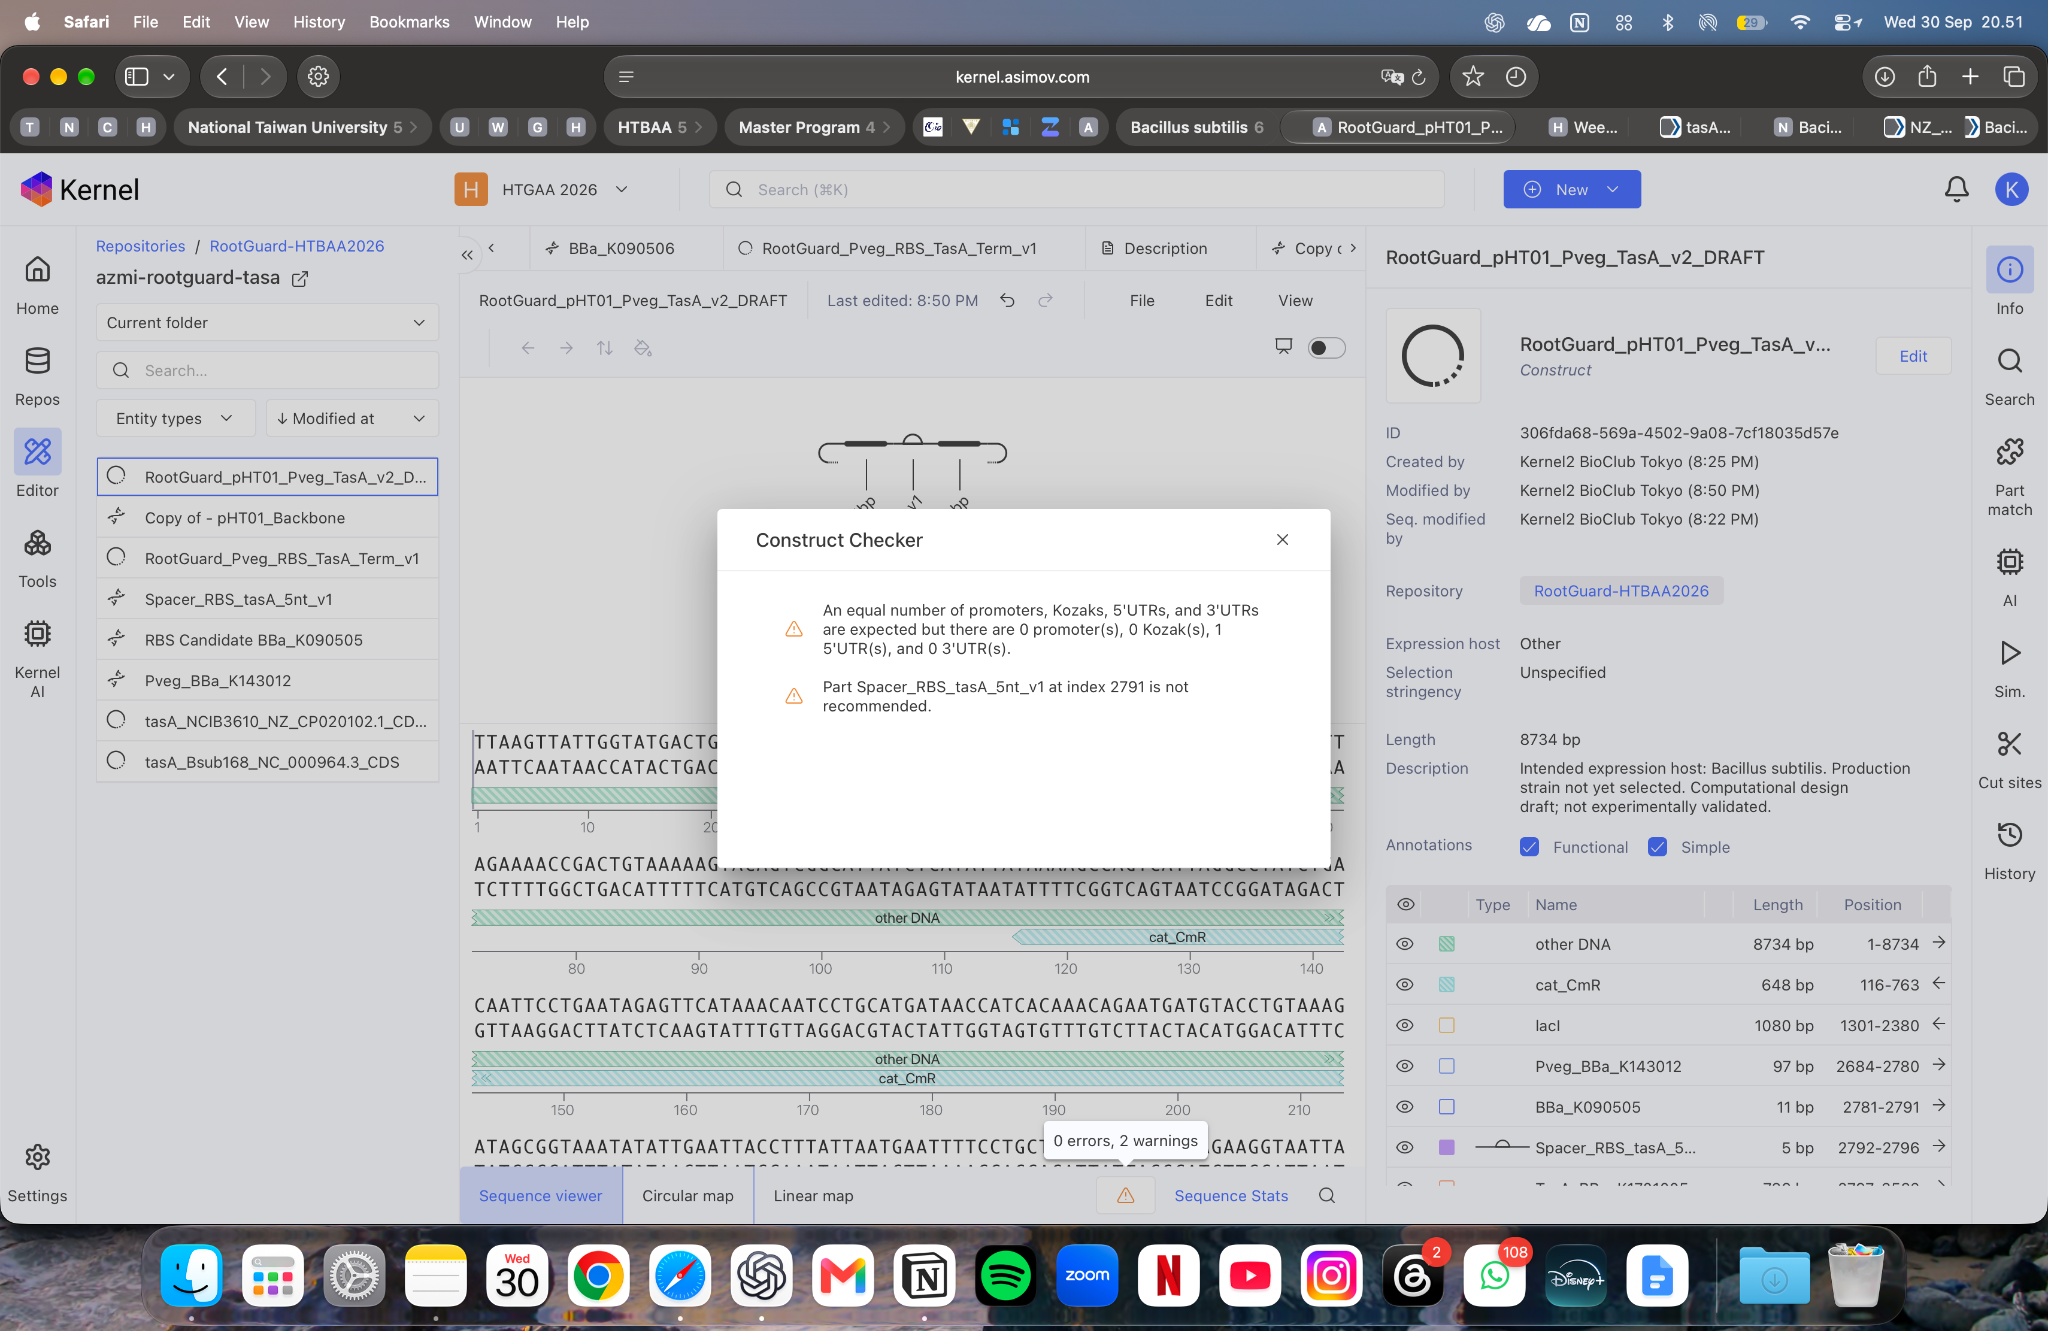
An earlier v2 checker showed 0 errors and 2 warnings, including a promoter-count inconsistency and an unrecommended local spacer. Typed functional parts were subsequently verified in the export. A complete updated v2 warning dialog is not supplied, so I do not claim that all v2 warnings disappeared. The documentation retains the earlier warning screenshot and explains its interpretation.
Part 4 — Optimize and quality-check
Codon optimization: what was attempted, returned and concluded
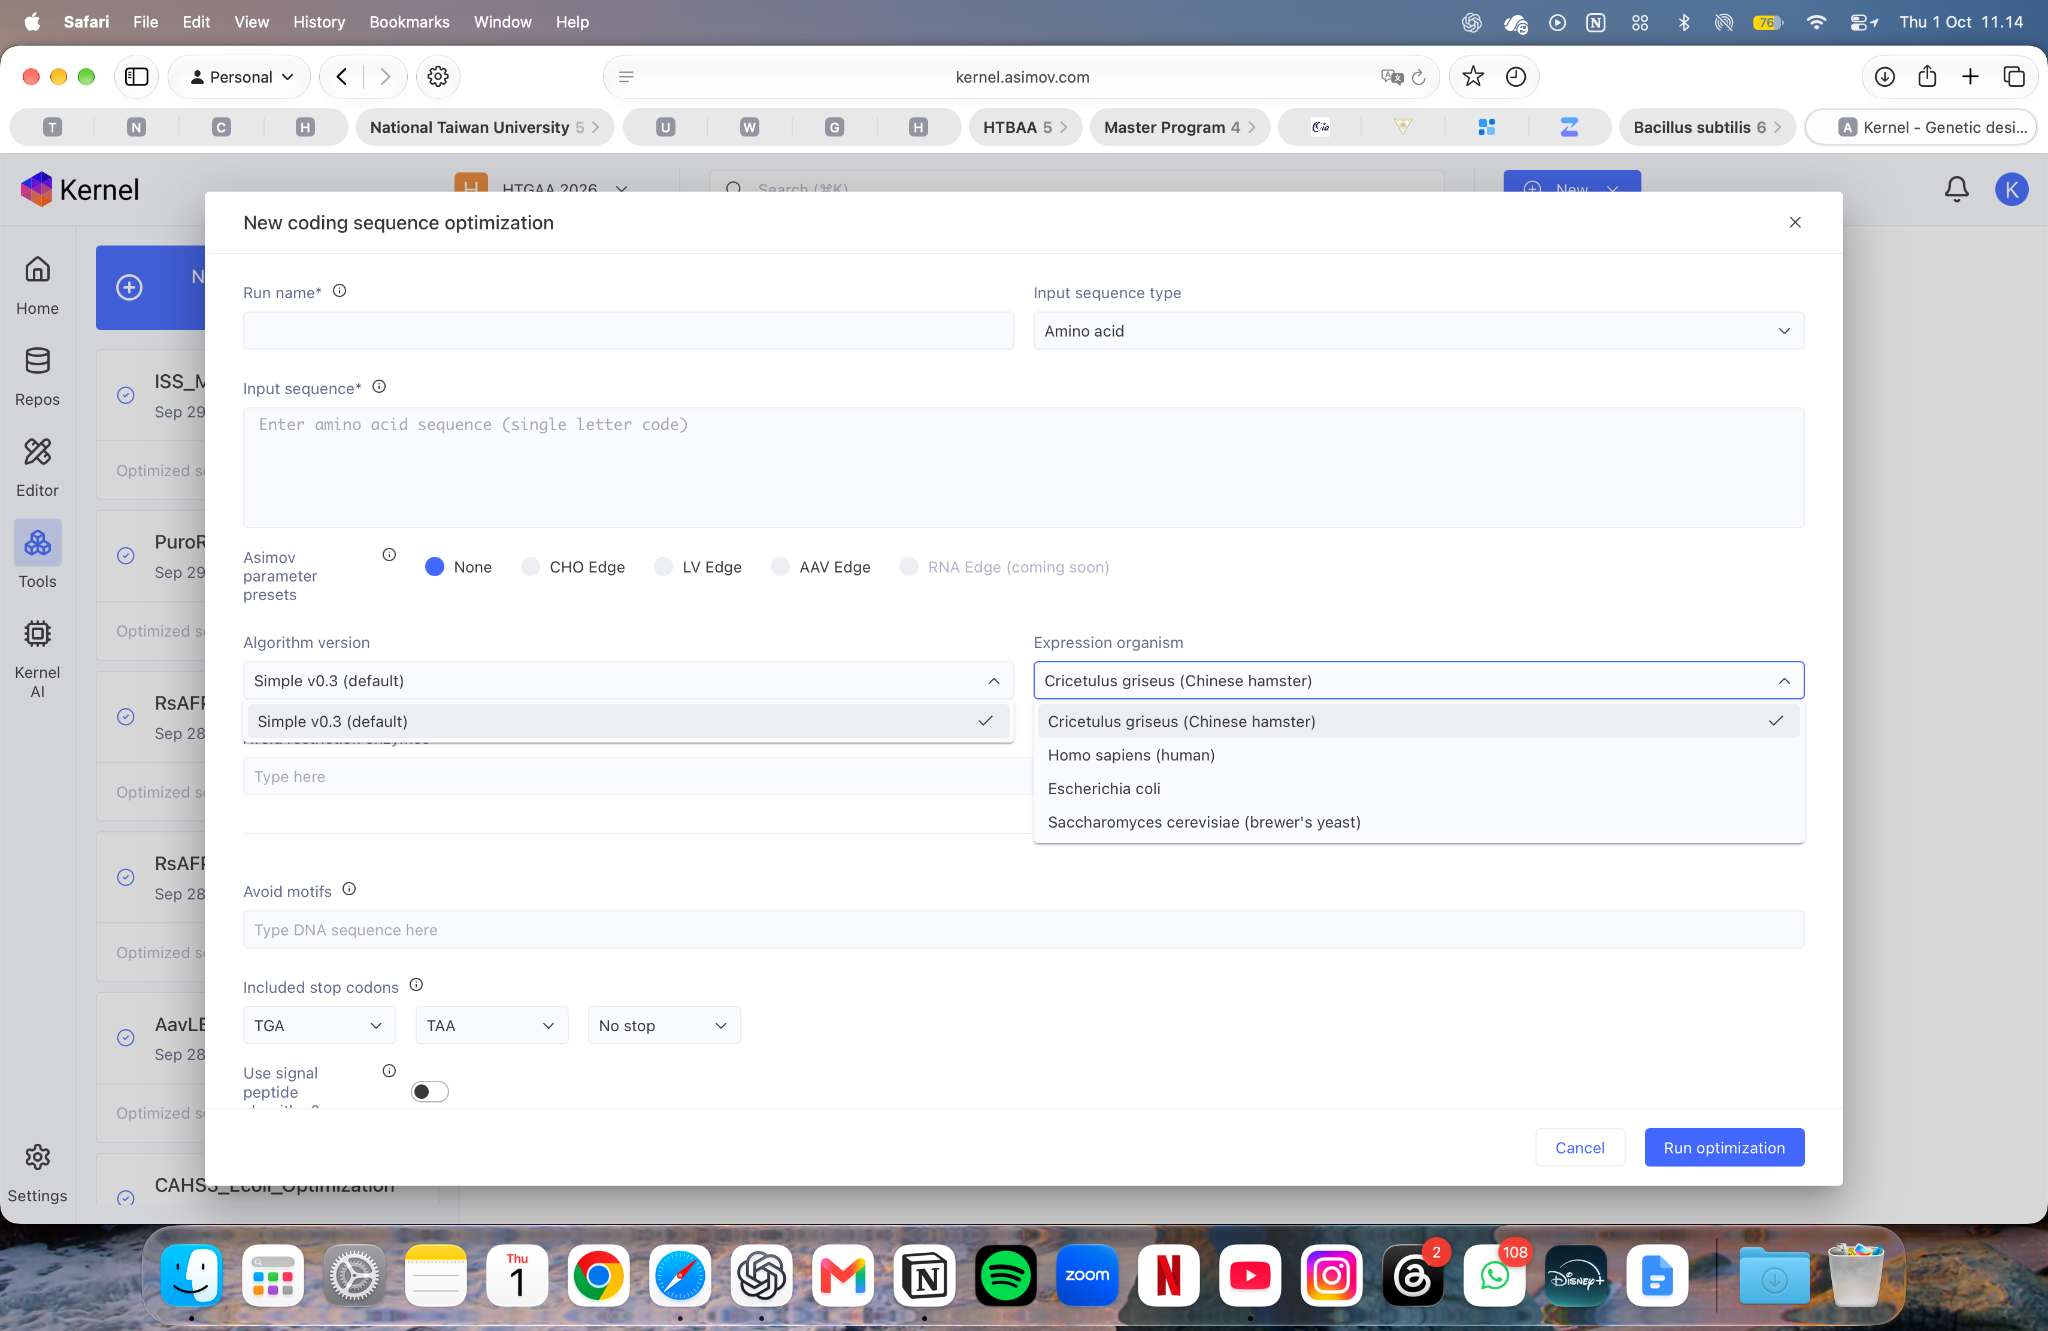
I inspected Kernel’s Simple v0.3 optimizer. The observed expression-organism menu offered Chinese hamster, human, E. coli and yeast, with no B. subtilis option. Kernel AI suggestions did not establish an available Bacillus setting. I did not substitute another host and call the result Bacillus optimization.
Figure 3. Original screenshot, 1 October 11:14 WIB. This documents the observed form, not a claim about every future Kernel version or workspace.
For a documented external comparison, I used DNA Chisel 3.2.16, CodonOptimize(method=“match_codon_usage”), and python_codon_tables 0.1.18 with b_subtilis_1423. The source is a species-level Kazusa/NCBI-derived table, not a selected production-strain or curated highly expressed-gene reference. Optimization covered the 261 sense codons, with seed 20261001. Constraints retained the protein, ATG start and TAA stop.
Different synonymous codons encode the same amino acid but may affect translation in a host. Matching a codon table offers a testable design hypothesis; it does not predict secretion or guarantee improved expression. DNA Chisel documentation and codon-table provider.
Metric
Native CDS
External candidate
Length
786 bp
786 bp
Translation
261 aa
Same 261 aa
Start / stop
ATG / TAA
ATG / TAA
GC
37.66%
42.49%
Longest homopolymer
6 bases
7 bases
Codon-profile discrepancy objective
−88.18
−12.36
The candidate contains 52 nucleotide substitutions across 47 synonymous codons. Closer to zero means a closer table-profile match for this objective; the score is not CAI and is not measured expression. No GC target, restriction-site avoidance, mRNA-folding, secretion-efficiency or vendor-acceptance constraint was imposed.
The separate Kernel entry RootGuard_TasA_Bsub_DNAChisel_candidate_v1_2026-10-01, ID 61e38ea9-3d0f-4cc4-9b8a-629c57ec7736, is CDS-only, with tasA 1–786 forward. Its Sequence Stats shows 786 bp / 42.49% GC; editor validation shows 0 errors / 0 warnings. Those checks do not prove biological function. Its complete Kernel re-export has not been hash-compared; the supplied candidate GenBank is an external file, not that missing re-export. Native assembled v2 remains unchanged.
Sequence search: identity and nearest visible matches
I submitted complete CDS sequences to Kernel’s global sequence search. The results concern Kernel’s indexed repositories, including public iGEM entries and local constructs; this was not a separate NCBI BLAST run. Exact algorithm parameters and database snapshot were not displayed.
Query and visible public hit
Identity
Query / subject coordinates
Displayed E value
Bit score
Native CDS → BBa_K1701005, 30 September
100.0%
1–786 / 1–786
0.00e+0
1452.6
External candidate → BBa_K1701005, 1 October 12:25
93.4%
1–786 / 1–786
0.00e+0
1164.5
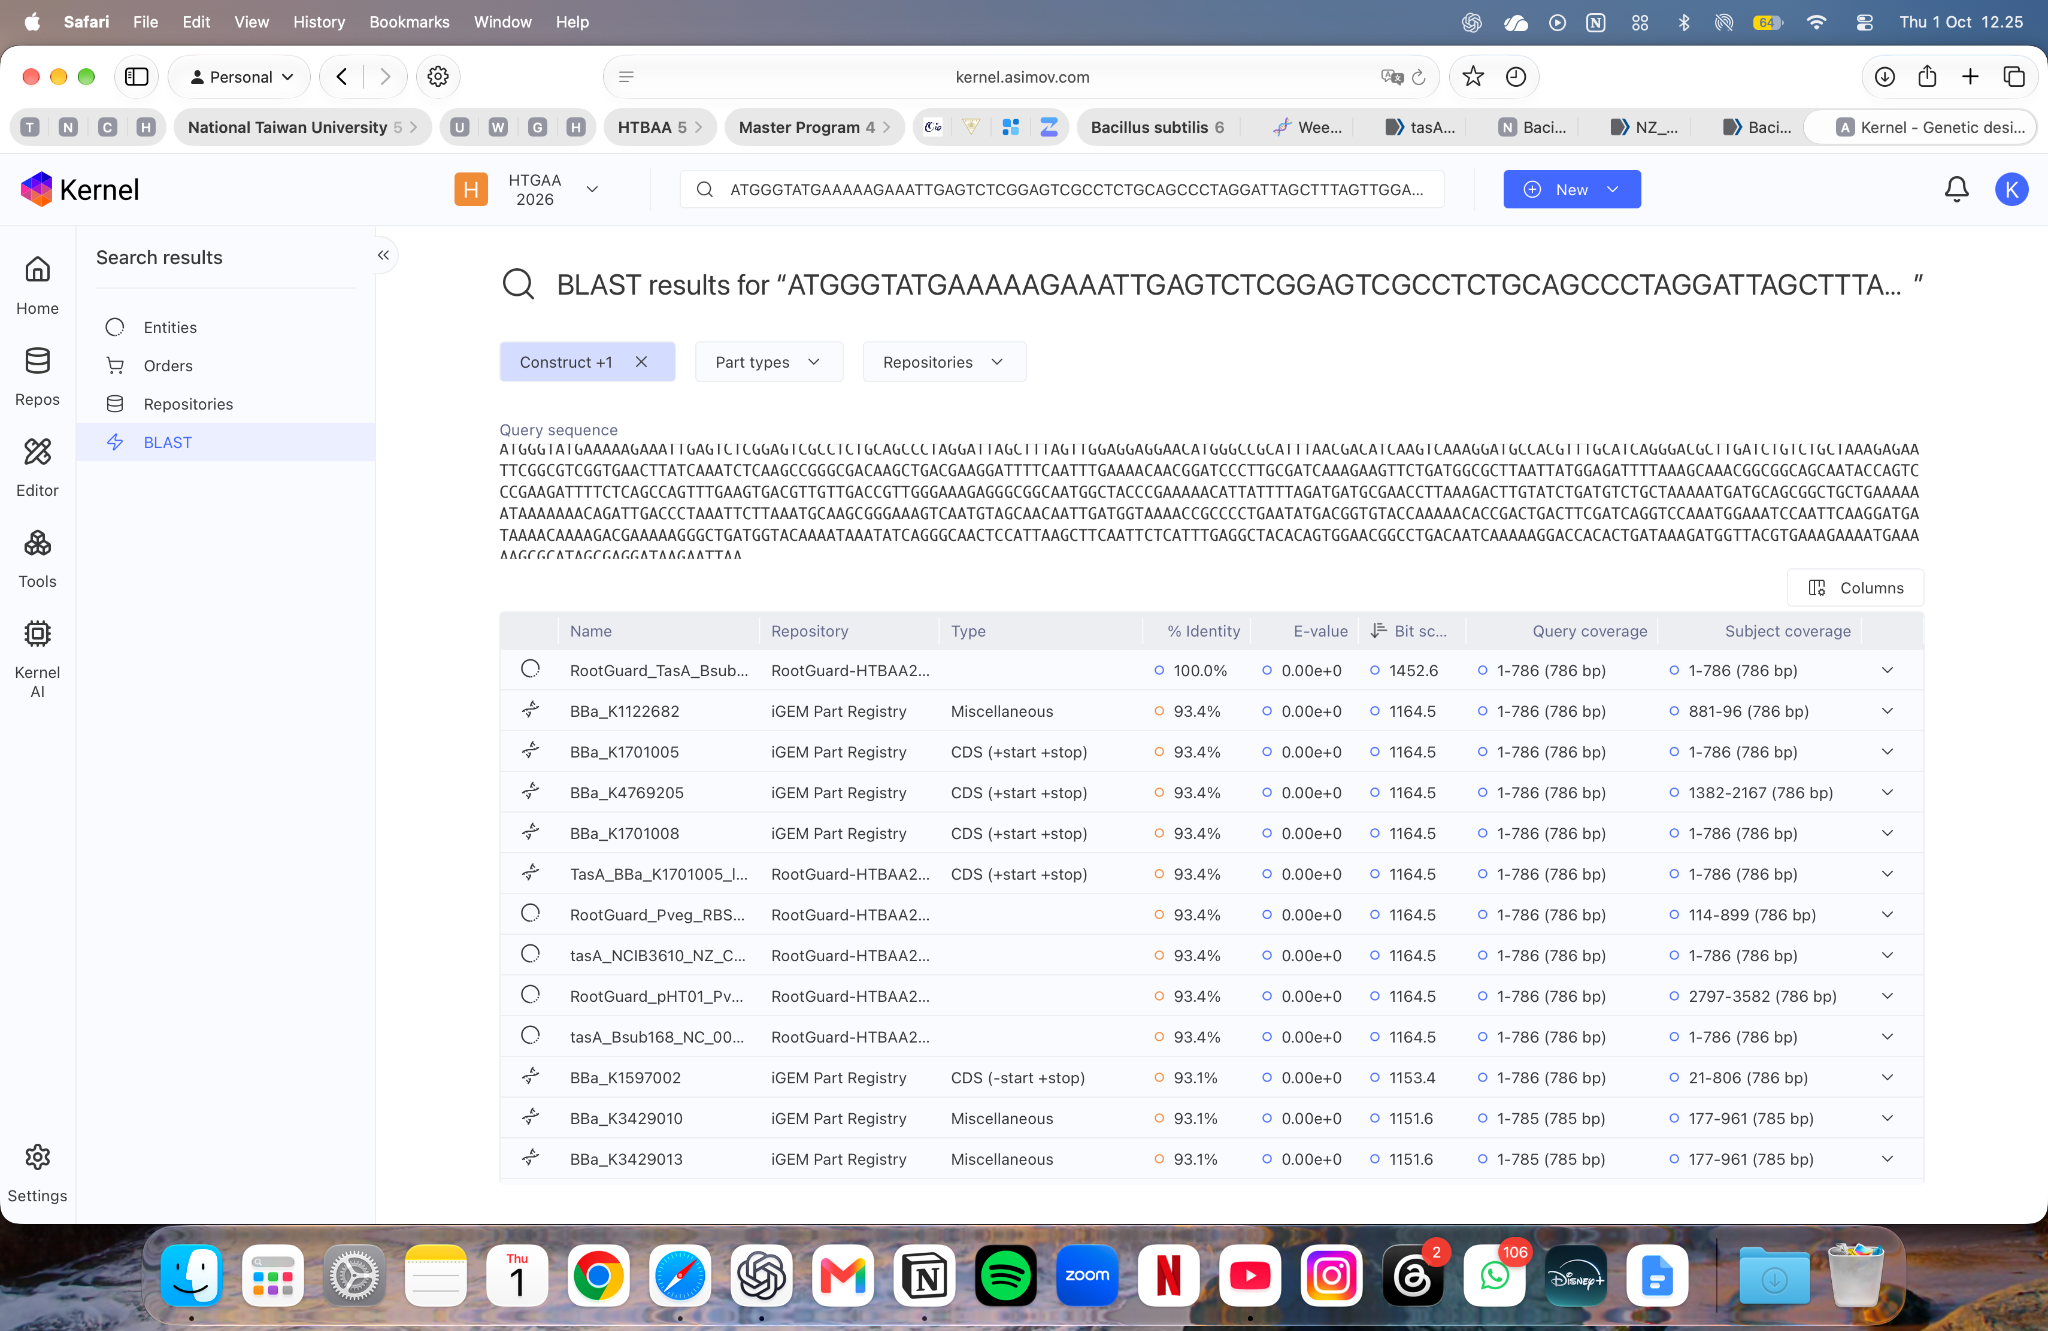
The native query is consistent with the known TasA sequence. For the candidate, several public/native entries tie at 93.4%. 734 / 786 × 100 = 93.3842%, matching the rounded display after 52 substitutions. This is a redesigned DNA sequence relative to the native reference, while local translation confirms the same protein. It is not evidence of globally novel sequence or a new protein function.
Figure 4. Native search, 30 September 17:15 WIB. BBa_K1701005 is a full-length 100% hit; other entries contain the same matching region.
Figure 5. Candidate search, 1 October 12:25 WIB. The local candidate’s 100% self-match is not independent biological evidence. The visible filter is “Construct +1”; the additional entity type is not expanded. Subject coordinates differ between entries, including a reverse-oriented hit.
Biosecurity screening: what it checks and what happened
Kernel’s Biosecurity sequence scanner, powered by SecureDNA, compares nucleotide input against a database of potential biosecurity threats. The observed action button was Scan for Biohazards. The v2 workflow at 09:54 WIB and the candidate workflow at 12:14 WIB on 1 October reported No flagged sequences detected. Earlier v1 screening also reported no flags. Official Kernel documentation.
Figure 6. Whole-v2 workflow result, 1 October 09:54 WIB.
Figure 7. Candidate workflow result, 1 October 12:14 WIB.
The intended inputs were the 8,734-bp v2 and 786-bp candidate, and visible sequence endpoints agree with the source files. The screenshots do not independently establish full input length/hash, database version or a screening certificate. I retain this provenance limitation. No sequence flags in these runs does not establish living-strain safety, successful expression or suitability for environmental release. If a subsequent screen flags a region, I would review that region with the course team and screening provider rather than treat a digital pass as a substitute for review.
Historical QC files are kept unchanged. A generation-time field such as “candidate not imported or screened” describes that earlier snapshot; subsequent import, search and screening are documented here and in the dated re-verification record.
Part 5 — From design to build
How would I build one prototype?
I would start with a sequence-verified synthetic native cassette of 953 bp and an identified, compatible pHT01-derived vector. A fragment-based approach is reasonable for this modest cassette. Gibson assembly is a candidate route after the insertion boundaries and complementary overlaps are reviewed. I have not specified ready-to-order primers, overlaps or assembly scars, and no DNA has been ordered or built.
Physical assembly followed by insert/junction sequence verification
This is the minimum specification for review, not a completed commercial order. An entire 8.7-kb synthetic plasmid might be another route, but I have not checked vendor feasibility or cost and do not assume it is necessary for one prototype. A chip-derived oligo pool adds complexity that is not justified for this single initial cassette.
What does synthesis constrain?
Native CDS GC is 37.66%, its longest homopolymer is six bases, and it contains an EcoRI site at positions 150–155. That site matters if EcoRI is selected for restriction assembly; it does not inherently prevent an overlap-based assembly. The candidate’s longest homopolymer increases to seven bases, showing that codon-table matching does not automatically improve every synthesis property. These are CDS observations, not a full-vector vendor acceptance audit.
Before ordering fragments, I would review GC extremes, repeated or difficult regions, unwanted assembly-related sites and junctions. Splitting a difficult region into fragments may alter the build plan, but fragment assembly still needs sequence confirmation. There is no current vendor-specific difficulty report for this design.
Two assigned readings directly support this reasoning:
Gibson et al. (2009) describes joining overlapping DNA fragments using exonuclease, polymerase and ligase in an isothermal reaction. It supports the proposed overlap-assembly route, without validating my chosen junctions. DOI: 10.1038/nmeth.1318.
Carr et al. (2004) describes mismatch-protein-based error reduction in synthesized DNA. It supports considering synthesis errors and sequence verification of received DNA; I do not claim to have applied that error-correction method. Its historical error figures are not a current supplier guarantee. DOI: 10.1093/nar/gnh160.
Prototype versus scale
For a larger library of DNA variants, pooled synthesis and selective amplification, as in Kosuri et al. (2010), could become relevant. DOI: 10.1038/nbt.1716. This is distinct from scaling RootGuard production. After a strain and design are qualified, manufacturing focuses on cultivation, carrier formulation, recoverable viable cells and batch consistency; it does not require synthesizing new DNA for every inoculant batch. This keeps HW2 consistent with HW1’s proposed automated screening and later process-control workflow.
Part 6 — Three validation risks and how I would find out
Biggest unknown
Why it matters
Next measurement or design comparison
Regulatory parts may give inadequate expression, burden or read-through
Correct DNA order does not establish useful TasA expression
Compare matched promoter/RBS/spacer variants and controls; measure TasA transcript/protein, downstream read-through and growth. Compare native and synonymous CDS under the same regulatory context if the candidate advances
TasA may not be processed, exported or assembled into matrix
The production strain is unselected; TasA alone may not supply the needed host context
Check SipW/TapA/matrix context, extracellular TasA and structured matrix with appropriate controls; distinguish total protein from correctly localized/assembled product
Matrix may not improve RootGuard cell retention or plant outcomes
Biochar compatibility, cell recovery and spore-mediated survival may confound interpretation
Compare recoverable viable cells per gram, retention/storage, spore fraction and microscopy with matched free-cell, carrier-only and recovery controls; evaluate maize responses separately after strain qualification
Biochar can interfere with optical or colorimetric measurements, as already considered in HW1. Carrier blanks and recovery controls therefore matter. No matrix improvement, drought tolerance, maize-yield benefit or shelf-life claim follows from the software results.
Verified results versus assumptions
Verified within the supplied computational evidence
Still uncertain
Actual v2 export: 8,734 bp, native CDS, preserved flanks and intended typed cassette annotations
Biological validity of vector replacement boundaries and the eventual strain context
Native/candidate local files: 786 bp each, identical 261-aa protein, 52 substitutions and 47 synonymous codons
Recorded search identity/coverage and observed SecureDNA no-flag messages
Screening input’s independently verified full hash/count; live-organism suitability
Actual PNG export and dated editor screenshots
Complete latest v2 warning state; acceptance of the external optimization alternative
The handout asks for a defensible design, not a perfect lab-ready plasmid. The result is a documented computational prototype with explicit unresolved requirements, not a validated RootGuard product.
Questions for Homework Review
Does the visible HTGAA 2026 workspace satisfy the requested HTBAA 2026 workspace?
Can the documented external Bacillus codon comparison satisfy Part 4, or which available Kernel workflow supports this host?
Is TasA alone an appropriate HW2 scope, and which strain-context, replication and replacement-boundary checks should precede construction?
Requirements follow the supplied HTBAA Homework #2: DNA Design handout and HTBAA Fall 2026 Syllabus. Project continuity follows my published HW1 and its supplied PDF. Sequence, part, vector and software links appear beside the relevant claims. Build reasoning uses the assigned Gibson (2009), Carr (2004) and Kosuri (2010) readings; I do not imply that every assigned reading was needed to select this simple cassette.
I used ChatGPT by OpenAI to interpret requirements and screenshots, review provenance/direction/frame, prepare the provisional pHT01 draft, run the external DNA Chisel comparison, recover/check files and revise this report. English translations of prompts originally submitted in Indonesian include:
“How can I obtain it from an official source?”
“Is this what you meant by exporting the map? Now that I have reached this stage, what should I do next to complete Homework 2 and publish it?”
“Can you evaluate and analyze the entire narrative?”
“Please prepare a fully revised write-up, including documentation and results, that answers all of the questions in Homework 2.”
I also consulted Kernel AI about Bacillus optimizer support. The exact English prompt asks for available controls, an explicit limitation if unsupported, and no substitution of another host or modification of native v2. AI suggestions were checked against available controls and sequence evidence. Proposed biological behavior remains an assumption wherever marked.
Subsections of Week 2 HW: DNA Design — RootGuard TasA Prototype
RootGuard HW2 — Process Documentation in Kernel
Process documentation · revised 2 October 2026 · English translation prepared 2 October 2026. Times use Western Indonesian Time (WIB, UTC+7), unless explicitly stated as UTC.
This record describes the work completed, the reasons for design decisions, and the questions that remain unresolved. It does not replace laboratory data. The more detailed history, including 51 original images, remains in the Notion journal.
1. Understanding the design files
Expression instructions can be understood as a recipe for producing a protein. TasA provides the coding instructions for one protein, while the promoter, RBS and terminator help control how those instructions are read. The backbone provides the context for maintaining DNA in a suitable host. This analogy helps explain the components; actual function still depends on the sequence, strain and experimental conditions.
Object
Contents
Purpose
Native TasA, 786 bp
CDS only, including ATG and TAA
Gene reference and sequence comparison
RootGuard v1, 953 bp
Promoter + RBS + spacer + CDS + terminator
Initial cassette history; no replication backbone
RootGuard v2, 8,734 bp
Native cassette in the pHT01 context
Main assembled design for HW2
DNA Chisel candidate, 786 bp
Synonymous CDS from an external comparison
Codon-usage comparison; has not replaced the CDS in v2
The Construct label in Kernel identifies a data container. It does not establish that the DNA inside is a complete plasmid. Similarly, circular metadata does not add a missing backbone.
2. Selecting a focused target from HW1
HW1 describes the RootGuard inoculant with a cocoa pod husk and okara biochar carrier, intended for evaluation with maize in Sumbawa. The initial goals are consistent viable-cell loading and survival. I selected TasA as one protein target associated with matrix structure; this choice does not establish that a single gene will produce a complete biofilm or a benefit to the plant.
The proposed chassis remains Bacillus subtilis. The production strain has not been selected. NCIB 3610 is the sequence reference. Future strain selection needs to consider identity, suitability for maize, growth, matrix formation and retention, and formulation stability, as proposed in HW1.
3. Retrieving the CDS from NCBI and checking its orientation
The chromosome reference is NZ_CP020102.1. The tasA feature is located at complement(2553102..2553887), with protein WP_004398632.1. The term complement indicates that the gene lies on the opposite strand relative to the displayed chromosome coordinates.
The expression design requires the CDS in the 5′→3′ coding direction. The full chromosome and an uncorrected plus-strand copy of that interval would not provide the intended coding sequence. The file used contains 786 bp, beginning with ATG and ending with TAA. Translation produces 261 aa, with no internal stop codon in the reading frame.
The initial guidance required two corrections: a strain 168 file should not be labeled NCIB 3610 without checking its source, and an earlier claim of a 1,384-bp design did not match the available CDS file. The comparison subsequently found the strain 168 CDS and this reference CDS to be identical. I therefore retained the documented source. An identical gene sequence does not establish strain identity or show that a more recently referenced strain is superior.
The repository is RootGuard-HTBAA2026, and the folder is azmi-rootguard-tasa. The visible workspace is named HTGAA 2026, whereas the assignment refers to HTBAA 2026. The course team needs to confirm the naming and membership; the difference alone does not establish whether the workspace is correct.
The following parts were used:
Part
Action taken
Process notes
Pveg, BBa_K143012
Saved a local copy as Promoter and retained the original source
The visible public part type did not match the intended role; duplicate names needed to be distinguished and did not demonstrate damaged DNA
RBS BBa_K090505
Saved an RBS candidate and reviewed BBa_K090506 as a comparison
Neither RBS has been evaluated experimentally for expression strength with TasA
Spacer AATTA
Saved Spacer_RBS_tasA_5nt_v1, typed as 5′ UTR
Local design; not an NCBI sequence or a validated assembly scar
TasA BBa_K1701005
Checked the native sequence match, then created a local CDS when part search failed
CDS (+start +stop) matched a CDS that already contained ATG and TAA
Terminator BBa_K780000
Created and linked a local part typed as Terminator
Termination function still requires measurement in the final host and context
After a part was saved and visible in the folder, it could either be inserted as DNA or linked to an existing interval as a part definition. These are different operations. The cassette DNA was already present in v2, so linking its annotation to a part should not insert a second DNA copy.
5. Building cassette v1 and adding the backbone context in v2
The 953-bp v1 cassette follows the order Pveg → RBS → spacer → TasA → terminator. Its coordinates are 1–97, 98–108, 109–113, 114–899, and 900–953. The file contains no replication backbone, despite its circular metadata. Because the assignment requests a vector context, I prepared a separate v2 version.
The pHT01 DNA copied and provided on 30 September contains 7,956 bp and matches the archived sequence in Addgene Vector Database 5885. The NovoPro annotation variant used for mapping differed, so coordinates were mapped by alignment rather than copied directly.
The provisional design replaces pHT01 interval 2684–2858, a 175-bp segment, with the 953-bp cassette. The resulting length is 7,956 − 175 + 953 = 8,734 bp. DNA outside that interval is retained. The replacement boundaries are design assumptions; they do not yet constitute junction or primer designs ready for ordering.
I imported v2 as RootGuard_pHT01_Pveg_TasA_v2_DRAFT. Its host metadata was initially unsuitable and was corrected to Other, with a description stating that the intended host is B. subtilis and that the production strain has not been selected. Selecting Other documents the metadata choice; it does not validate host compatibility.
6. Linking functional parts to the map
After the initial import, several intervals remained simple annotations. A label such as Pveg in the sequence viewer could select the DNA while its functional part representation was still unlinked. A limited map display therefore did not establish that DNA was missing.
I completed the following workflow:
Opened v2 in the Editor and checked the construct name and length.
Selected an annotated interval and opened Part match to find a matching definition.
Linked the appropriate Pveg and RBS parts to the existing DNA intervals.
When TasA search failed, used the interval menu to create a local part from the existing sequence, selected CDS (+start +stop), saved it, and linked it.
Created and linked the terminator with the Terminator type.
Rechecked construct length, coordinates and orientation to ensure that part linking did not duplicate DNA.
TasA search still returned an error after a refresh at 07:44 on 1 October; repository-limited search also failed at 07:59. The local-part route was identified around 08:15, the CDS type was selected at 08:24, the local part was saved at 08:49, and it was linked in v2 at 09:07. The terminator was saved and linked at 09:20. These persistent search failures led to the local-part workflow.
Evidence captured on 1 October at 09:20 WIB: 8,734-bp v2, five functional parts, host description and repository. Simple and functional labels can overlap because they refer to the same DNA interval.
7. Interpreting validator warnings
At 20:51 on 30 September, v2 displayed 0 errors, 2 warnings. The dialog referred to a promoter/Kozak/UTR imbalance and a local spacer that was not recommended. Its promoter count of zero did not establish that Pveg DNA was missing; the functional promoter representation was incomplete at that stage. The later export includes the correct promoter type.
I did not add Kozak or poly(A) elements to the bacterial design to satisfy a generic validator message. I also retained the terminal TAA rather than removing it because of differences in validator or CDS-type handling. An appropriate stop at the end of a CDS differs from an internal stop in the reading frame.
A more recent complete dialog establishing that both v2 warnings have disappeared is unavailable. The 0 errors, 0 warnings result for the 786-bp candidate belongs to a different object and does not establish that the full v2 construct is free of warnings.
8. Exporting and checking the sequence and map
I exported and checked the v2 GenBank file around 09:30 on 1 October. Its DNA matched the prepared draft exactly; that check passed 16 assertions. The five functional parts had the intended positions and orientations. The native CDS, backbone flanks and RBS–spacer–ATG junction remained consistent.
The Kernel PNG was received around 10:09. The original PNG does not show part names, so the report pairs it with a coordinate table and a labeled editor screenshot. The PNG is retained without modifying its contents.
A digital map; it does not establish that protein or biofilm has been produced.
On 2 October, I rechecked the recovered files. All 25 local checks passed, covering CDS identity, translation, length, typed annotations, unchanged flanks and codon changes. The results are recorded in the reverification JSON. This was a local file check, without rerunning every Kernel tool or generating new experimental results.
9. Interpreting 100% and 93.4% sequence-search results
The successful route used Kernel global search, including Cmd+K on Mac, followed by pasting the complete CDS. After the BLAST results appeared, I checked hit names, repositories, percentage identity, and query and subject lengths and coordinates.
The native CDS showed 100% identity across 786 bp to BBa_K1701005 on 30 September. The synonymous candidate showed 93.4% identity across 786 bp at 12:25 on 1 October because 52 of its 786 bases had changed. Translation of the local files showed the same protein sequence: a DNA change does not necessarily change the encoded protein.
The candidate also produced a 100% local self-match. This helped identify the object but was not independent confirmation. The search covers repositories indexed by Kernel; I do not describe it as an independent BLAST search across the entire NCBI database. The displayed E value of zero is the tool’s numerical presentation, not a statement that the probability is exactly zero.
10. Codon optimization: constraint, alternative and evidence limits
The visible Simple v0.3 menu offered Chinese hamster, human, E. coli and yeast. No B. subtilis option appeared. I asked Kernel AI in English to keep the control names clear, but its response did not establish an available Bacillus option. I did not select another organism as an equivalent host.
The external alternative used DNA Chisel, the match_codon_usage method, the b_subtilis_1423 table and seed 20261001. The candidate retains ATG, TAA and all 261 aa. Its results were:
Check
Result
Length
Unchanged at 786 bp
Protein
Identical, 261 aa
Changed bases
52 substitutions
Changed codons
47 synonymous codons
GC
37.66% → 42.49%
Longest homopolymer
6 → 7 bases
Profile-matching objective
−88.18 → −12.36; not CAI or measured expression
I imported the candidate as a separate object. Its host metadata was corrected to Other, with the intended Bacillus host described. The 11:59 screenshot is consistent with the local file’s length and GC content; the editor validator showed zero errors and zero warnings.
The displayed melting temperature of 98.78°C is not interpreted as a bacterial growth temperature; the calculation conditions were not shown. The candidate remains a CDS-only comparison. A complete candidate re-export from Kernel has not been compared with the source-file hash, and instructor acceptance of the external optimization alternative remains unconfirmed.
11. SecureDNA results and interpretation
The visible route was Tools → Biosecurity sequence scanner, using SecureDNA and Scan for Biohazards. The v2 workflow was checked at 09:54, and the candidate at 12:14, on 1 October. Both screens displayed No flagged sequences detected. V1 had previously also returned a no-flags result.
The intended nucleotide input was the complete v2 sequence or the complete candidate. The sequence ends visible on screen were consistent with the files, but the interface did not provide a full-input hash, an independent length count or a database version. The report therefore limits its conclusion to the screen evidence available.
A no-flags sequence result does not establish TasA expression, matrix formation or the safety of a living strain for environmental use. The official tool documentation provides further context.
12. Timeline and publication record
Date / time
Event
Result or decision
29 September
CDS and parts assembled as v1
953-bp cassette without a plasmid backbone
30 September, 17:15
Native sequence search
K1701005 match: 100% across the complete 786 bp
30 September, 19:23–20:26
pHT01 DNA checked; v2 prepared and imported
8,734-bp v2 with provisional replacement boundaries
30 September, 20:51
Host metadata corrected; validator reviewed
0 errors, 2 warnings; no eukaryotic elements added to the bacterial design
1 October, 06:58–09:20
Functional parts corrected and linked
Pveg, RBS, local TasA and local terminator available
1 October, 09:30–10:09
GenBank QC, v2 screening and PNG export
Matching exported DNA; no screening flags; PNG received
1 October, 11:14–11:59
Limited optimizer host options; external comparison and candidate import
Separate CDS-only candidate encoding the same protein
1 October, 12:14–12:25
Candidate screening and search
No flags; public hit 93.4%; local self-match 100%
2 October
Reverification and package revision
Consistent local files; Parts 0–6 narrative and evidence updated
2 October, 20:34 WIB
Main-report revision committed and published
Commit a019cc5431192135213c789370ce6617d920201e; server time 13:34:23 UTC, equivalent to 20:34:23 WIB
2 October, after the commit
Live publication checked
Revision date 2 October 2026 and Parts 0–6 visible; seven report images and five documentation images loaded (10 unique images combined); 21 unique downloads identical to local file bytes
2 October
Publication documentation finalized
Follow-up commit d5871fe8d9c1e47b75a6f709ae1e6e182b2bb2d4 recorded the publication and corrected documentation backlinks
2 October
English translation prepared
Documentation translated into English; the preceding publication checks refer to revisions published before this translation
V1 was published on 30 September. The revised HW2 report was subsequently published through the browser to the course repository on 2 October 2026. The main-report commit records the revision that replaced the earlier narrative. The live HW2 report and live documentation page were both accessible. Publication documentation was finalized in the follow-up commit.
The live checks showed the revision date and Parts 0–6, all seven inline images in the main report, and all five inline images in the documentation (10 unique images across both pages). All 21 unique downloads from the main report matched local files byte-for-byte in the initial post-publication check. A screenshot of the public page was saved as HW2_published_2026-10-02.png among the accompanying output files. Successfully loaded live pages provide evidence of the build output; build logs were not inspected. The two documentation backlinks to the main report were changed to absolute URLs because Hugo had routed the previous ../ links to the homepage. The evidence manifest and package checksums were aligned with the publication record. These checks describe the published revisions preceding this English translation.
13. Evidence checklist and remaining work
Evidence
Status at this revision
Repository and folder names, and construct ID
Recorded in screenshots and the report
Typed parts, positions and orientations
Recorded in v2 screenshots and GenBank
Native CDS and protein, start/stop codons and reading frame
Recorded in FASTA and QC files
Native and candidate sequence searches
Recorded in original screenshots
Optimizer host list and alternative method
Documented; Bacillus-specific optimization in Kernel remains incomplete
Before/after codon comparison
Recorded in QC, CSV, script and table snapshot
Candidate statistics and validator
Recorded; distinct from the full-v2 warning state
V2 and candidate screening results
Recorded, with limits on input provenance
Original Kernel PNG
Retained; interpreted alongside the coordinate table and labeled screenshot
Biological measurements
Unavailable; the proposed measurements remain a validation plan
Revision commits and live pages
Main and publication-documentation commits recorded; both live pages accessible
Report and documentation images
Seven and five inline images loaded; 10 unique images combined
Main-report downloads
21 unique downloads identical to local bytes in the initial post-publication check
Evidence of build output
Live pages loaded successfully; build logs were not inspected
Publication and live-page checks for the preceding revisions are complete. Two course requirements still need confirmation: workspace naming and membership for HTGAA versus HTBAA 2026, and a Bacillus-specific optimization route in Kernel or instructor acceptance of the external alternative. Strain selection, TapA/SipW requirements, regulatory-part performance, vector boundaries and retention on biochar remain validation questions stated in HW2. Publication does not establish the design’s biological function.
I can proceed with Homework 3 while seeking confirmation of those two HW2 requirements. HW3 specifies a protein target, so this next assignment does not require waiting for changes to the RootGuard plasmid. Class notes, a glossary and study materials can be developed alongside that work.
Sources and AI assistance
The primary sources are the HW2 handout, syllabus, supplied HW1 material/PDF, NCBI/iGEM/vector/software references linked in the main report, actual export files, supplied screenshots and the Notion journal. This record was prepared with ChatGPT by OpenAI; Kernel AI was used to ask about host support. Examples of the requests and the complete English Kernel AI prompt are included in the package. A control that was not observed is not reported as having been used successfully.
I also used Codex desktop (OpenAI) on 2 October 2026 to recover the material, check coverage of Parts 0–6, review file consistency and prepare the upload package. No new optimization run, screening run or experiment was performed in this session. The original request was written in Indonesian; the following is an English translation of that request:
Please prepare the fully revised write-up, including documentation and results, answering every requirement and question in Homework 2, as Markdown for the website or as the files that need to be included on the site. Can the finished version also be uploaded directly?
Codex subsequently assisted with publishing the revision through the browser and checking the live pages on the same date. The following is an English translation of the original Indonesian publication request:
Can you help me promptly publish this Homework 2 assignment to the website, replacing the previous version?
This documentation was then translated into English on 2 October 2026. The English renderings of the two requests above are translations, not verbatim English prompts. The linked Kernel AI prompt remains in its original English wording.
Week 3 HW: Cell-Free Reaction Design
Homework 3: Cell-Free Reaction Design
Student: Naufal Tsabitul Azmi Last updated: 8 October 2026 (WIB; evidence and documentation update) Initial submission: 5 October 2026 (WIB) Assignment due: 6 October 2026, as stated in the official HW3 handout.
I compared two published cell-free formulations and submitted three initial 20 µL CFPS design hypotheses: a magnesium adjustment for sfGFP, a modest DsbC reduction for TfCut2/PETase, and a modest DsbC increase for Reteplase. The save confirmations and target groupings were verified on the class Coopetition platform. I also upvoted a Community Reagent and verified access to the class discussion channel. I did not conduct laboratory experiments for this submission; no new protein yield, enzyme activity, or experimentally improved cost is claimed.
The objective is to reduce cost per functional protein output, which depends on both mixing cost and the amount of active product. The reactions use Ginkgo-supplied lysate and target DNA. PETase here is Thermobifida fusca cutinase 2 (TfCut2), and Reteplase requires a disulfide-compatible framework. My three designs are small changes from target-specific reference presets. Each proposed change is intended to be evaluated against its unchanged reference under matched assay conditions. No results from an experimental comparison of these designs were found in the evidence reviewed for this report. Official assignment and target framework.
Completion record
Assignment component
Completion and evidence
A1: salt concentrations and sensitivity
Answered below with Jewett and Swartz Table II, including its concentration basis and limitations
A2: PEP + NTP versus ribose + NMP
Answered below with original PANOx-SP and RFopt sources
A3: two literature formulations
Full component comparison and experimental-context discussion below
B1: one initial composition per target
Three save confirmations and target groupings verified on 5 October 2026; record IDs and exact submitted inputs below
B2: Community Reagents
FkpA upvote verified on 5 October 2026: count 3 → 4 and “Remove your vote” displayed
B3: discussion access
cfps-coopetition forum access verified on 5 October 2026; no forum message posted
C: optional Asimov Kernel plasmid work
Not undertaken in this submission
Laboratory outcomes
No results for these designs were found in the reviewed evidence; their hypotheses remain unvalidated here
UI costing
Original paired estimates retained; PETase and Reteplase loaded-copy discrepancies observed on 8 October remain unresolved
Evidence status as of 8 October 2026
“Verified” below refers to the specific document, input check, or platform readback. It does not mean that the reactions have been run or their performance validated.
Evidence category
What this report can establish
Verified records and input checks
The three saved records remain traceable under their corresponding targets. The archived submitted inputs pass the documented 20,000 nL total, 25 nL dispensing-increment, fixed-component, and DNA-target checks. The public report and its three JSON files plus submission screenshot are accessible.
Supported by literature or the platform
The papers and class presets support formulation choices and folding considerations. Stock labels and the official buffer specification support nominal concentration calculations. UI prices support dated estimates only. The proposed benefits of magnesium and DsbC changes remain hypotheses; published yields and FkpA results belong to the cited authors and their experimental systems.
Not yet verified
Experimental yield or activity, improved cost per functional output, definitive costs of the saved records, community-wide uniqueness, plate allocation, laboratory execution, and a full supplementary/Source Data audit or raw-data reanalysis.
The detailed process and decision log and the dated cost observations below distinguish submission evidence from these unresolved items.
A. Compare cell-free reaction compositions
A1. Potassium and magnesium glutamate
Assignment question: Why does the concentration of potassium glutamate and magnesium glutamate differ between compositions? Which is more sensitive?
Potassium and magnesium glutamate help establish the ionic environment in which cell-free transcription and translation operate. Their useful concentrations depend on the whole formulation, including the lysate, its carried-over salts, nucleotides, energy substrates, and metabolites that accumulate during the reaction. A concentration optimized for one system should therefore be re-evaluated when those conditions change. Jewett and Swartz explicitly reoptimized magnesium when replacing PEP with pyruvate because PEP has a stronger affinity for magnesium and the expected phosphate accumulation also changes. Jewett & Swartz, 2004, PDF pp. 4–5, Tables I–II.
Magnesium was more sensitive around the optimum tested in their PANOx-SP system. Increasing added magnesium glutamate from 20 to 24 and 28 mM reduced normalized total CAT expression from 1.00 to 0.73 and 0.39. Increasing potassium glutamate from 175 to 200 and 225 mM reduced the corresponding values from 1.00 to 0.94 and 0.92. The magnesium response was therefore sharper in this experiment. Potassium still mattered: at 100 mM potassium glutamate, the relative yield was only 0.63. This supports a formulation-specific sensitivity conclusion rather than a universal statement that potassium is unimportant.
Solute varied individually
Added concentration, mM
Relative total CAT expression
Magnesium glutamate
20
1.00
Magnesium glutamate
24
0.73
Magnesium glutamate
28
0.39
Potassium glutamate
175
1.00
Potassium glutamate
200
0.94
Potassium glutamate
225
0.92
These are the authors’ measurements from Table II, using 15-µL PANOx-SP reactions at 37°C for 3 h, with one solute varied at a time. The magnesium values are additions: approximately 3.3 mM magnesium was also carried over from the extract. Nominal added or total magnesium must not be confused with measured free Mg²⁺. The data concern CAT in the paper’s system and do not establish the optimum for sfGFP, TfCut2, or Reteplase. Jewett & Swartz, Table II, PDF p. 4.
Design implication: salt optimization should be considered together with the energy/nucleotide strategy and the defined contributions from the class base buffer, rather than copying a literature value as an additional stock concentration.
A2. PEP + NTP versus ribose + NMP
Assignment question: Explain how a PEP+NTP reaction formulation is different from a Ribose+NMP reaction formulation.
The original PANOx-SP formulation adds phosphoenolpyruvate (PEP) as a phosphorylated energy substrate and supplies nucleotide triphosphates: ATP, GTP, UTP, and CTP. These provide nucleotide building blocks and support the energy-demanding transcription/translation system. ATP regeneration is supported by the supplied energy substrate and the enzymes present in the extract. PEP-based reactions can accumulate phosphate and experience pH changes; these effects are part of the chemical environment that must be optimized. Jewett & Swartz, Methods and homeostasis discussion, PDF pp. 2, 5–6.
Olsen’s RFopt instead uses ribose, glucose, phosphate, nucleotide monophosphates (AMP, GMP, UMP, and CMP), and other supporting components. No exogenous NTPs are listed in baseline RFopt. The reaction still requires NTPs: it relies on the lysate’s metabolic and nucleotide-regeneration activities to supply them. Thus, “no added ATP” does not mean “no ATP is required,” and ribose alone is not a direct replacement for every function of NTPs. Olsen et al., Table 1 and Fig. 2, PDF pp. 3, 5.
Aspect
Original PANOx-SP: PEP + NTP
RFopt: ribose + NMP
Added energy-related substrates
PEP, 33 mM
Ribose, 50 mM; glucose, 10 mM; phosphate, 15 mM
Added nucleotide form
ATP 1.2 mM; GTP/UTP/CTP 0.85 mM each
AMP 3 mM; GMP/UMP/CMP 2.15 mM each
ATP/NTP availability
Added NTPs plus regeneration supported by the energy system
Regeneration from the supplied substrates and endogenous lysate activities
Chemical interactions to consider
Magnesium binding, phosphate accumulation, and pH changes
Metabolic capacity, oxygen transfer, phosphate balance, and pH
Cost rationale
Phosphorylated energy substrates and NTPs can be substantial reagent expenses
Less expensive inputs can lower cost when functional output is maintained
Evidence needed for a new design
Functional yield and cost under the chosen conditions
Functional yield and cost under the chosen conditions
In Olsen’s own comparison, RFopt generated ATP despite starting without added ATP and maintained ATP around 250 µM, while phosphate remained approximately 10–15 mM during the measured reaction. Its PEP-based comparator showed a different ATP/phosphate profile. These observations support the importance of sustained metabolism and homeostasis. They are results under Olsen’s conditions, and the comparator reported by Olsen is a different implementation from the original 2004 PANOx-SP recipe. Olsen et al., Fig. 2, PDF p. 5.
Design implication: a ribose/NMP strategy is a plausible cost-focused baseline, but its performance depends on the lysate and reaction environment. It must be adapted to the class inventory and evaluated using functional output, rather than assumed to work because it uses cheaper ingredients.
A3. Comparison of two literature formulations
Assignment question: Choose two cell-free reaction compositions from the literature, compare and contrast the choice of reagents and the concentration of reagents.
I compare the original PANOx-SP formulation reported by Jewett and Swartz (2004) with RFopt reported by Olsen et al. (2026). The first represents a PEP/NTP-based strategy; the second represents a later ribose/NMP-based strategy optimized for low reagent cost and high sfGFP production.
The comparison uses Jewett’s original Methods/Table I, rather than substituting the PANOx-SP comparator column printed in Olsen’s Table 1. Those reported implementations differ: for example, original PANOx-SP contains 175 mM potassium glutamate and 20 mM added magnesium glutamate, while Olsen’s comparator column lists 130 and 8 mM, respectively. Keeping the versions separate makes the concentration comparison traceable. Jewett, PDF p. 2, Olsen, PDF p. 3.
Reading the table: concentrations are nominal amounts in the assembled reaction, not stock concentrations or measurements of free ions. “Not added” means no exogenous addition is specified; it does not mean that the molecule is absent from the lysate. Values are mM unless another unit is shown.
Component
Original PANOx-SP, J04
RFopt, O26
Potassium glutamate
175 mM
362 mM
Magnesium glutamate
20 mM added
8 mM listed
Ammonium glutamate
10 mM
Not added
Magnesium acetate carried from extract
Approximately 3.3 mM
Final carryover not quantified in Table 1
Potassium acetate carried from extract
Approximately 14.4 mM
Final carryover not quantified in Table 1
HEPES
0 added
75 mM
PEP
33 mM
Not added
Glucose
Not added
10 mM
Ribose
Not added
50 mM
Phosphate supplement
Not added
15 mM
Nicotinamide
Not added
4 mM
ATP
1.2 mM
Not added
GTP, UTP, CTP
0.85 mM each
Not added
AMP
Not added
3 mM
GMP, UMP, CMP
Not added
2.15 mM each
Each of the 20 standard amino acids
2 mM
5 mM
Spermidine
1.5 mM
Not added
Putrescine
1 mM
Not added
Sodium oxalate
2.7 mM
Not added
NAD
0.33 mM
Not added
Coenzyme A
0.26 mM
Not added
Folinic acid
34 µg/mL
Not added
Exogenous E. coli tRNA mixture
170.6 µg/mL
Not added
Separate purified T7 RNA polymerase
100 µg/mL
No separate addition specified
PEG-8000
0% w/v added
Not added
Lysate fraction
24% v/v
30% v/v for baseline experiments
Plasmid DNA mass concentration
13.3 µg/mL
13.3 ng/µL, equivalent to 13.3 µg/mL
Jewett also reports extract contributions of approximately 2.4 mM Tris and 23.5 mM acetate. Original PANOx-SP therefore contains approximately 23.3 mM magnesium from its stated added glutamate salt plus extract carryover; this is not free Mg²⁺. RFopt’s Table 1 does not provide an equivalent quantified carryover correction. The class lysate fraction is fixed at 25%, so neither paper’s extract fraction can be transferred unchanged. Jewett, Methods/Table I, class specification.
Comparison and interpretation
Energy and nucleotide strategy. Original PANOx-SP uses PEP and externally added NTPs, whereas RFopt uses ribose/glucose/phosphate and NMPs. This changes the metabolic demands and the chemical environment, so the salt composition must also be considered.
Reagent choice and concentration. RFopt omits several separately supplied components listed in original PANOx-SP, including NAD, CoA, folinic acid, tRNA, and polyamines. At the same time, RFopt contains more potassium glutamate and amino acids, plus 75 mM HEPES. Low cost therefore does not mean reducing every concentration; it means choosing a productive combination and avoiding costs that do not improve the relevant output.
Experimental context. Jewett used CAT and an engineered K12-derived S30 extract at 37°C. Its Table II optimization used 15-µL reactions for 3 h, while other comparisons tracked reactions over 6 h. Olsen’s baseline RFopt measurements used sfGFP and BL21 Star (DE3) lysate, generally 15-µL reactions at 30°C for 20 h. Different proteins, lysates, temperatures, durations, and geometries prevent these literature results from being treated as a controlled head-to-head comparison of our two selected original recipes.
Results and cost scope. Olsen reports RFopt at 2.39 ± 0.28 g/L sfGFP, with reagent cost of USD 143 per liter of reaction and approximately USD 60 per gram of protein. These are the authors’ results and exclude lysate and DNA costs. Jewett’s original composition table does not supply the same modern costing basis, so I do not assign it a cost using Olsen’s differently composed comparator. The CAT expression measurements in Jewett and sfGFP measurements in Olsen should also retain their respective definitions and assay contexts. Olsen, Table 1, Jewett, Table II and Fig. 4.
Application to HW3. RFopt is a useful candidate baseline for a cost-focused design, but the class supplies fixed lysate, DNA, and base buffer. That base buffer already contributes salts, HEPES, and amino-acid components. Literature concentrations must therefore be converted into additions only after checking the actual inventory and those existing contributions. Reteplase also requires the prepared DSB framework and target-specific folding considerations; baseline RFopt is not the same formulation as oxidized RFopt. No published result above establishes that a new class composition will produce functional protein.
B. Design and participation
B1. One reaction composition for each target
Assignment: publish a first unique 20 µL CFPS composition for sfGFP, PETase, and Reteplase, and explain the reagents adjusted from the relevant categories. I designed one reagent perturbation from each target-specific preset and balanced the volume with water. These are proposed one-factor-at-a-time comparisons. No experimental evaluation of these proposals was found in the evidence reviewed for this report. Other energy substrates, building blocks, salts, cofactors, and redox components were retained from the corresponding reference unless explicitly changed below.
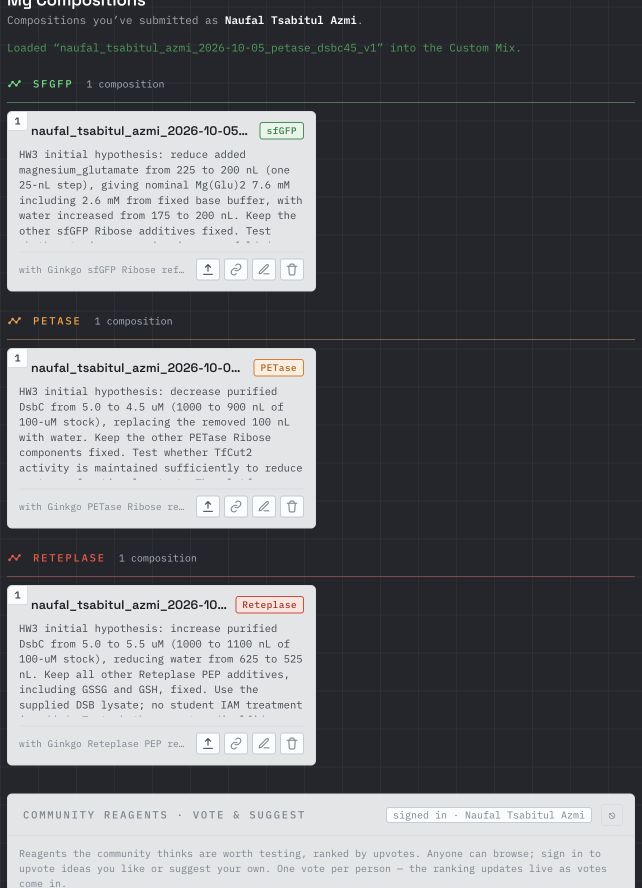
The three entries were saved and grouped under their corresponding targets in My Compositions. Each differs from its reference preset; I did not perform an exhaustive community-wide duplicate audit. The downloadable JSON files preserve the submitted inputs and are not raw server exports. Reloading a saved additive mix into Custom Mix can assign a new sample ID, reset metadata, and retain the currently selected DNA target, so that view alone does not verify a record’s saved target or final cost.
Archive qualification: the Submitted JSON files remain unchanged as historical inputs paired with the 5 October save evidence. Their comments contain the original cost estimates; the dated cost note below records subsequent unresolved display differences. The record links above open loaded copies and should be read with this limitation.
All three reagent lists total exactly 20,000 nL. Every volume is a multiple of 25 nL. Each contains fixed base buffer 2000 nL, lysate 5000 nL, and exactly one target-matched DNA template 2000 nL; additives plus water total 11,000 nL. PETase/TfCut2 uses template_petase; Reteplase uses template_reteplase. The local JSON target keys were corrected to match the official specification.
Interface pitfall: loading a preset does not automatically switch the DNA/protein target. Check both the selected protein target and the exported template_* key before submission. A PETase or Reteplase preset can otherwise retain the previously selected sfGFP template. Matching fixed volume alone cannot detect this error.
Concentration basis
Stock labels for variable reagents come from the visible public DOM snapshot captured on 5 October 2026. DNA and base-buffer stock values come from the official specification. Nominal final concentration = stock concentration × reagent volume / 20,000 nL, plus any defined base-buffer contribution. The fixed buffer contributes HEPES 30 mM, potassium glutamate 200 mM, magnesium glutamate 2.6 mM, amino-acid mix 1 mM, and cysteine 1 mM. Tyrosine is represented within the base-buffer amino-acid contribution; the platform displays 1 mM tyrosine with no separate addition in these recipes. Listed amino-acid-mix levels are nominal mixture/per-component levels, not a sum across all amino acids. Base-buffer contributions are already included in affected table rows and must not be added twice. Unknown endogenous lysate contributions and free-ion concentrations are not determined by this calculation; potassium-glutamate concentration is not total potassium concentration. Folinic acid stays in mg/mL because that is the verified stock unit.
Cost estimates and unresolved display differences
The table preserves the paired UI estimates recorded on 5 October 2026, including the rounded costs visible immediately after the respective save confirmations. These estimates describe the reaction as mixed, not a full procurement or project budget. They do not represent a bottle purchase, minimum order, shipping, labor, capital, or complete downstream workflow. USD per 20 µL reaction is calculated as the displayed USD/mL × 0.020 mL; source values are rounded.
Preset
Baseline USD/mL
Submitted-mix snapshot USD/mL
Baseline USD/20 µL
Submitted-mix snapshot USD/20 µL
sfGFP / sfGFP Ribose
$5.79
$5.79
$0.1158
$0.1158
PETase / PETase Ribose
$339.64
$311.48
$6.7928
$6.2296
Reteplase / Reteplase PEP
$344.46
$372.62
$6.8892
$7.4524
Loaded-copy observations on 8 October 2026:
Saved-record link used
Custom Mix copy USD/mL
Calculated USD/20 µL
Check in the editor
PETase/TfCut2, ov0n7790fzd7f99
$306.69
$6.1338
Display remained after selecting PETase and template_petase
Reteplase, sfvi72kwto5mmc6
$377.47
$7.5494
Display remained after selecting Reteplase and template_reteplase
An earlier PETase reload had retained the editor’s then-current Reteplase template. The 8 October checks show that selecting the corresponding target and DNA template did not resolve the observed price differences. These loaded copies generated new sample IDs and reset metadata; they are not raw server exports. The cause remains unresolved, so these observations do not establish definitive costs for the saved records.
The 91.7% PETase and 108.2% Reteplase thresholds below remain conditional calculations from the original paired estimates. They have not been recalculated from loaded-copy prices because matching reference costs were not established in those checks. Neither experimental activity nor improved cost per functional output has been established. Final costing requires a reconciled, target-matched reference/design pair under the same pricing basis.
B1.1. sfGFP: one-step magnesium adjustment
Reference: sfGFP Ribose (sfGFP_R2PC_054).
Submitted sample ID:naufal_tsabitul_azmi_2026-10-05_sfgfp_mg76_v1. Platform record ID:14sqepz2b15y1o0.
Change: Supplemental magnesium glutamate: 225 → 200 nL; water: 175 → 200 nL. Nominal final magnesium glutamate: 8.225 → 7.600 mM, including the fixed base-buffer contribution.
Hypothesis: A one-droplet reduction in supplemental magnesium may preserve or improve folded sfGFP production by changing the ionic environment of the ribose/NMP formulation. Magnesium is sensitive to formulation context, so the direction of any effect remains unknown. The direct salt saving is small; the primary test is functional output relative to reaction cost.
Risk: A small volume step can still move the reaction away from its magnesium optimum. Nominal magnesium concentration does not measure free Mg²⁺, and the optimum from another energy system or lysate cannot be assumed here.
Planned evaluation: Use endpoint sfGFP fluorescence with the appropriate protein standard curve and plate controls; compare with the unchanged sfGFP Ribose reference under the same conditions.
Conditional break-even: The UI rounds baseline and draft costs to the same $5.79/mL. At that displayed precision, functional sfGFP output must exceed baseline to improve cost per functional output; the tiny underlying salt saving is not resolved by this rounded display.
Submitted sample ID:naufal_tsabitul_azmi_2026-10-05_petase_dsbc45_v1. Platform record ID:ov0n7790fzd7f99.
Change: DsbC: 1000 → 900 nL of the displayed 100 µM stock, giving 5.0 → 4.5 µM; water: 225 → 325 nL. Other additives remain fixed.
Hypothesis: Reducing DsbC supplementation by 10% may retain enough folding assistance for TfCut2 while lowering reaction cost. Its single disulfide bond motivates a conservative dose test; it does not establish that DsbC is unnecessary.
Risk: Reduced folding assistance may lower active enzyme production more than the reagent saving can tolerate. The soluble p-nitrophenyl-ester assay measures esterase activity and does not directly demonstrate hydrolysis of solid PET.
Planned evaluation: Compare the initial PNP assay rate with the unchanged PETase Ribose reference, using consistent dilution, the linear assay range, standards, and controls. Product concentration is an activity proxy, not enzyme mass.
Conditional break-even, using the original paired UI snapshots: activity_new/activity_reference must exceed 0.91709, or about 91.7%, to improve cost per unit activity. A reduction in activity of roughly 8.3% would erase the estimated saving.
Submitted sample ID:naufal_tsabitul_azmi_2026-10-05_reteplase_dsbc55_v1. Platform record ID:sfvi72kwto5mmc6.
Change: DsbC: 1000 → 1100 nL of the displayed 100 µM stock, giving 5.0 → 5.5 µM; water: 625 → 525 nL. GSSG and GSH remain fixed at nominal 4.0375 and 1.0 mM.
Hypothesis: A 10% increase in DsbC may improve disulfide isomerization and the functional fraction of Reteplase, which requires nine correctly paired disulfide bonds. The added folding helper increases reaction cost, so the hypothesis concerns cost per functional activity rather than cheaper mixing.
Risk: Extra DsbC may give little benefit or disturb the reaction; more folding helper does not guarantee correctly paired disulfides. Maintain the supplied DSB lysate and existing GSH/GSSG system. No student IAM treatment is included.
Planned evaluation: Compare the initial AMC-cleavage assay rate with the unchanged Reteplase PEP reference, using the defined assay window, elapsed time, standard curve, and controls. AMC concentration is a product/activity proxy, not Reteplase mass.
Conditional break-even, using the original paired UI snapshots: activity_new/activity_reference must exceed 1.08175, or about 108.2% of baseline, to improve cost per unit activity. The necessary gain is greater than approximately 8.2%.
Assignment: contribute or upvote at least one reagent, explain why it was selected, and link relevant research. I selected an existing FkpA proposal because it tests folding assistance that complements the disulfide-isomerization strategy already used for Reteplase.
FkpA is worth testing as a complementary folding helper because Groff et al. (2014) found that purified FkpA improved antibody-chain solubility in E. coli cell-free synthesis and, together with DsbC, increased assembled IgG production. For HW3, I would test whether adding FkpA to the existing Reteplase DSB formulation increases functional activity sufficiently to justify its additional reagent cost. The study evaluated antibodies, so any benefit for Reteplase remains a hypothesis requiring target-specific activity and cost measurements. Groff et al. (2014), DOI 10.4161/mabs.28172.
Completion evidence: I upvoted FkpA on 5 October 2026. Readback showed “Remove your vote” and the displayed count increased from 3 to 4. FkpA is not present in these three submitted compositions. This records an upvote on an existing proposal; it does not claim a new reagent proposal or a published rationale comment.
B3. Access to the cfps-coopetition discussion
Assignment: visit the dedicated forum channel and ensure discussion access. I verified access to cfps-coopetition on 5 October 2026. Sending an optimization idea is a bonus in the handout. No forum message was posted for this submission.
C. Optional Asimov Kernel work
I did not undertake the optional T7-compatible plasmid construction or the bonus T7 helper-plasmid design in this submission. The three submitted reactions use the supplied target templates. This page makes no plasmid-design completion claim for HW3.
Process documentation and remaining questions
The working process was to read the official assignment and platform specification; compare the primary literature with its original concentration and cost definitions; inspect the available stocks and target-specific presets; make one change per design; balance the water volume; check fixed components, total volume, dispensing increments, and DNA-target identity; submit the three records; and read back the save confirmations and target groupings. Participation was documented by the FkpA upvote readback and forum access check.
The source and decision log is kept in the HW3 journal, the three-design documentation page, and the detailed process and decision log. The detailed log records 27 meaningful steps, 10 decisions, 10 source entries, and the submitted record IDs. These records preserve reasoning and limitations alongside the learning notes.
Two questions remain for subsequent work: reconcile the changing UI cost displays for loaded PETase and Reteplase recipes, and evaluate each hypothesis when controlled assay results become available. The break-even ratios above are calculations from paired UI estimates, not experimental findings. For PETase and Reteplase, PNP and AMC product measurements must retain their activity-proxy interpretation rather than being treated as grams of enzyme.
Recitation preparation
Explain why magnesium sensitivity depends on the complete reaction formulation and distinguish added, nominal total, and free magnesium.
Explain how a ribose/NMP reaction can require ATP/NTPs while adding no exogenous NTPs.
Identify the original PANOx-SP and RFopt source versions and explain why their published outputs are not a controlled head-to-head comparison here.
Describe the single variable changed in each submitted recipe and predict both possible benefits and failure modes.
Show the 20,000 nL volume calculation, 25 nL increments, fixed components, and target-matched DNA templates.
Explain the conditional 91.7% PETase and 108.2% Reteplase activity thresholds, together with the unresolved UI-cost limitation.
Explain why FkpA’s antibody evidence motivates a Reteplase test without proving a benefit for that target.
AI assistance and prompts
AI client: Codex desktop. The specific AI model identifier was not captured in the preparation record. No trained yield-prediction model was built: these designs use literature-guided hypotheses, one-variable perturbations, volume/concentration arithmetic, and conditional cost/activity ratios. AI assisted with reading and extracting the supplied PDFs, explaining the concepts, comparing the literature, checking arithmetic, drafting the design hypotheses and documentation, and operating the authorized submission workflow. The reasoning and evidence need to be understood and explained by the student during recitation, as required by the assignment’s AI-use section.
Sources and downloadable evidence
Official Homework 3 handout: assignment questions, target-specific folding requirements, assays, participation requirements, and AI disclosure.
Class Coopetition designer: reference compositions, visible stock concentrations, submitted-record readback, and UI estimates.
Jewett, M. C., and Swartz, J. R. (2004). Mimicking the Escherichia coli cytoplasmic environment activates long-lived and efficient cell-free protein synthesis. Biotechnology and Bioengineering 86(1), 19–26. DOI 10.1002/bit.20026. Critical source locations: supplied PDF pp. 2 and 4–6; Tables I–II.
Olsen et al. (2026). Design-driven optimization of low-cost reagent formulations for reproducible and high-yielding cell-free gene expression.Nature Communications, DOI 10.1038/s41467-026-69605-8. Critical source locations: supplied PDF pp. 2–7, Table 1, and Fig. 2.
Groff et al. (2014). Engineering toward a bacterial “endoplasmic reticulum” for the rapid expression of immunoglobulin proteins. mAbs 6(3), 671–678. Primary paper, DOI 10.4161/mabs.28172. FkpA/DsbC evidence is from IgG experiments, principally Results and Figs. 3–5.
Smith et al. (2026). Using a GPT-5-driven autonomous lab to optimize the cost and titer of cell-free protein synthesis.bioRxiv preprint, DOI 10.64898/2026.02.05.703998. Background reading on iterative automated optimization; labeled as a preprint.
The supplied main PDFs and critical tables were checked. Supplementary and Source Data files were not included in the supplied reading folder and have not been fully audited or reanalysed for this report. Olsen’s article states that these materials are provided with the publication; this is a limitation of the reviewed source collection. Stock-preparation details not established by the main sources and raw-data reanalysis remain outside this report. Olsen, Data availability, PDF p. 12.
Literature results belong to their authors; the new work documented here consists of comparisons, hypotheses, locally checked compositions, and verified submission/participation records. The 8 October update clarifies evidence status and cost provenance; it adds no experimental results and does not change the three submitted compositions.