Week 2 HW: DNA Design — RootGuard TasA Prototype
Naufal Tsabitul Azmi · HTBAA Fall 2026 · Homework #2
Revised 2 October 2026. Kernel evidence was captured on 29 September–1 October; recovered sequence files were rechecked on 2 October. No wet-lab results are reported.
I designed a TasA expression prototype for my Homework 1 RootGuard concept. The assembled baseline is RootGuard_pHT01_Pveg_TasA_v2_DRAFT, an 8,734-bp pHT01-based construct containing native TasA CDS. Its actual Kernel GenBank export matches the prepared DNA. A separate 786-bp DNA Chisel candidate is a synonymous codon-usage comparison; it has not replaced the baseline.
This report answers Parts 0–6 and documents the available evidence. Host-specific codon optimization inside Kernel remains unresolved, and the exact course-workspace naming/membership also needs confirmation. The observed optimizer form did not offer Bacillus subtilis. I report the external alternative and its limits; instructor acceptance is not assumed. The assignment permits an imperfect design with explicit reasonable assumptions, but that does not waive this tool requirement.
Design brief: connecting HW1 to HW2
HW1 proposes RootGuard, a microbial inoculant carried on co-pyrolyzed cocoa pod husk and okara biochar, for eventual evaluation with maize under water limitation in Sumbawa. Its first goal is reproducible viable-cell loading and survival. Attachment, biofilm formation and plant benefit remain hypotheses. HW2 narrows that concept to a matrix-protein expression design; TasA is one component to investigate, not the complete inoculant.
| Agenda item | Design decision | Evidence or assumption |
|---|---|---|
| Chassis | Bacillus subtilis; production strain not selected | Proposed host from HW1; NCIB 3610 is a sequence reference |
| Input | Constitutive Pveg-driven transcription | DNA design choice; biochar, nutrients and water limitation are conditions, not an encoded sensor input |
| Output | Full TasA protein, intended for extracellular matrix | Coding sequence checked; expression, processing and localization untested |
| Assay | Transcript/protein/localization, then matrix and viable-cell retention | Proposed measurements; no biological assay data |
| Part comparison | Pveg versus original Pgrac context; two RBS candidates; native versus synonymous CDS | Decisions below; no measured performance ranking |
| Minimum construct | Pveg–RBS–spacer–TasA–terminator, within retained vector context | 953-bp cassette in an 8,734-bp computational construct |
| Annotation and order | Typed parts, coordinates, strand, frame and junction checks | Actual Kernel GenBank and local QC |
| PNG export | Actual Kernel schematic plus a labeled editor screenshot | Included below |
| Homework Review | Workspace, optimizer alternative and host/vector assumptions | Questions at the end |
Part 0 — Set up in Kernel
My Kernel repository is RootGuard-HTBAA2026, and my folder is azmi-rootguard-tasa. The baseline construct is RootGuard_pHT01_Pveg_TasA_v2_DRAFT, ID 306fda68-569a-4502-9a08-7cf18035d57e.
I explored existing parts and constructs. A part has an assigned biological role, such as promoter or CDS; a construct holds an assembled sequence and its annotations. A CDS imported into a construct container is still CDS-only unless vector DNA is actually present. I used the editor, functional part linking, sequence search, checker, sequence statistics, schematic export, Biosecurity sequence scanner and Kernel AI.
The screenshots show a workspace called HTGAA 2026, whereas the handout asks for HTBAA 2026. Repository and folder creation are documented; membership in the exact requested workspace needs course-team confirmation. The process documentation records the sequence of decisions and errors; the Notion journal retains the broader screenshot history.
Part 1 — Define the expression target
What molecule am I expressing?
TasA, a protein, is the selected expression target. The proposed role is to investigate one protein component of extracellular matrix in the RootGuard chassis. I am not encoding biochar synthesis, a complete biofilm pathway, drought sensing or a proven plant-growth effect.
What is the sequence, and where does it come from?
The sequence reference is B. subtilis NCIB 3610, chromosome NCBI NZ_CP020102.1, annotated feature complement(2553102..2553887), protein WP_004398632.1. The 786-bp native TasA CDS, including start and stop, matches iGEM BBa_K1701005 in the recorded full-length search. Download the complete native CDS and 261-aa protein sequence.
The imported strain-168 CDS is identical in this comparison. Consequently, the CDS match does not identify a strain background or prove that NCIB 3610 is the best production strain. NCIB 3610 remains the documented sequence source.
The chromosome feature lies on the reverse strand. For the construct, the CDS is represented in its own 5′→3′ coding direction, using the reverse complement of that chromosome interval. It starts ATG, ends TAA, contains 262 codons including the stop, and translates to 261 amino acids with no internal in-frame stop.
What is the chassis?
The intended expression host remains B. subtilis, consistent with HW1. An actual production strain still needs selection and qualification. I therefore do not claim that a named strain has been engineered, cultured or validated. Kernel metadata uses Other, with the intended Bacillus host stated in the description; a generic menu choice does not establish biological compatibility.
Where should the protein go?
The desired destination is extracellular matrix. I retain the full native N-terminal region and add no separate signal peptide or tag. Processing/export and the relevant SipW/TapA/matrix context must be checked in the eventual strain. The biological literature describes SipW-associated processing and matrix regulation in this system; it does not demonstrate performance of my construct. Terra et al. (2012), DOI 10.1128/JB.06780-11.
Part 2 — Design and compare the parts
Selected parts: type, sequence, source and justification
All expression-cassette sequences are supplied in the functional-parts FASTA. The annotation TSV pairs each sequence with its type, source, direction and coordinates. The complete reused vector context is included in the actual GenBank and reference FASTA.
| Short name | Kernel part type | Sequence / length and source | Why use it for this host and target? |
|---|---|---|---|
| Pveg | Promoter | 97 bp; BBa_K143012 | Constitutive Bacillus-oriented prototype; gives a simple starting design without specifying an inducer |
| RBS K090505 | Ribosome binding site | AAAGGAGGTGT, 11 bp; BBa_K090505 | Candidate bacterial translation-initiation element; its effect with TasA must be measured |
| Spacer v1 | 5′ UTR | AATTA, 5 bp; local design | Separates the selected RBS and ATG; spacing remains an explicit assumption |
| Native TasA | CDS (+start +stop) | 786 bp; NCBI reference and BBa_K1701005 | Encodes the documented full 261-aa TasA target without redesigning its protein sequence |
| Terminator K780000 | Terminator | 54 bp; BBa_K780000 | Provisional transcription-stop element; termination/read-through in the selected host is untested |
| pHT01 context | Reused vector context | Original 7,956-bp reference FASTA; sequence record Addgene Vector Database 5885 | Supplies a Bacillus/E. coli shuttle-vector context; retained regions require physical-vector and boundary review before construction |
The Pveg and terminator sequences, extracted from the actual Kernel export in forward orientation, are:
There is no extra targeting element, because the full native N-terminal sequence is retained. There is no eukaryotic Kozak or poly(A) design: this is a bacterial expression cassette.
Candidate part comparison
| Layer | Selected candidate | Alternative | Decision and remaining uncertainty |
|---|---|---|---|
| Transcription | Constitutive Pveg | Original pHT01 Pgrac/lac-controlled expression context | Keep Pveg for continuity with v1 and a simple prototype; constitutive expression may cause burden, and no strength comparison has been measured |
| Translation initiation | K090505: AAAGGAGGTGT | K090506: AGAGGTGGTGT | Keep K090505 as the initial candidate; test otherwise matched RBS/spacer variants rather than infer strength from the name |
| Coding sequence | Native 786-bp TasA CDS | External synonymous codon-usage candidate, also 786 bp | Native remains in assembled v2; the candidate tests a codon-usage hypothesis and is not a proven expression improvement |
The selected RBS has a nominal AAAGGAGG core followed by TGT; with the designed AATTA spacer, this gives a nominal eight-base interval before ATG. This is a sequence description, not proof of optimal initiation spacing or mRNA structure.
Replication and selection context
The copied 7,956-bp pHT01 DNA matches the archived Addgene vector sequence. This verifies the digital sequence relationship, not a physical clone or present-day purchasing availability. The MoBiTec Bacillus vector manual describes shuttle-vector use and chloramphenicol/ampicillin selection context. The design retains reference-mapped cat/CmR, bla/AmpR, lacI and replication-associated regions outside the replacement.
ColE1 is the E. coli replication-origin annotation. Minimal Bacillus origin boundaries are not assigned here. Marker/regulator annotations remain mapped reference regions, not newly validated complete CDS models. I would confirm the exact vector and its Bacillus replication/selection context before physical construction.
Part 3 — Assemble the minimum construct and check direction
The expression order is Pveg → RBS → spacer → full native TasA CDS → terminator, within the pHT01-derived context. The original 953-bp v1 contained this cassette only. Its circular topology metadata did not supply a replication backbone. Current v2 contains 8,734 bp.
| Functional annotation | Coordinates in v2, 1-based inclusive | Length | Direction |
|---|---|---|---|
| Pveg_BBa_K143012 | 2684–2780 | 97 bp | Forward |
| RBS Candidate BBa_K090505 | 2781–2791 | 11 bp | Forward |
| Spacer_RBS_tasA_5nt_v1 | 2792–2796 | 5 bp | Forward |
| TasA_BBa_K1701005_local | 2797–3582 | 786 bp | Forward |
| Terminator_BBa_K780000_local | 3583–3636 | 54 bp | Forward |
I provisionally replaced pHT01 2684–2858, a 175-bp reference-mapped expression interval, with the 953-bp cassette: 7,956 − 175 + 953 = 8,734 bp. The left 2,683 bp and right 5,098 bp are unchanged. The replacement boundaries are engineering assumptions, not validated assembly junctions. Reference annotations were mapped by aligning an annotated NovoPro pHT01 variant to the exact copied DNA; differing variants were not assigned identical coordinates blindly. Residual lacI context remains.
Sequence-level checks and result
The actual Kernel GenBank export was checked against prepared v2 DNA. The original 1 October export QC passed 16 assertions. A separate 2 October re-verification passed 25 local checks, including length, unchanged flanks, cassette/CDS identity, typed forward annotations, start/stop, translation and the native–candidate comparison.
The RBS–spacer–start junction is AAAGGAGGTGT–AATTA–ATG. TasA is divisible by three, starts and stops at the intended positions, and has no accidental internal stop in its reading frame. Whole-v2 GC is 40.26%; native-CDS GC is 37.66%. Normalized v2 DNA SHA-256 is 23c372fad614d39adb670cf5291f002524fd956d518e39186b48047c7d81eba1. This DNA hash is distinct from the hash of the GenBank file bytes.

Figure 1. Actual Kernel PNG export, unchanged. Part-name labels are absent from this transparent export; the table above and labeled editor screenshot below supply the legend.
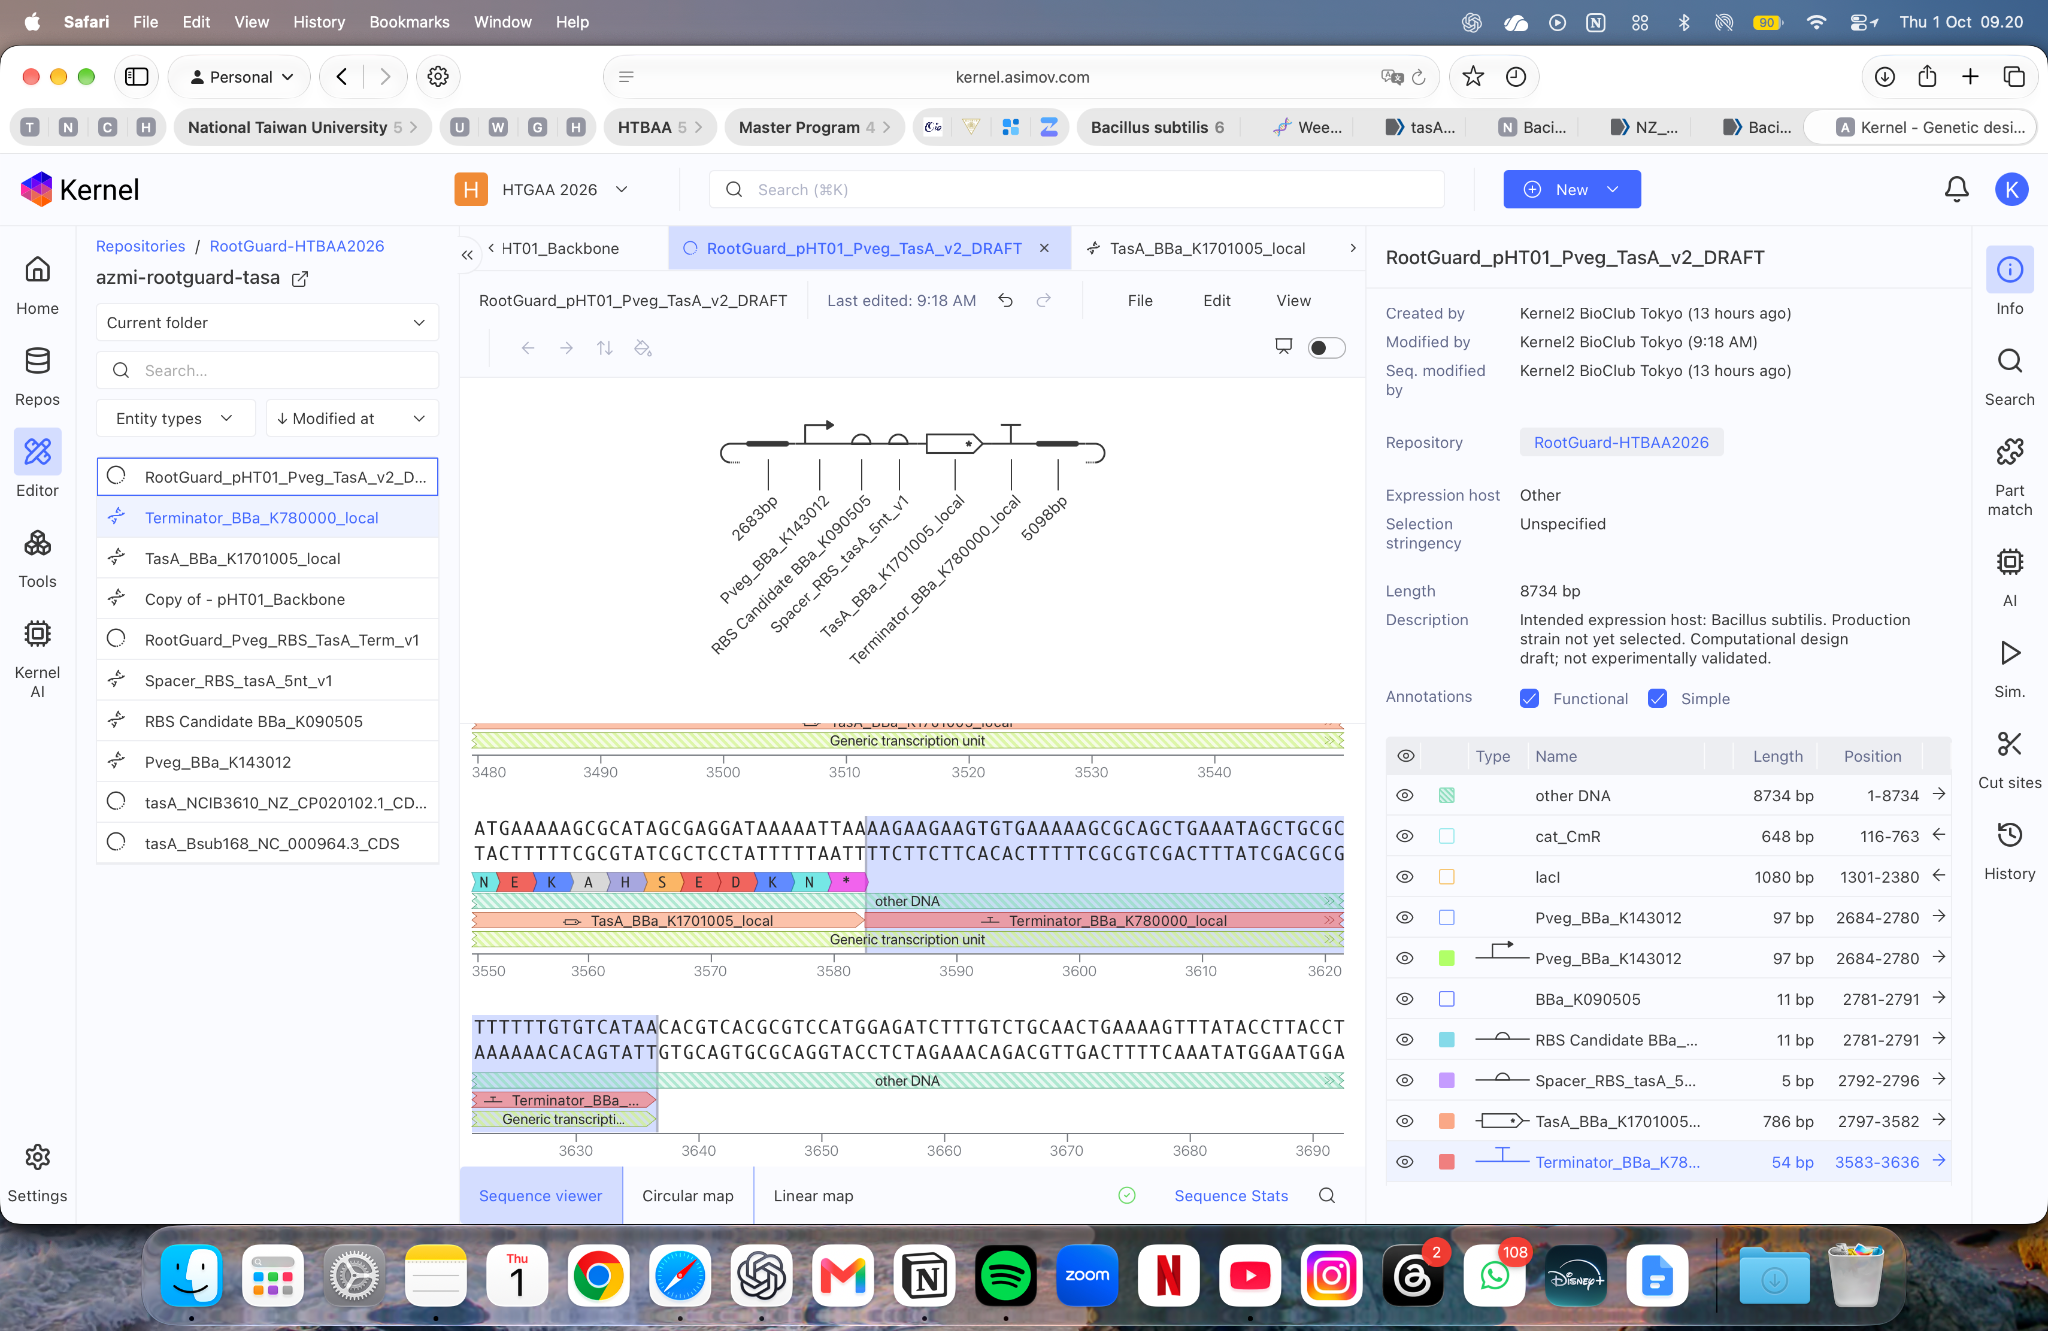
Figure 2. Original editor screenshot, 1 October 09:20 WIB. The functional definitions coexist with simpler feature labels; this does not mean extra copies of the DNA were inserted.
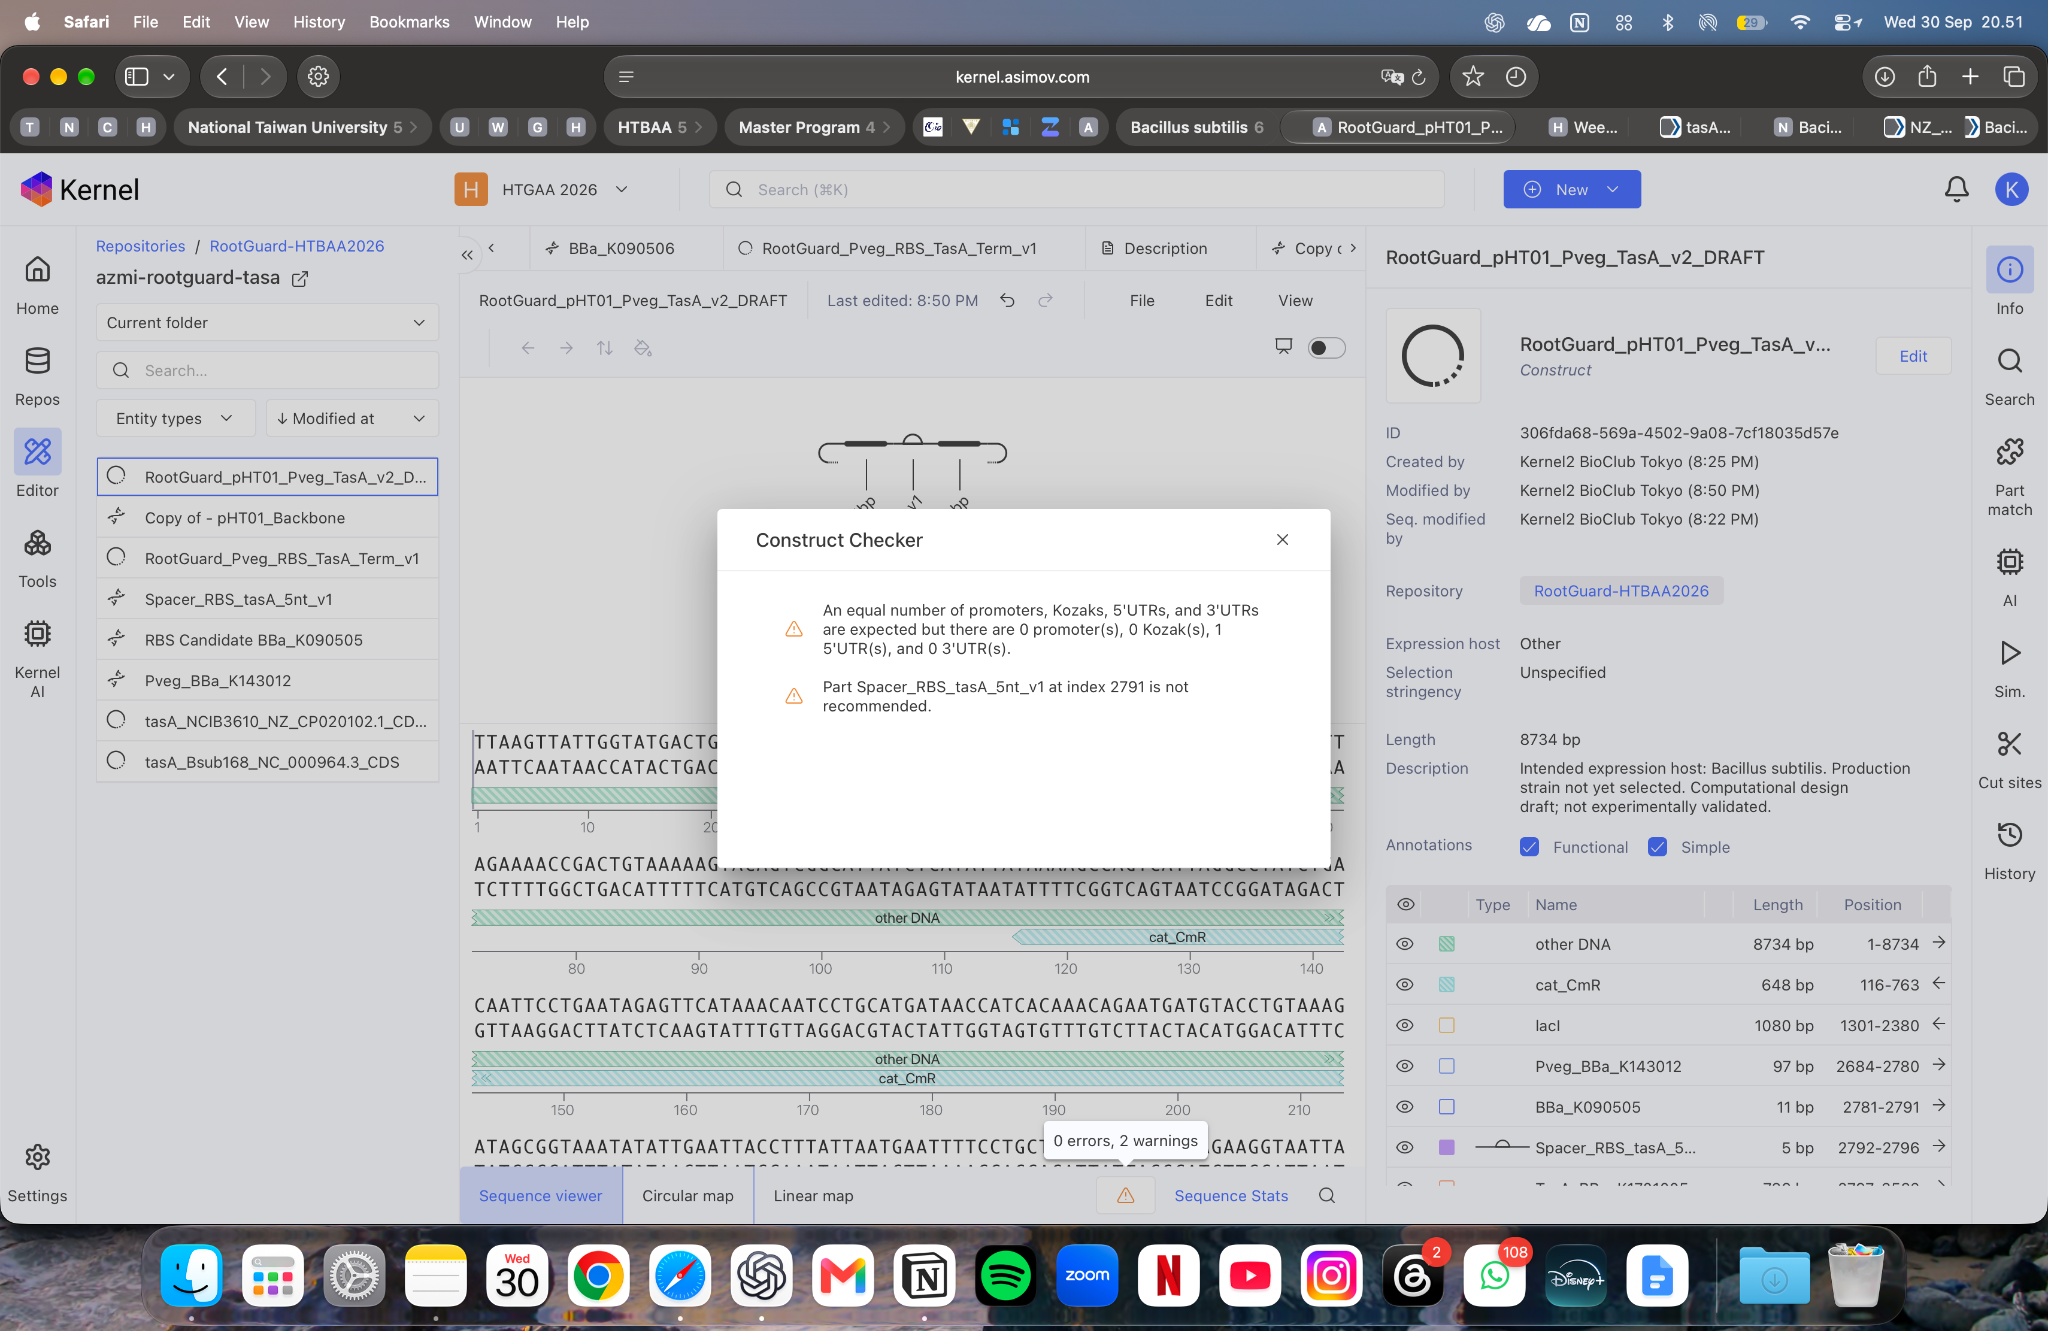
An earlier v2 checker showed 0 errors and 2 warnings, including a promoter-count inconsistency and an unrecommended local spacer. Typed functional parts were subsequently verified in the export. A complete updated v2 warning dialog is not supplied, so I do not claim that all v2 warnings disappeared. The documentation retains the earlier warning screenshot and explains its interpretation.
Part 4 — Optimize and quality-check
Codon optimization: what was attempted, returned and concluded
I inspected Kernel’s Simple v0.3 optimizer. The observed expression-organism menu offered Chinese hamster, human, E. coli and yeast, with no B. subtilis option. Kernel AI suggestions did not establish an available Bacillus setting. I did not substitute another host and call the result Bacillus optimization.
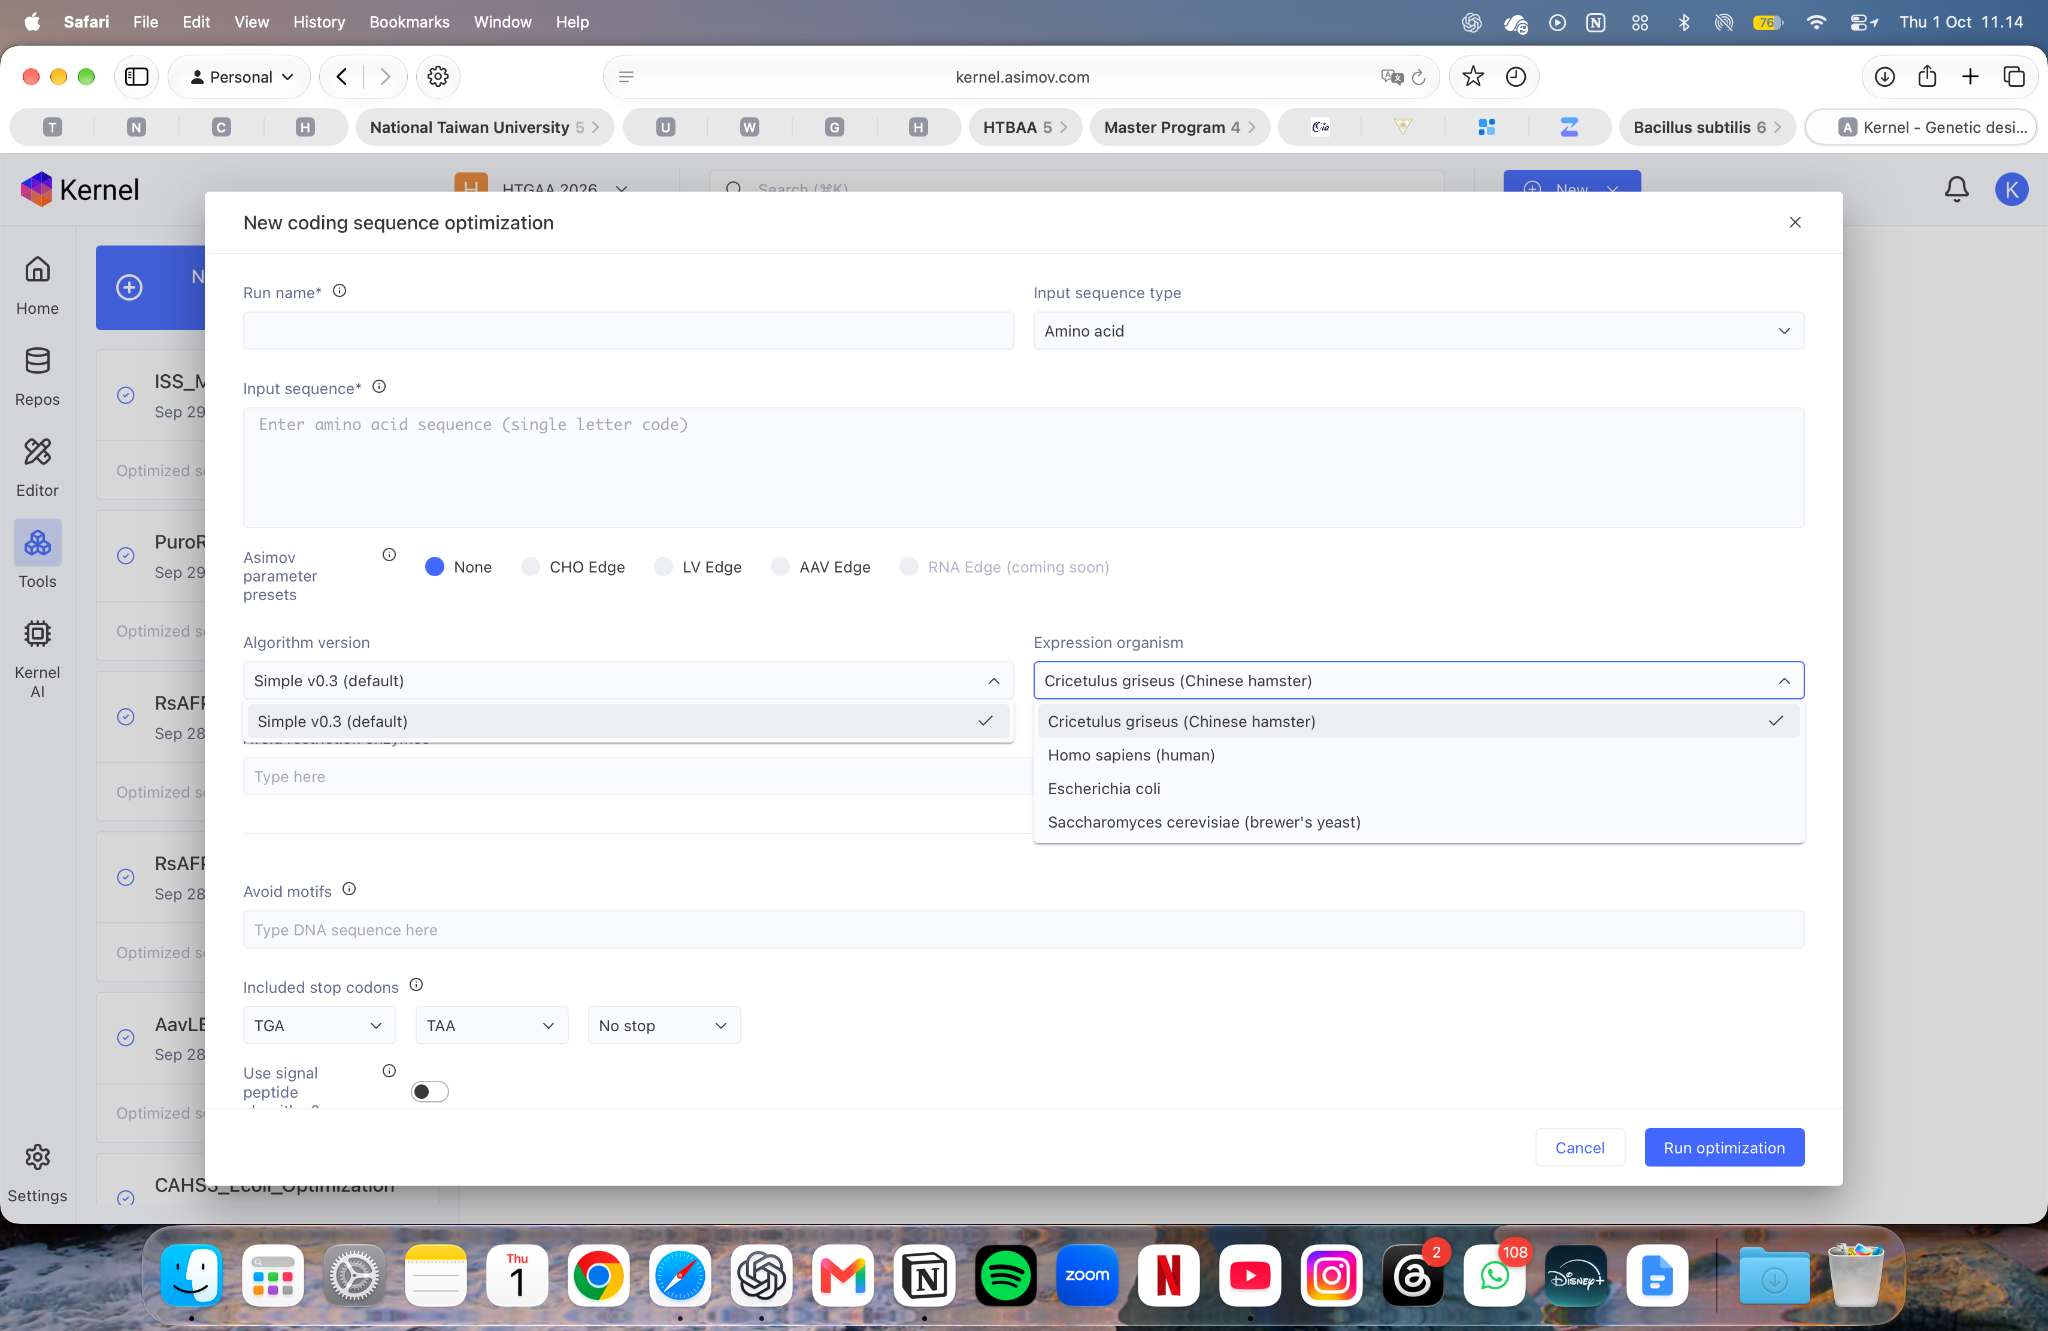
Figure 3. Original screenshot, 1 October 11:14 WIB. This documents the observed form, not a claim about every future Kernel version or workspace.
For a documented external comparison, I used DNA Chisel 3.2.16, CodonOptimize(method=“match_codon_usage”), and python_codon_tables 0.1.18 with b_subtilis_1423. The source is a species-level Kazusa/NCBI-derived table, not a selected production-strain or curated highly expressed-gene reference. Optimization covered the 261 sense codons, with seed 20261001. Constraints retained the protein, ATG start and TAA stop.
Different synonymous codons encode the same amino acid but may affect translation in a host. Matching a codon table offers a testable design hypothesis; it does not predict secretion or guarantee improved expression. DNA Chisel documentation and codon-table provider.
| Metric | Native CDS | External candidate |
|---|---|---|
| Length | 786 bp | 786 bp |
| Translation | 261 aa | Same 261 aa |
| Start / stop | ATG / TAA | ATG / TAA |
| GC | 37.66% | 42.49% |
| Longest homopolymer | 6 bases | 7 bases |
| Codon-profile discrepancy objective | −88.18 | −12.36 |
The candidate contains 52 nucleotide substitutions across 47 synonymous codons. Closer to zero means a closer table-profile match for this objective; the score is not CAI and is not measured expression. No GC target, restriction-site avoidance, mRNA-folding, secretion-efficiency or vendor-acceptance constraint was imposed.
The candidate FASTA, generation QC, change table, script, dependency versions and codon-table snapshot make the comparison inspectable.
The separate Kernel entry RootGuard_TasA_Bsub_DNAChisel_candidate_v1_2026-10-01, ID 61e38ea9-3d0f-4cc4-9b8a-629c57ec7736, is CDS-only, with tasA 1–786 forward. Its Sequence Stats shows 786 bp / 42.49% GC; editor validation shows 0 errors / 0 warnings. Those checks do not prove biological function. Its complete Kernel re-export has not been hash-compared; the supplied candidate GenBank is an external file, not that missing re-export. Native assembled v2 remains unchanged.
Sequence search: identity and nearest visible matches
I submitted complete CDS sequences to Kernel’s global sequence search. The results concern Kernel’s indexed repositories, including public iGEM entries and local constructs; this was not a separate NCBI BLAST run. Exact algorithm parameters and database snapshot were not displayed.
| Query and visible public hit | Identity | Query / subject coordinates | Displayed E value | Bit score |
|---|---|---|---|---|
| Native CDS → BBa_K1701005, 30 September | 100.0% | 1–786 / 1–786 | 0.00e+0 | 1452.6 |
| External candidate → BBa_K1701005, 1 October 12:25 | 93.4% | 1–786 / 1–786 | 0.00e+0 | 1164.5 |
The native query is consistent with the known TasA sequence. For the candidate, several public/native entries tie at 93.4%. 734 / 786 × 100 = 93.3842%, matching the rounded display after 52 substitutions. This is a redesigned DNA sequence relative to the native reference, while local translation confirms the same protein. It is not evidence of globally novel sequence or a new protein function.
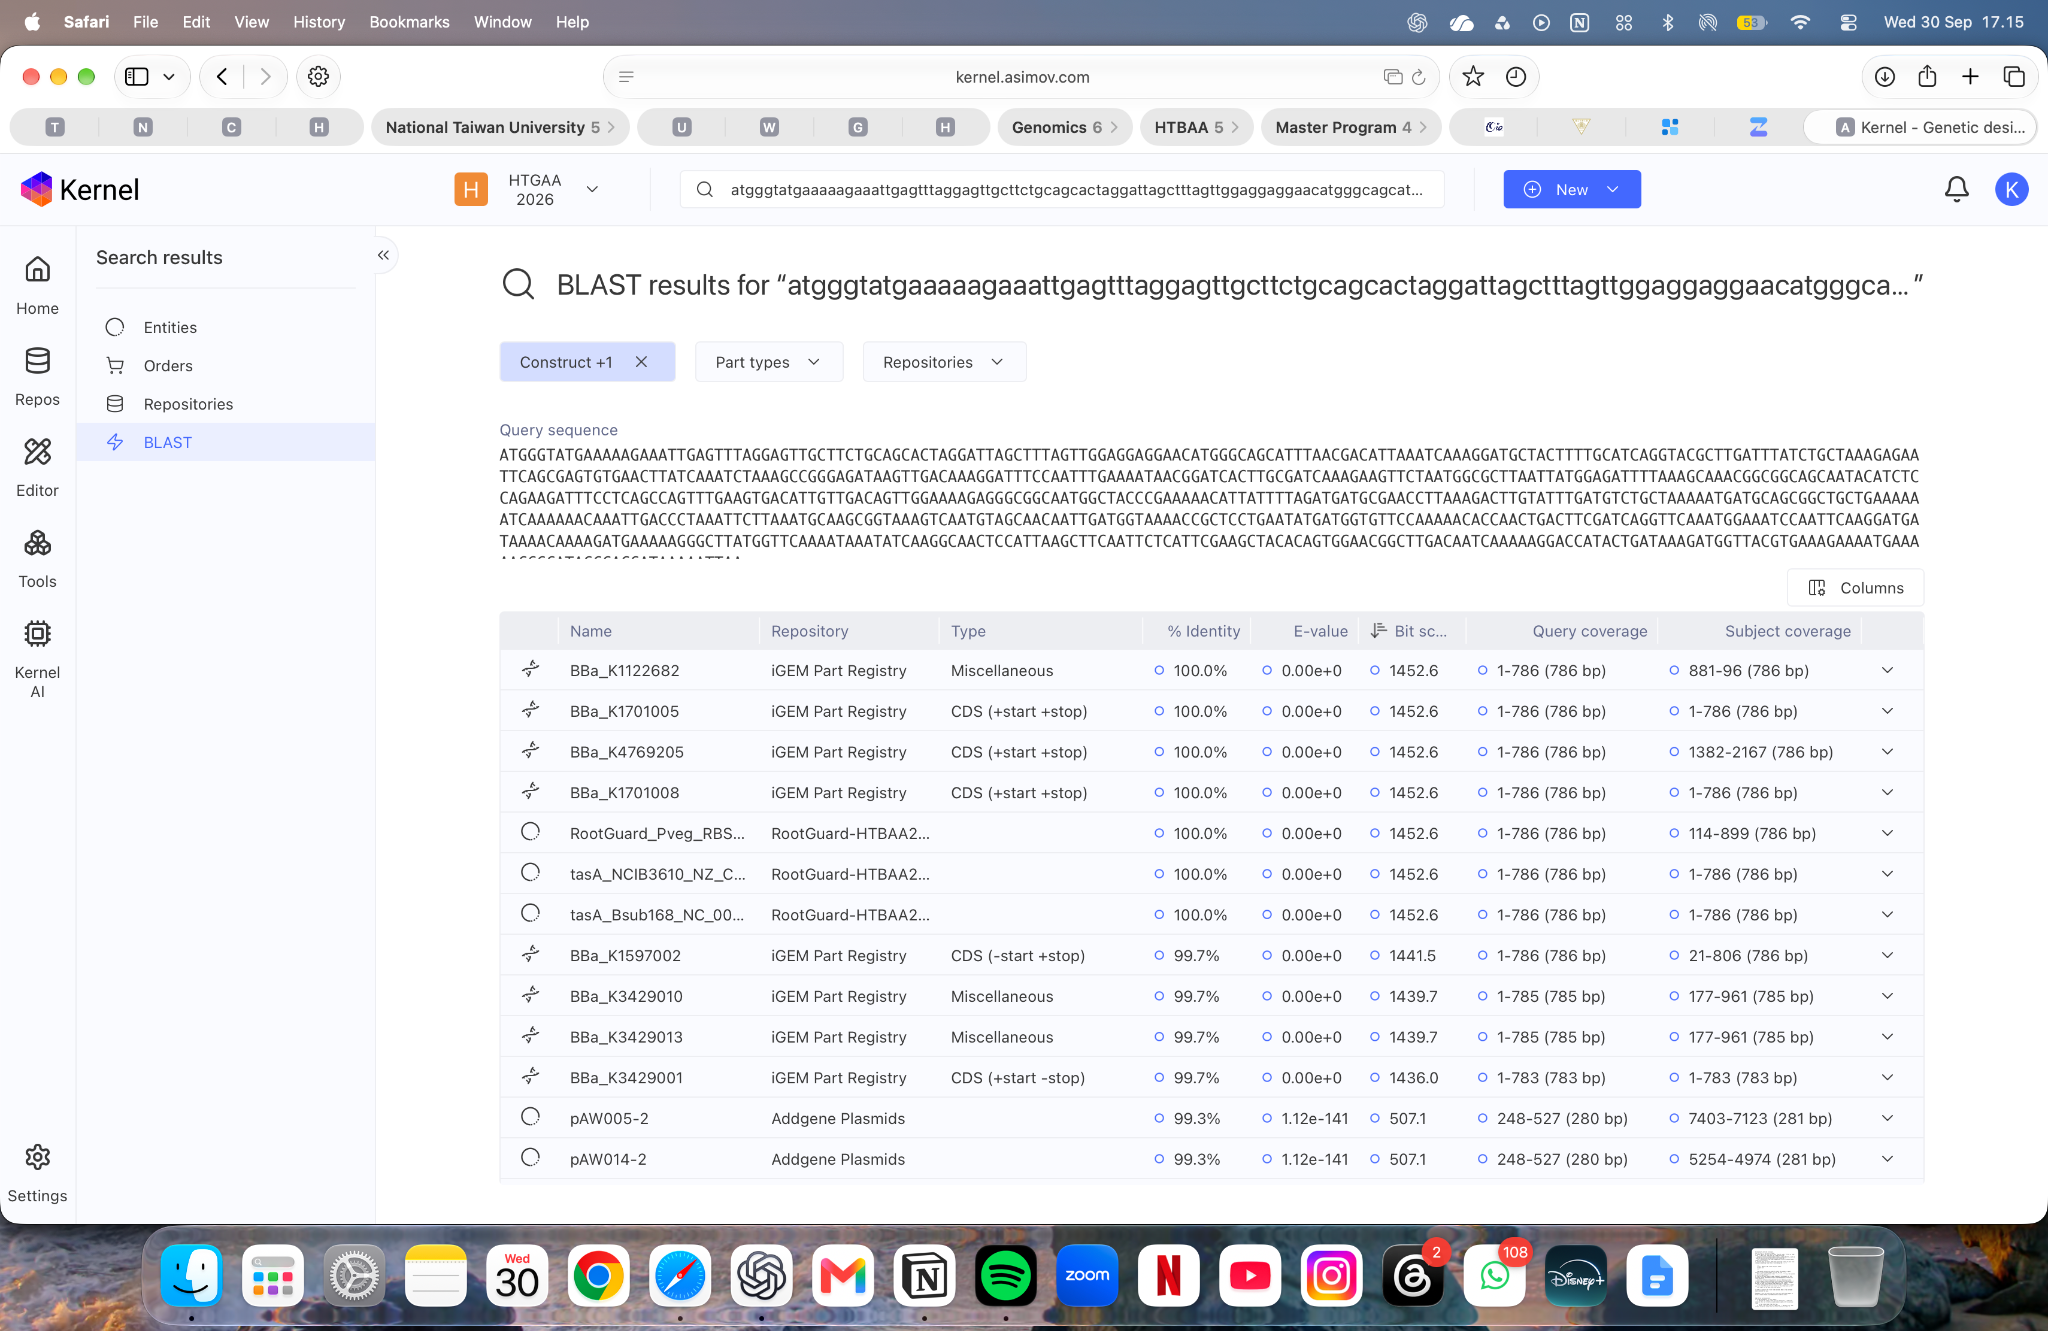
Figure 4. Native search, 30 September 17:15 WIB. BBa_K1701005 is a full-length 100% hit; other entries contain the same matching region.
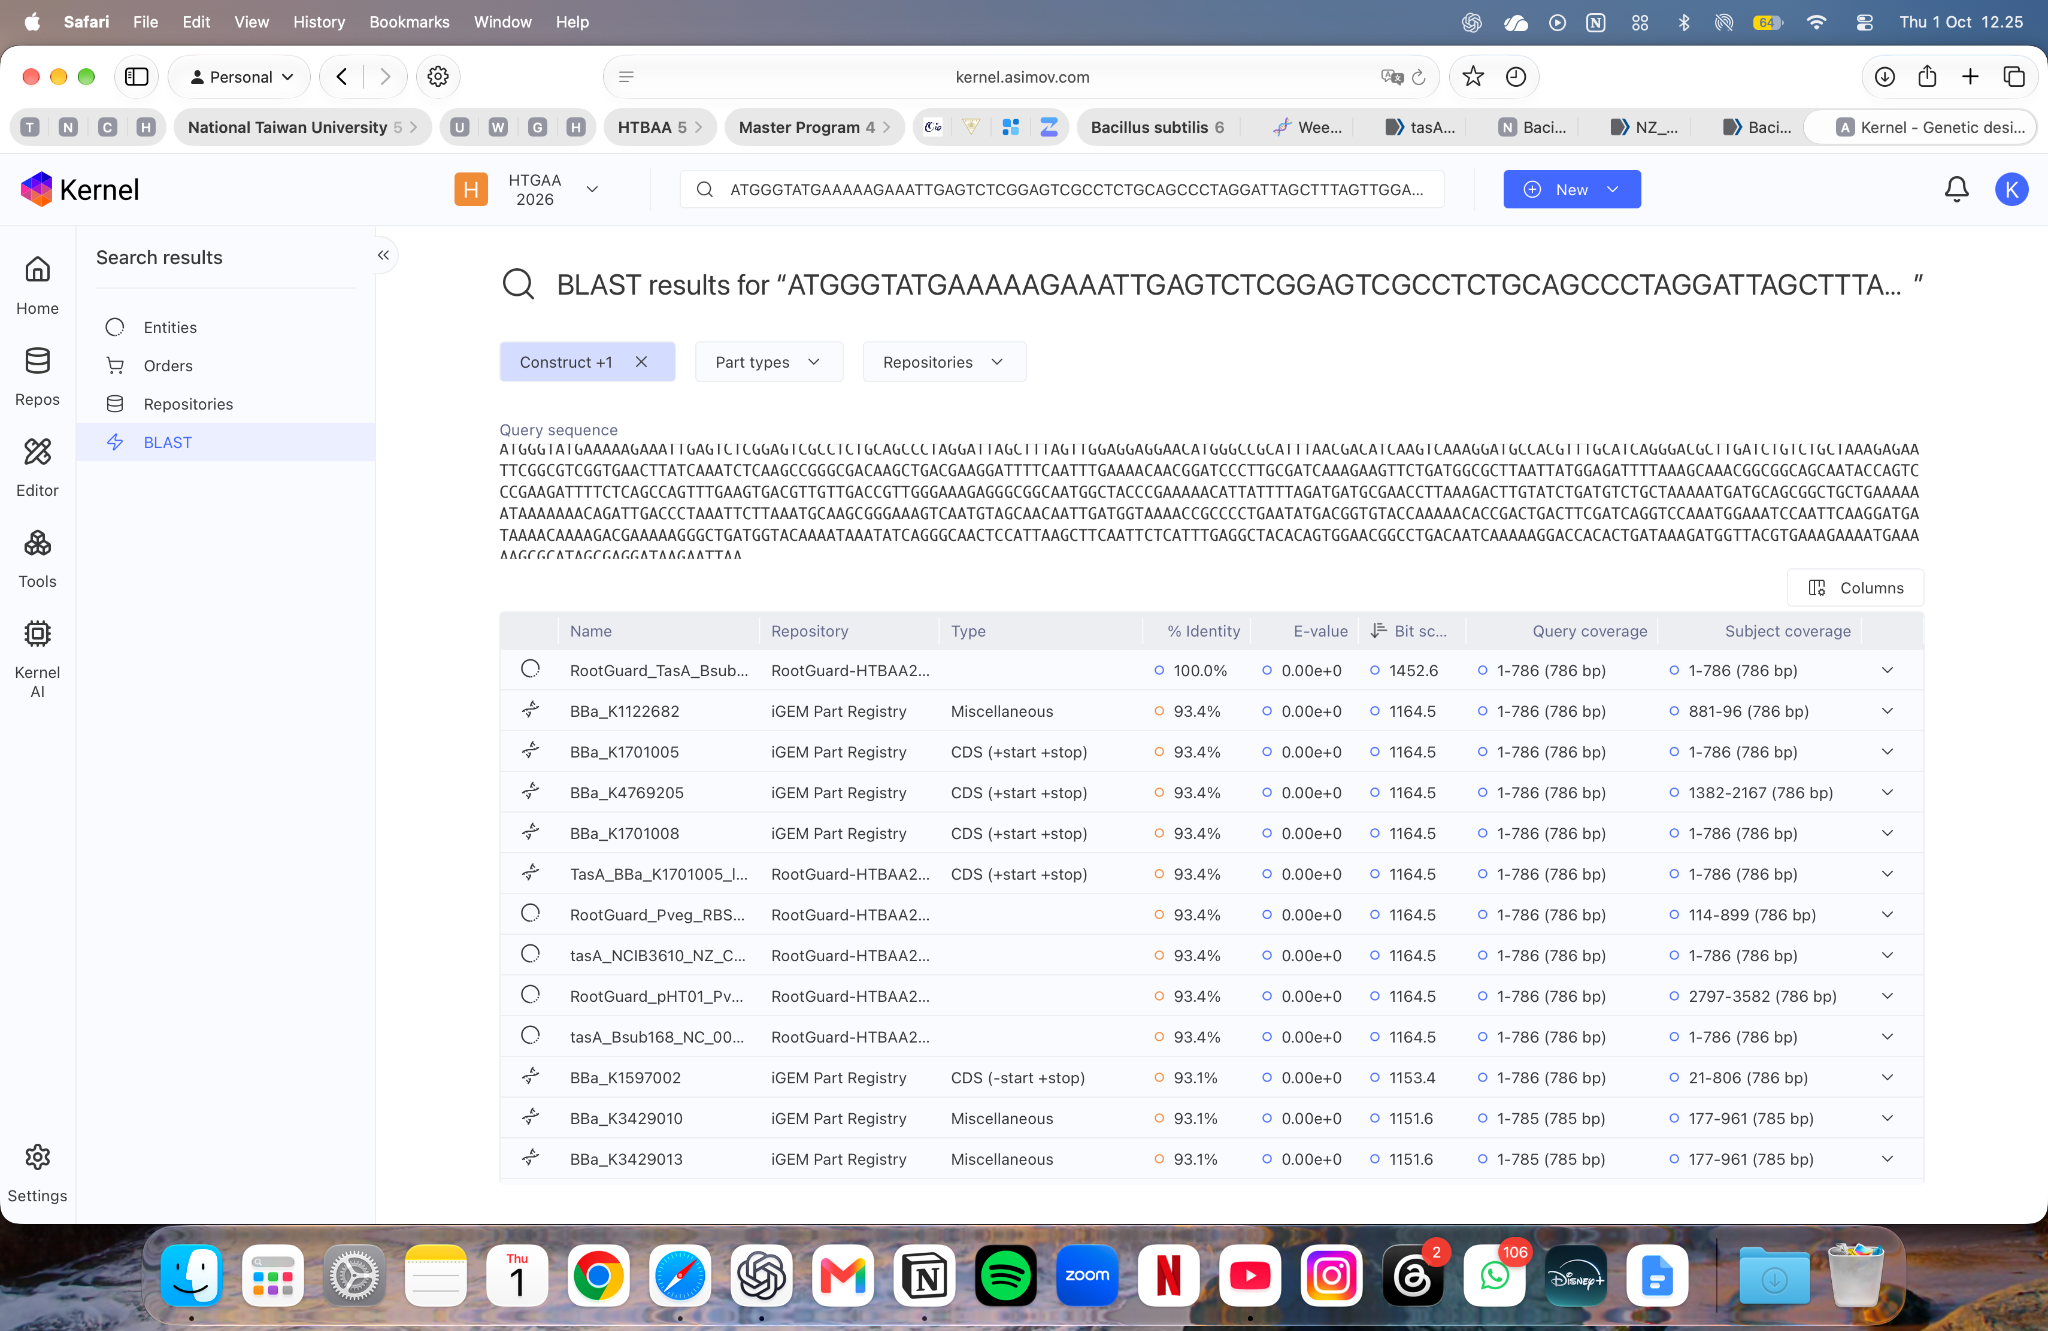
Figure 5. Candidate search, 1 October 12:25 WIB. The local candidate’s 100% self-match is not independent biological evidence. The visible filter is “Construct +1”; the additional entity type is not expanded. Subject coordinates differ between entries, including a reverse-oriented hit.
Biosecurity screening: what it checks and what happened
Kernel’s Biosecurity sequence scanner, powered by SecureDNA, compares nucleotide input against a database of potential biosecurity threats. The observed action button was Scan for Biohazards. The v2 workflow at 09:54 WIB and the candidate workflow at 12:14 WIB on 1 October reported No flagged sequences detected. Earlier v1 screening also reported no flags. Official Kernel documentation.
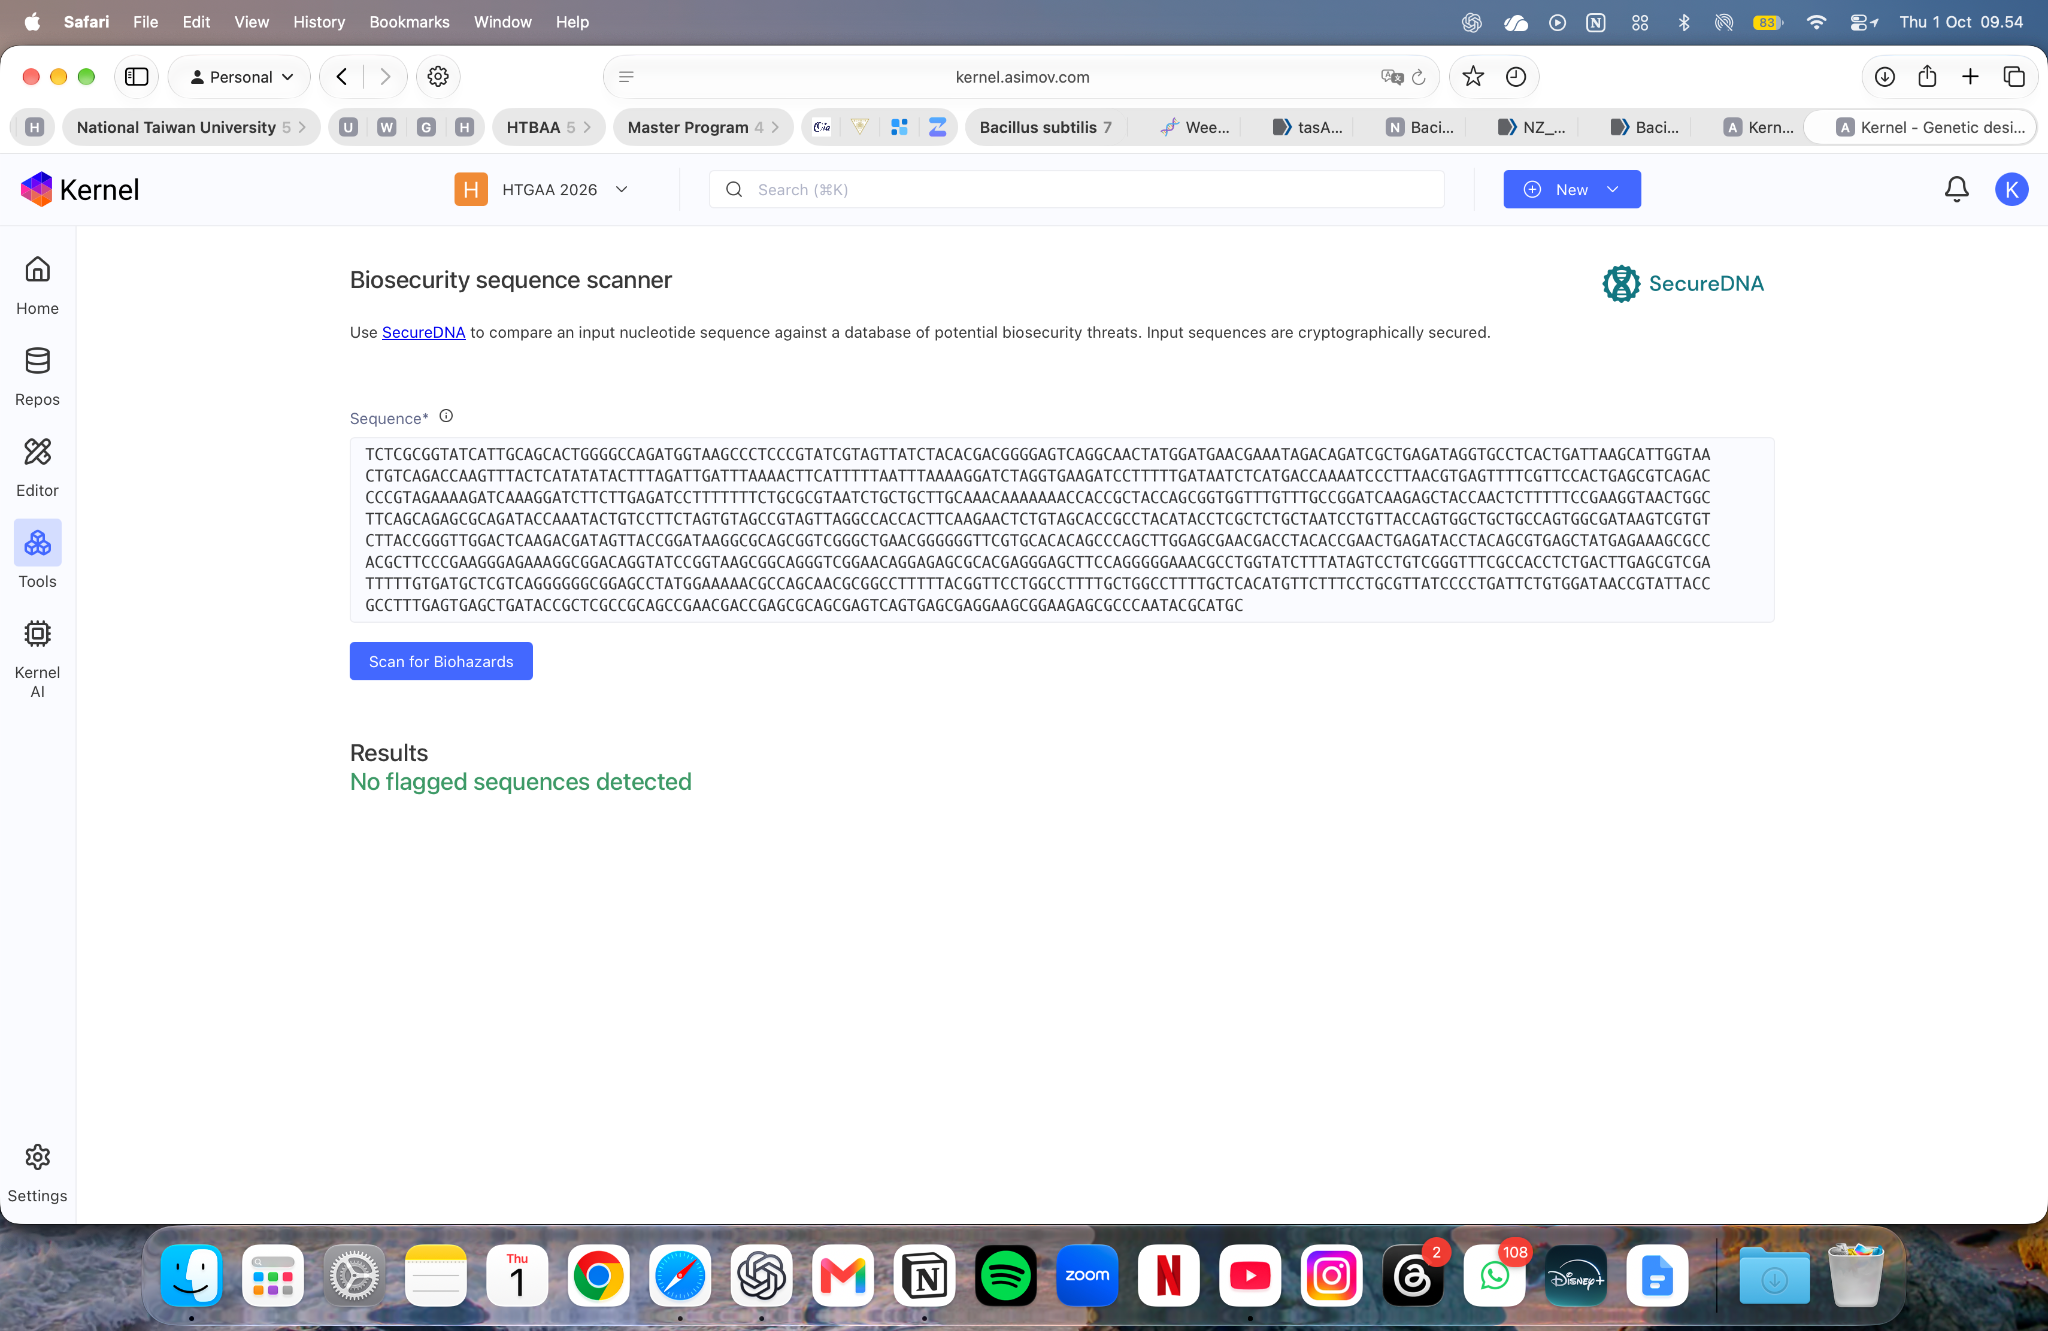
Figure 6. Whole-v2 workflow result, 1 October 09:54 WIB.
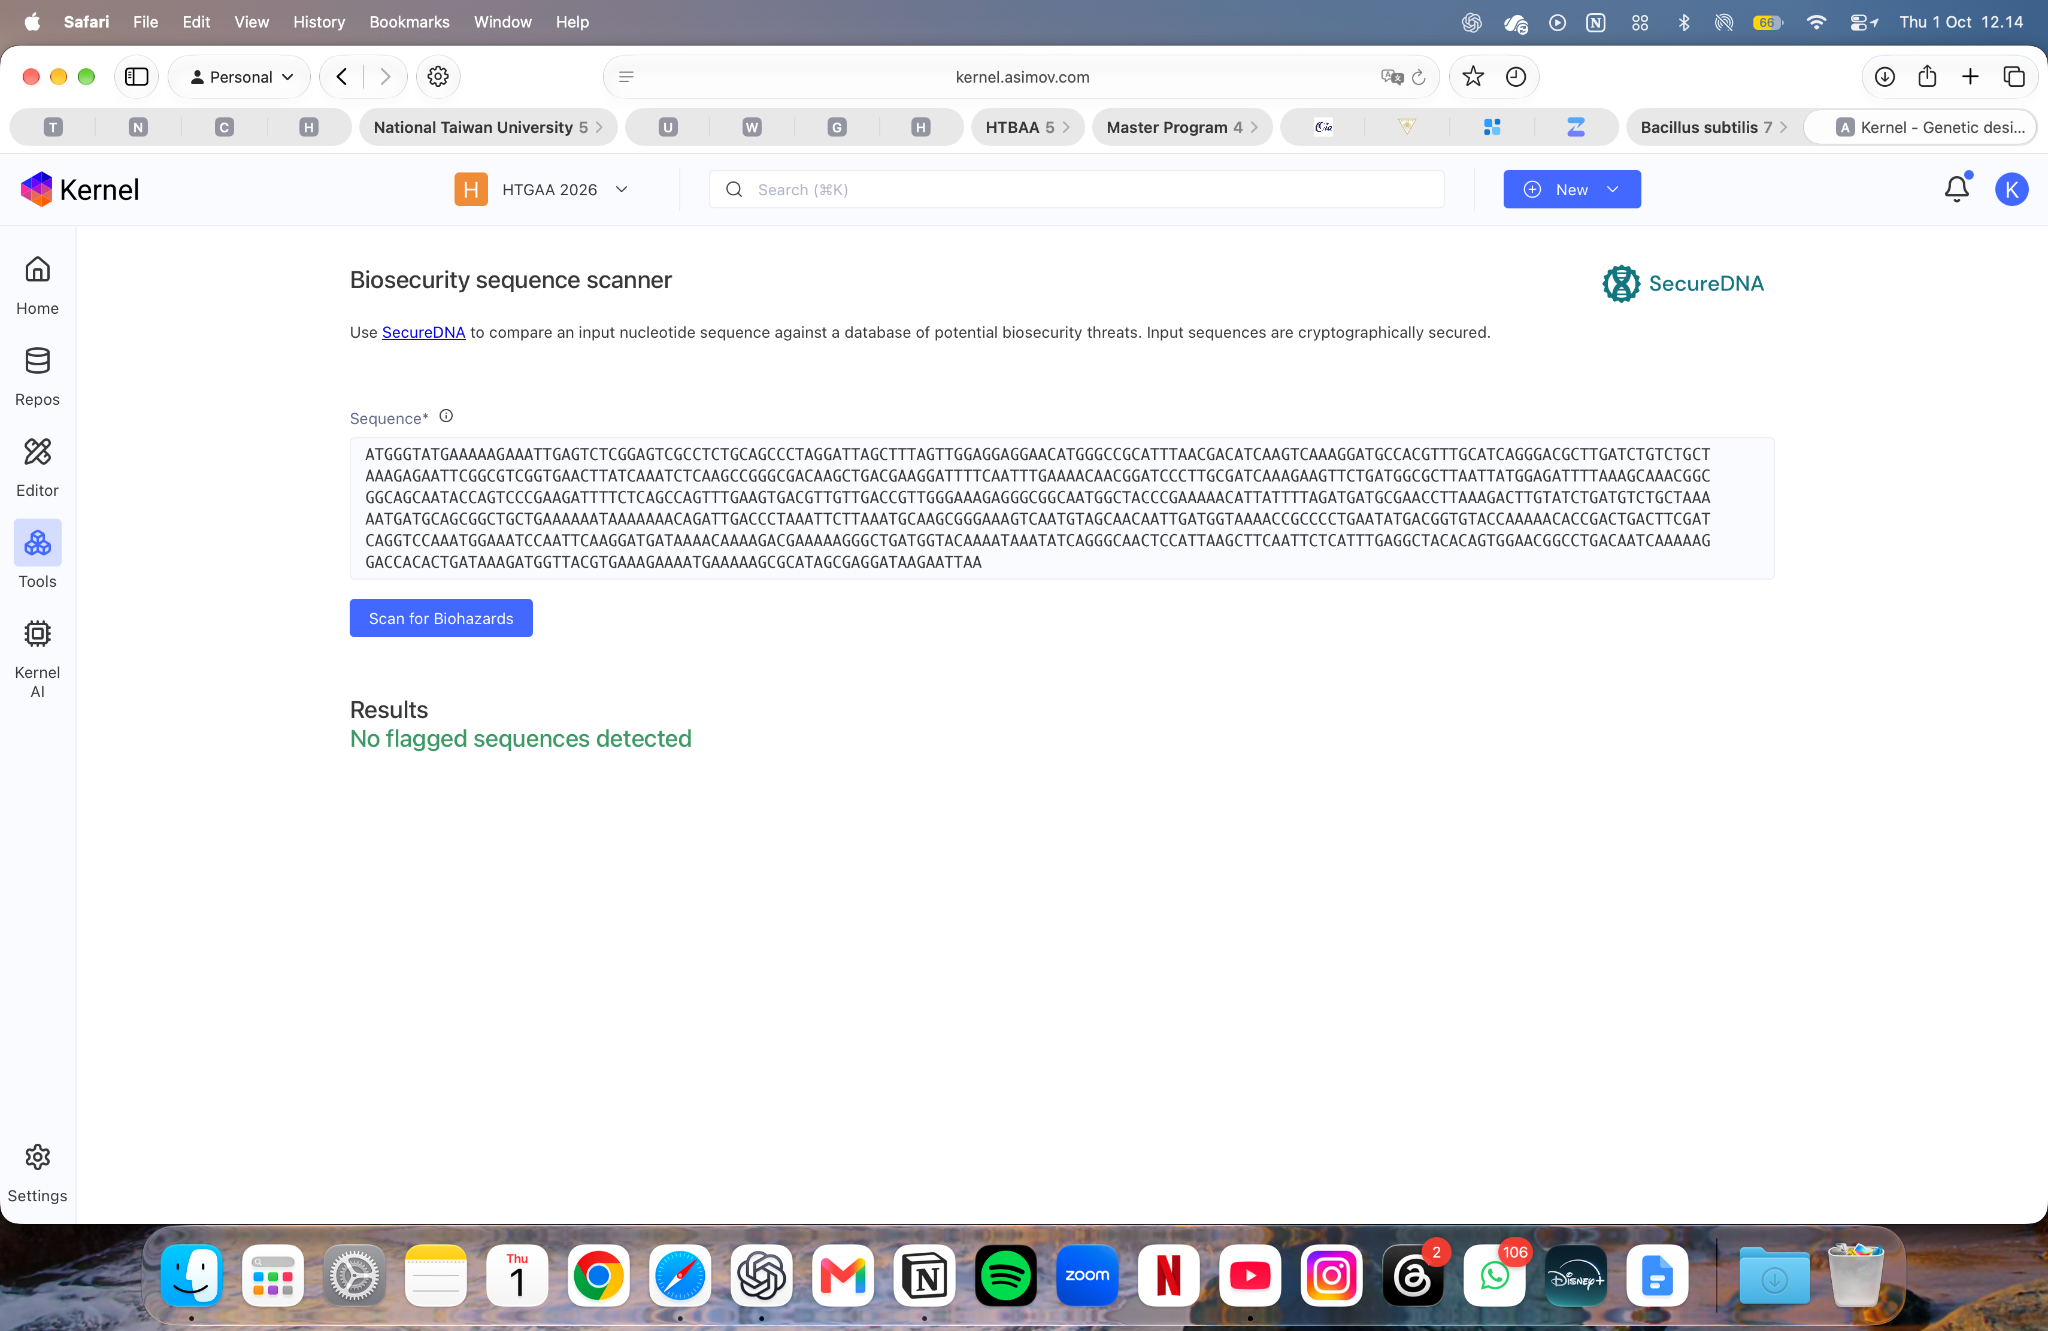
Figure 7. Candidate workflow result, 1 October 12:14 WIB.
The intended inputs were the 8,734-bp v2 and 786-bp candidate, and visible sequence endpoints agree with the source files. The screenshots do not independently establish full input length/hash, database version or a screening certificate. I retain this provenance limitation. No sequence flags in these runs does not establish living-strain safety, successful expression or suitability for environmental release. If a subsequent screen flags a region, I would review that region with the course team and screening provider rather than treat a digital pass as a substitute for review.
Historical QC files are kept unchanged. A generation-time field such as “candidate not imported or screened” describes that earlier snapshot; subsequent import, search and screening are documented here and in the dated re-verification record.
Part 5 — From design to build
How would I build one prototype?
I would start with a sequence-verified synthetic native cassette of 953 bp and an identified, compatible pHT01-derived vector. A fragment-based approach is reasonable for this modest cassette. Gibson assembly is a candidate route after the insertion boundaries and complementary overlaps are reviewed. I have not specified ready-to-order primers, overlaps or assembly scars, and no DNA has been ordered or built.
| Minimum build request | Digital specification available | Still needed before ordering/building |
|---|---|---|
| One native expression insert | 953-bp cassette FASTA, with all five part sequences | Synthesis/fragment review and final junction/overlap design |
| One compatible vector context | Original 7,956-bp reference; retained digital flanks total 7,781 bp | Exact physical vector, Bacillus replication/selection context and insertion-boundary review |
| Final intended assembled DNA | 8,734-bp FASTA and actual Kernel GenBank | Physical assembly followed by insert/junction sequence verification |
This is the minimum specification for review, not a completed commercial order. An entire 8.7-kb synthetic plasmid might be another route, but I have not checked vendor feasibility or cost and do not assume it is necessary for one prototype. A chip-derived oligo pool adds complexity that is not justified for this single initial cassette.
What does synthesis constrain?
Native CDS GC is 37.66%, its longest homopolymer is six bases, and it contains an EcoRI site at positions 150–155. That site matters if EcoRI is selected for restriction assembly; it does not inherently prevent an overlap-based assembly. The candidate’s longest homopolymer increases to seven bases, showing that codon-table matching does not automatically improve every synthesis property. These are CDS observations, not a full-vector vendor acceptance audit.
Before ordering fragments, I would review GC extremes, repeated or difficult regions, unwanted assembly-related sites and junctions. Splitting a difficult region into fragments may alter the build plan, but fragment assembly still needs sequence confirmation. There is no current vendor-specific difficulty report for this design.
Two assigned readings directly support this reasoning:
- Gibson et al. (2009) describes joining overlapping DNA fragments using exonuclease, polymerase and ligase in an isothermal reaction. It supports the proposed overlap-assembly route, without validating my chosen junctions. DOI: 10.1038/nmeth.1318.
- Carr et al. (2004) describes mismatch-protein-based error reduction in synthesized DNA. It supports considering synthesis errors and sequence verification of received DNA; I do not claim to have applied that error-correction method. Its historical error figures are not a current supplier guarantee. DOI: 10.1093/nar/gnh160.
Prototype versus scale
For a larger library of DNA variants, pooled synthesis and selective amplification, as in Kosuri et al. (2010), could become relevant. DOI: 10.1038/nbt.1716. This is distinct from scaling RootGuard production. After a strain and design are qualified, manufacturing focuses on cultivation, carrier formulation, recoverable viable cells and batch consistency; it does not require synthesizing new DNA for every inoculant batch. This keeps HW2 consistent with HW1’s proposed automated screening and later process-control workflow.
Part 6 — Three validation risks and how I would find out
| Biggest unknown | Why it matters | Next measurement or design comparison |
|---|---|---|
| Regulatory parts may give inadequate expression, burden or read-through | Correct DNA order does not establish useful TasA expression | Compare matched promoter/RBS/spacer variants and controls; measure TasA transcript/protein, downstream read-through and growth. Compare native and synonymous CDS under the same regulatory context if the candidate advances |
| TasA may not be processed, exported or assembled into matrix | The production strain is unselected; TasA alone may not supply the needed host context | Check SipW/TapA/matrix context, extracellular TasA and structured matrix with appropriate controls; distinguish total protein from correctly localized/assembled product |
| Matrix may not improve RootGuard cell retention or plant outcomes | Biochar compatibility, cell recovery and spore-mediated survival may confound interpretation | Compare recoverable viable cells per gram, retention/storage, spore fraction and microscopy with matched free-cell, carrier-only and recovery controls; evaluate maize responses separately after strain qualification |
Biochar can interfere with optical or colorimetric measurements, as already considered in HW1. Carrier blanks and recovery controls therefore matter. No matrix improvement, drought tolerance, maize-yield benefit or shelf-life claim follows from the software results.
Verified results versus assumptions
| Verified within the supplied computational evidence | Still uncertain |
|---|---|
| Actual v2 export: 8,734 bp, native CDS, preserved flanks and intended typed cassette annotations | Biological validity of vector replacement boundaries and the eventual strain context |
| Native/candidate local files: 786 bp each, identical 261-aa protein, 52 substitutions and 47 synonymous codons | Whether the synonymous candidate improves expression; complete candidate Kernel re-export identity |
| Recorded search identity/coverage and observed SecureDNA no-flag messages | Screening input’s independently verified full hash/count; live-organism suitability |
| Actual PNG export and dated editor screenshots | Complete latest v2 warning state; acceptance of the external optimization alternative |
The handout asks for a defensible design, not a perfect lab-ready plasmid. The result is a documented computational prototype with explicit unresolved requirements, not a validated RootGuard product.
Questions for Homework Review
- Does the visible HTGAA 2026 workspace satisfy the requested HTBAA 2026 workspace?
- Can the documented external Bacillus codon comparison satisfy Part 4, or which available Kernel workflow supports this host?
- Is TasA alone an appropriate HW2 scope, and which strain-context, replication and replacement-boundary checks should precede construction?
Documentation, files and evidence
- Process documentation: steps, decisions, errors and screenshots.
- Requirement-by-requirement coverage checklist.
- Actual Kernel GenBank, complete v2 DNA FASTA, typed-part sequences and annotation TSV.
- Native CDS, protein and external candidate CDS.
- Dated re-verification, standalone file-verification script, evidence manifest and file checksums.
- Complete dated Notion journal.
Sources and AI disclosure
Requirements follow the supplied HTBAA Homework #2: DNA Design handout and HTBAA Fall 2026 Syllabus. Project continuity follows my published HW1 and its supplied PDF. Sequence, part, vector and software links appear beside the relevant claims. Build reasoning uses the assigned Gibson (2009), Carr (2004) and Kosuri (2010) readings; I do not imply that every assigned reading was needed to select this simple cassette.
I used ChatGPT by OpenAI to interpret requirements and screenshots, review provenance/direction/frame, prepare the provisional pHT01 draft, run the external DNA Chisel comparison, recover/check files and revise this report. English translations of prompts originally submitted in Indonesian include:
- “How can I obtain it from an official source?”
- “Is this what you meant by exporting the map? Now that I have reached this stage, what should I do next to complete Homework 2 and publish it?”
- “Can you evaluate and analyze the entire narrative?”
- “Please prepare a fully revised write-up, including documentation and results, that answers all of the questions in Homework 2.”
I also consulted Kernel AI about Bacillus optimizer support. The exact English prompt asks for available controls, an explicit limitation if unsupported, and no substitution of another host or modification of native v2. AI suggestions were checked against available controls and sequence evidence. Proposed biological behavior remains an assumption wherever marked.