Week 2 HW: DNA Design
DNA Design & Expression Construct
Part 0: Open-Source Software Setup & Workspace
Note on Software: This DNA design was constructed, optimized and checked using Asimov Kernel (construct editor, coding-sequence optimization tool and construct checker). Protein and part identifiers come from public databases (UniProt, iGEM Registry) and are listed as accession numbers in the References section.
- Project: Desiccation-associated proteins in E. coli: CAHS3 and AavLEA1
- Design tool: Asimov Kernel (construct maps, codon optimization, construct checker)
- Host: E. coli BL21(DE3), T7 expression system
- Constructs: two independent expression cassettes, T7 promoter → BBa_B0034 RBS → CDS → BBa_B0015 terminator
- Construct 1: CAHS3 (UniProt J7M3T1), E. coli-optimized CDS
- Construct 2: AavLEA1 (UniProt Q95V77), E. coli-optimized CDS
- Status: in-silico design only. Nothing was synthesized, transformed or expressed for this homework.
Project summary
Some organisms survive almost complete water loss. Two protein families implicated in this are the tardigrade CAHS proteins and the nematode group 3 LEA proteins. My goal this week was to design DNA that could later be used to test whether two such proteins can be expressed in E. coli: CAHS3 from the tardigrade Ramazzottius varieornatus and AavLEA1 from the nematode Aphelenchus avenae.
I kept them as two separate constructs, not a fusion, so each protein can be tested on its own, and later in combination. Trehalose, a well-known desiccation protectant, is treated as an external variable and is not encoded in the DNA.
This page is a design study. Whether these proteins protect E. coli is a hypothesis for future testing, not a result of this homework.
Part 3: DNA Design Challenge
3.1 Choose your protein
Protein 1: CAHS3
| Name | CAHS3 (cytosolic-abundant heat-soluble protein 3) |
| Organism | Ramazzottius varieornatus (tardigrade) |
| UniProt | J7M3T1 |
| Length | 303 aa |
CAHS proteins are tardigrade-specific, intrinsically disordered proteins that are abundant in the cytosol and heat-soluble. CAHS3 is one of the most highly expressed CAHS paralogs in R. varieornatus. Work on tardigrade-specific disordered proteins reported that they can contribute to desiccation tolerance, including when expressed in heterologous systems (Boothby et al. 2017). I chose it because it is a natural candidate protectant that is small enough to express easily in bacteria.
Protein 2: AavLEA1
| Name | AavLEA1 (late embryogenesis abundant protein 1, group 3 LEA) |
| Organism | Aphelenchus avenae (nematode; UniProt lists Aphelenchoides avenae) |
| UniProt | Q95V77 |
| Length | 143 aa |
The A. avenae LEA gene is induced during dehydration (Browne et al. 2004), and the protein reduces aggregation of other proteins during drying and rehydration in vitro (Chakrabortee et al. 2007). I chose it as a second candidate with a different origin and, plausibly, a different mechanism, so the two can be compared instead of assuming all desiccation proteins act alike.
3.2 Reverse translate: protein to DNA
Each protein sequence was converted to a coding sequence (CDS). The reference CDS lengths, including a single stop codon, were:
| Protein | Amino acids | Reference CDS |
|---|---|---|
| CAHS3 | 303 | 912 bp |
| AavLEA1 | 143 | 432 bp |
(303 × 3 + 3 = 912 and 143 × 3 + 3 = 432, consistent with one stop codon each.)
3.3 Codon optimization
Why optimize? The genetic code is degenerate: most amino acids are encoded by several synonymous codons, and organisms use them at different frequencies, matched to their tRNA pools. A gene from a tardigrade or a nematode uses codons that may be rare in E. coli, which can slow or stall translation. Re-encoding the same protein with codons E. coli prefers can improve expression (Gustafsson et al. 2004). It is not a guarantee, because synonymous changes also alter mRNA structure and translation kinetics and can affect folding (Mauro 2018), so I treat optimization as a design choice that still needs experimental testing.
Organism chosen: E. coli, specifically BL21(DE3), because it is the standard T7 expression host and the one most accessible for a first test.
Settings used in the Kernel Coding Sequence Optimization tool (both proteins):
| Parameter | Setting |
|---|---|
| Input | Protein amino-acid sequence |
| Target organism | E. coli |
| Algorithm | SIMPLE_0_3 |
| Stop codons | TGA and TAA |
| Signal peptide | No |
| CpG avoidance | No |
| Restriction-site / motif avoidance | None specified |
The original CDSs were kept unchanged and the optimized versions saved separately. Each optimized CDS ends with TGATAA (double stop), giving about 915 bp (CAHS3) and 435 bp (AavLEA1).
The design journey, including what did not work
My first constructs used the original CDSs with the same parts. The Kernel construct checker returned 0 errors but 7 warnings for both:
- The CDS did not end in the expected double stop.
- The checker expected equal numbers of promoters, Kozaks and UTRs.
- No poly-A sequence was present.
- T7 promoter flagged “not recommended”.
- BBa_B0034 flagged “not recommended”.
- The CDS flagged “not recommended”.
- BBa_B0015 flagged “not recommended”.
I interpreted these one by one instead of silencing them all. Warnings 2 and 3 (Kozak/UTR/poly-A) are eukaryotic conventions that do not apply to a bacterial T7 → RBS → terminator cassette, so I did not add eukaryotic elements just to satisfy the checker. The stop-codon warning was a real sequence-level issue that optimization with TGA + TAA fixed. After rebuilding both constructs with the optimized CDSs, the checker reported 0 errors and 0 warnings for both.
Final constructs
Construct 1: CAHS3
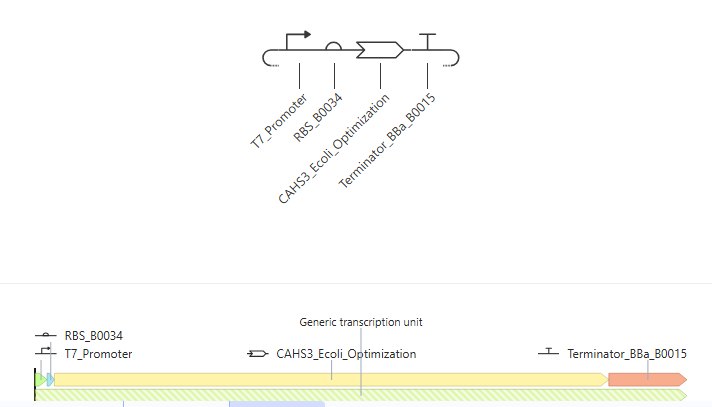
SBOL-style schematic and linear map: T7 promoter, RBS_B0034, CAHS3_Ecoli_Optimization, Terminator_BBa_B0015.
Construct 2: AavLEA1
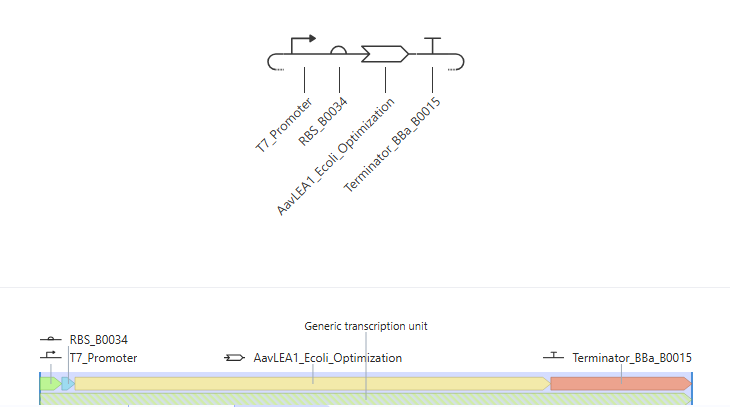
SBOL-style schematic and linear map: T7 promoter, RBS_B0034, AavLEA1_Ecoli_Optimization, Terminator_BBa_B0015.
| Part | Choice | Role |
|---|---|---|
| Promoter | T7 promoter | Transcription by T7 RNA polymerase in BL21(DE3) |
| RBS | BBa_B0034 | Bacterial translation initiation |
| CDS | CAHS3 or AavLEA1 (E. coli-optimized) | Candidate protective protein |
| Terminator | BBa_B0015 | Bacterial transcription termination |
| Construct | Errors | Warnings |
|---|---|---|
| CAHS3 (optimized) | 0 | 0 |
| AavLEA1 (optimized) | 0 | 0 |
A clean checker result means the constructs pass Kernel’s computational checks. It does not show that the proteins will express, fold, stay soluble, or protect cells.
Why two constructs instead of a fusion
A CAHS3–AavLEA1 fusion would raise extra questions about whether each partner keeps its behavior, and it would make it impossible to attribute an effect to one protein. Separate cassettes let me test each protein alone, and later co-express them, without redesigning the DNA. The simplicity is deliberate.
Why trehalose is not in the DNA
Trehalose is a small molecule protectant, and I did not add a biosynthesis pathway (e.g. OtsA/OtsB). Keeping it as an external condition keeps the genetic variable (which protein) separate from the formulation variable (trehalose or not). A possible future experimental layout (not performed):
| Condition | CAHS3 | AavLEA1 | Exogenous trehalose |
|---|---|---|---|
| Control | − | − | ± |
| CAHS3 | + | − | ± |
| AavLEA1 | − | + | ± |
| Both | + | + | ± |
3.4 You have a sequence! Now what?
Cell-dependent production. The cassette would be placed on a plasmid and transformed into E. coli BL21(DE3), which carries the gene for T7 RNA polymerase under inducible control. Inducing the host makes T7 polymerase, which recognizes the T7 promoter and transcribes the cassette into mRNA; transcription stops at BBa_B0015. A ribosome binds the BBa_B0034 RBS, finds the start codon, and translates codon by codon (each 3-nt codon specifies one amino acid, read by tRNAs) until it reaches the stop codon, releasing CAHS3 or AavLEA1.
Cell-free production. The same cassette, supplied as a linear gene fragment or plasmid, could be added to a cell-free expression system that contains T7 RNA polymerase, ribosomes, tRNAs and energy sources, avoiding transformation and growth.
Caveats. T7 expression can be leaky and impose a metabolic burden, so induction conditions would need optimization. BBa_B0015 is a general bacterial terminator, not a T7-specific one, so transcriptional read-through is possible. No purification tag was included in these designs, which would make purification harder without adding one later.
3.5 [Optional] How does it work in nature?
A single eukaryotic gene can code for several proteins at the transcriptional/RNA level mainly through alternative splicing (different exon combinations from one pre-mRNA), and also through alternative promoters or transcription start sites. My constructs are bacterial and single-gene, so this does not apply directly. I did not include a DNA/RNA/protein alignment here.
Part 4: Prepare a Twist DNA Synthesis Order
The expression cassettes are designed and annotated (see the maps above). The Twist ordering portion has not been completed at the time of writing: no vector has been selected and no order or quote has been made. When I do it, I plan to import the two annotated inserts as clonal genes and choose a Twist cloning vector with a resistance marker permitted at MIT/Harvard (ampicillin, chloramphenicol or kanamycin).
Part 5: DNA Read / Write / Edit
5.1 DNA Read
(i) What would I sequence and why? The final plasmids carrying the CAHS3 and AavLEA1 cassettes, to confirm that the physical DNA matches the design. The regions that matter most are the promoter–RBS junction, the RBS–CDS junction, the full CDS with its stop codons, and the CDS–terminator junction. A single point error in a CDS could change the protein.
(ii) Technology. I would use Sanger sequencing (first generation) with primers flanking the cassette, and consider Oxford Nanopore whole-plasmid sequencing (third generation) if I wanted the entire plasmid confirmed.
- Generation: Sanger is first-generation (chain termination, one read per reaction). Nanopore is third-generation (single-molecule, long reads).
- Input and preparation: purified plasmid DNA plus a sequencing primer. For Sanger, a cycle-sequencing reaction uses the template, primer, polymerase, dNTPs and fluorescently labelled ddNTPs. For nanopore, the plasmid is linearized, and sequencing adapters are ligated.
- Essential steps and base calling: in Sanger, chain-terminating ddNTPs produce fragments ending at every position; capillary electrophoresis separates them by size, and a detector reads each terminal fluorescent label in order, so the color sequence gives the base sequence. In nanopore sequencing, DNA passes through a protein pore, changing ionic current in a base-dependent way; a basecaller converts the current signal into bases.
- Output: Sanger yields a chromatogram and a text sequence read (~800–1000 bases of good quality). Nanopore yields FASTQ reads, which I would align against the designed reference.
5.2 DNA Write
(i) What would I synthesize and why? The two optimized expression cassettes: T7 promoter → BBa_B0034 → CAHS3 (optimized) → BBa_B0015 and the same with AavLEA1. Optimized CDSs are designed sequences that do not exist as natural DNA, so they must be synthesized before the hypothesis can be tested.
(ii) Technology. Commercial gene synthesis (e.g. Twist Bioscience), ordering the cassettes as clonal genes in a cloning vector.
- Essential steps: short oligonucleotides are chemically synthesized (phosphoramidite chemistry, base by base), then assembled into full-length genes by enzymatic assembly, cloned into a vector, and sequence-verified.
- Limitations: difficulty rises with length, high GC content and repeats; synthesis has a small error rate that requires verification; turnaround takes days to weeks; and cost scales with length. Successful synthesis says nothing about whether the protein will express well.
5.3 DNA Edit
(i) What would I edit and why? If the proteins show promise, I would insert a cassette into a defined E. coli genomic site instead of keeping it on a plasmid, for stable inheritance and defined copy number. Plasmids are easier for early testing, so I would start with plasmids.
(ii) Technology. CRISPR-Cas9 combined with recombineering (λ-Red-mediated homologous recombination) in E. coli.
- How it works: Cas9, guided by a gRNA, cuts the chosen genomic target next to a PAM site; a repair template carrying the cassette flanked by homology arms is used by λ-Red recombination to repair the break, so cells that integrate the cassette survive the cut.
- Preparation and inputs: choose a target site and design the gRNA (with a PAM), design the repair template (cassette plus ~50 bp or longer homology arms), and supply Cas9, the gRNA, the repair template, and competent cells expressing λ-Red; afterwards screen colonies by PCR and confirm by sequencing.
- Limitations: editing efficiency varies by site; off-target cutting is possible; long inserts recombine less efficiently; a single-copy insertion gives lower expression than a multicopy plasmid; and each edit needs verification.
Limitations and what was actually done
Completed: protein selection; two T7 expression cassettes with BBa_B0034 and BBa_B0015; E. coli codon optimization with double stop; identification and interpretation of checker warnings; final constructs with 0 errors and 0 warnings in Kernel.
Not performed: Twist order, DNA synthesis, transformation, expression, purification, desiccation or trehalose experiments, or genome integration.
Unknowns: whether either protein expresses and stays soluble in E. coli; whether codon optimization helps or hurts here; whether either protein provides measurable protection; and how trehalose interacts with them.
AI usage
I used AI assistants (ChatGPT and Claude) to help learn the Kernel workflow, interpret checker warnings, organize this write-up and cross-check my reasoning and citations. Design decisions, settings and Kernel results documented here come from my own work in the tool, and the cited papers were used for the scientific claims.
References
- UniProt J7M3T1 (CAHS3, Ramazzottius varieornatus)
- UniProt Q95V77 (AavLEA1, Aphelenchus avenae)
- iGEM Registry: BBa_B0034 (RBS), BBa_B0015 (terminator)
- E. coli BL21(DE3): NEB C2527
- Boothby TC et al. (2017) Mol Cell 65:975. doi:10.1016/j.molcel.2017.02.018
- Browne JA et al. (2004) Eukaryot Cell 3(4):966–975
- Chakrabortee S et al. (2007) PNAS 104(46):18073. doi:10.1073/pnas.0706964104
- Gustafsson C, Govindarajan S, Minshull J (2004) Trends Biotechnol 22(7):346
- Mauro VP (2018) Methods Mol Biol 1850:275
- Shendure J et al. (2017) doi:10.1038/nature24286
- Hoose A et al. (2023) doi:10.1038/s41570-022-00456-9
- Wannier T et al. (2021) PMC9083505