Week 2 HW: DNA design
Part 1 — What am I expressing?
My product is DNA, so there’s no protein that “makes” it — the cell’s own replication machinery does. The plasmid therefore carries two different things:
- A protein: M.SssI, a CpG DNA methyltransferase.1 It adds a methyl group to the
cytosine in every CG pair.
- Why: vertebrate DNA is CpG-methylated, bacterial DNA isn’t, and unmethylated CpG is read by the immune receptor TLR9 as a danger signal.23 This was the biggest risk identified in HW1. Methylating the DNA as it’s made makes it look vertebrate-like.
- The enzyme is a process aid — it gets thrown away during purification.
- The product: an AT-rich array of defined-length DNA units. A non-coding part whose sequence is the deliverable.
Neat detail: the plasmid is both the vector and the product — 49.6% of its mass is product.
Sequence: UniProt P15840 (386 aa)1; native gene GenBank X17195.14. My coding sequence is a redesigned version of that gene. The product array is designed from scratch.
Findings
Spiroplasma uses genetic code table 4, where TGA = tryptophan, not “stop.” The native gene has 5 tryptophan codons and 4 are TGA (codons 43, 83, 165, 203). In E. coli, translation stops at codon 43 → 42-amino-acid fragment, no enzyme.
So codon optimization isn’t about boosting yield here — it’s the only reason the gene makes protein at all.
(Check: Renbaum et al. did report expressing this in E. coli,4 probably via inefficient TGA read-through. Worth skimming their methods.)
Host: E. coli K-12 (from HW1 — DNA is ~3.1% of dry weight, giving ~2.5 g/L vs ~0.12 g/L for the Lactobacillus process in the precedent paper5). Three new requirements:
- mcrBC⁻ (mandatory) — E. coli destroys DNA containing 5-methylcytosine,6 so a cell methylating its own genome would attack its own chromosome. Most cloning strains (DH5α, DH10B) already lack it.
- dcm⁻ — removes native methylation so the only methylation is the kind I added.
- endA⁻ — stops the product being degraded during lysis.
Location: cytoplasm. No signal peptide, no tag. The enzyme has to reach DNA, which is in the cytoplasm — secreting it would separate it from its substrate. No tag because the enzyme is discarded, not purified.
Part 2 — Parts
| Type | Name | Length | Source |
|---|---|---|---|
| Terminator | rrnB_T1_insulator | 52 bp | E. coli MG16557 |
| Promoter | P_rhaBAD | 200 bp | E. coli MG16557 |
| RBS | BBa_B0034 | 12 bp | iGEM Registry8 |
| Spacer | RBS_spacer | 7 bp | designed |
| CDS | sssIM_Ecoli_opt | 1,161 bp | designed from P15840 |
| Terminator | rrnB_T1 | 52 bp | E. coli MG16557 |
| Product array | PDRN_array_8x500 | 4,072 bp | designed de novo |
| Backbone | pUC19 | 2,641 bp | GenBank L09137.29 |
Justifications, one line each:
- Terminators — block read-through from the backbone into my cassette, and stop transcription before the array (the array shouldn’t be transcribed; it’s a substrate, not a gene).
- PrhaBAD instead of T7 — M.SssI is toxic when overexpressed, so I want a promoter I can dial down. The rhamnose system was built for tunable expression of toxic proteins.10 It also fits HW1’s two-phase fermentation: grow uninduced, then induce at the end.
- RBS — characterized strong ribosome binding site, so initiation is predictable.8
- Spacer — puts the RBS 7 nt from the ATG (optimal is 5–9).
- CDS — the methyltransferase, recoded for E. coli (see Part 4).
- pUC19 — high-copy origin (~500–700 copies/cell) means more product per cell; bla for selection.9
Designing the product array
Six rules, all enforced by code:
- AT-rich (~30% GC) — more adenine per gram, which matters if the mechanism is adenosine-receptor signalling. Got 67.3% AT vs ~56–59% for salmon DNA and 49.2% for the E. coli genome. So my product is more adenine-rich than the salmon material.
- 500 bp units, each flanked by PacI (TTAATTAA).
- No PacI inside units — so it only cuts where I want.
- Units are all different sequences, not identical copies (see below).
- No run of the same base longer than 4 — a DNA-synthesis constraint.
- Biologically inert — screened out promoter-like and ribosome-binding motifs; longest accidental reading frame is ≤24 codons, so nothing encodes a peptide.
Two constraints that only show up when parts interact
(these are the interesting bits)
- The cut site has to survive my own enzyme. M.SssI methylates the C in every CG, and methylation blocks most restriction enzymes. PacI has no CG in it, so it stays cuttable. This rules out the usual rare-cutters — NotI, AscI, FseI and AsiSI all contain CG.
- Identical repeats would collapse. Tandem repeats recombine and get deleted. So each unit is a different sequence with the same length and composition. Longest exact stretch shared by any two units is 11–12 bp, under the ~20–25 bp minimum RecA needs to recombine.11 Uniform in length, not repetitive in sequence — so I don’t need a ΔrecA strain.
Part 3 — Assembled construct
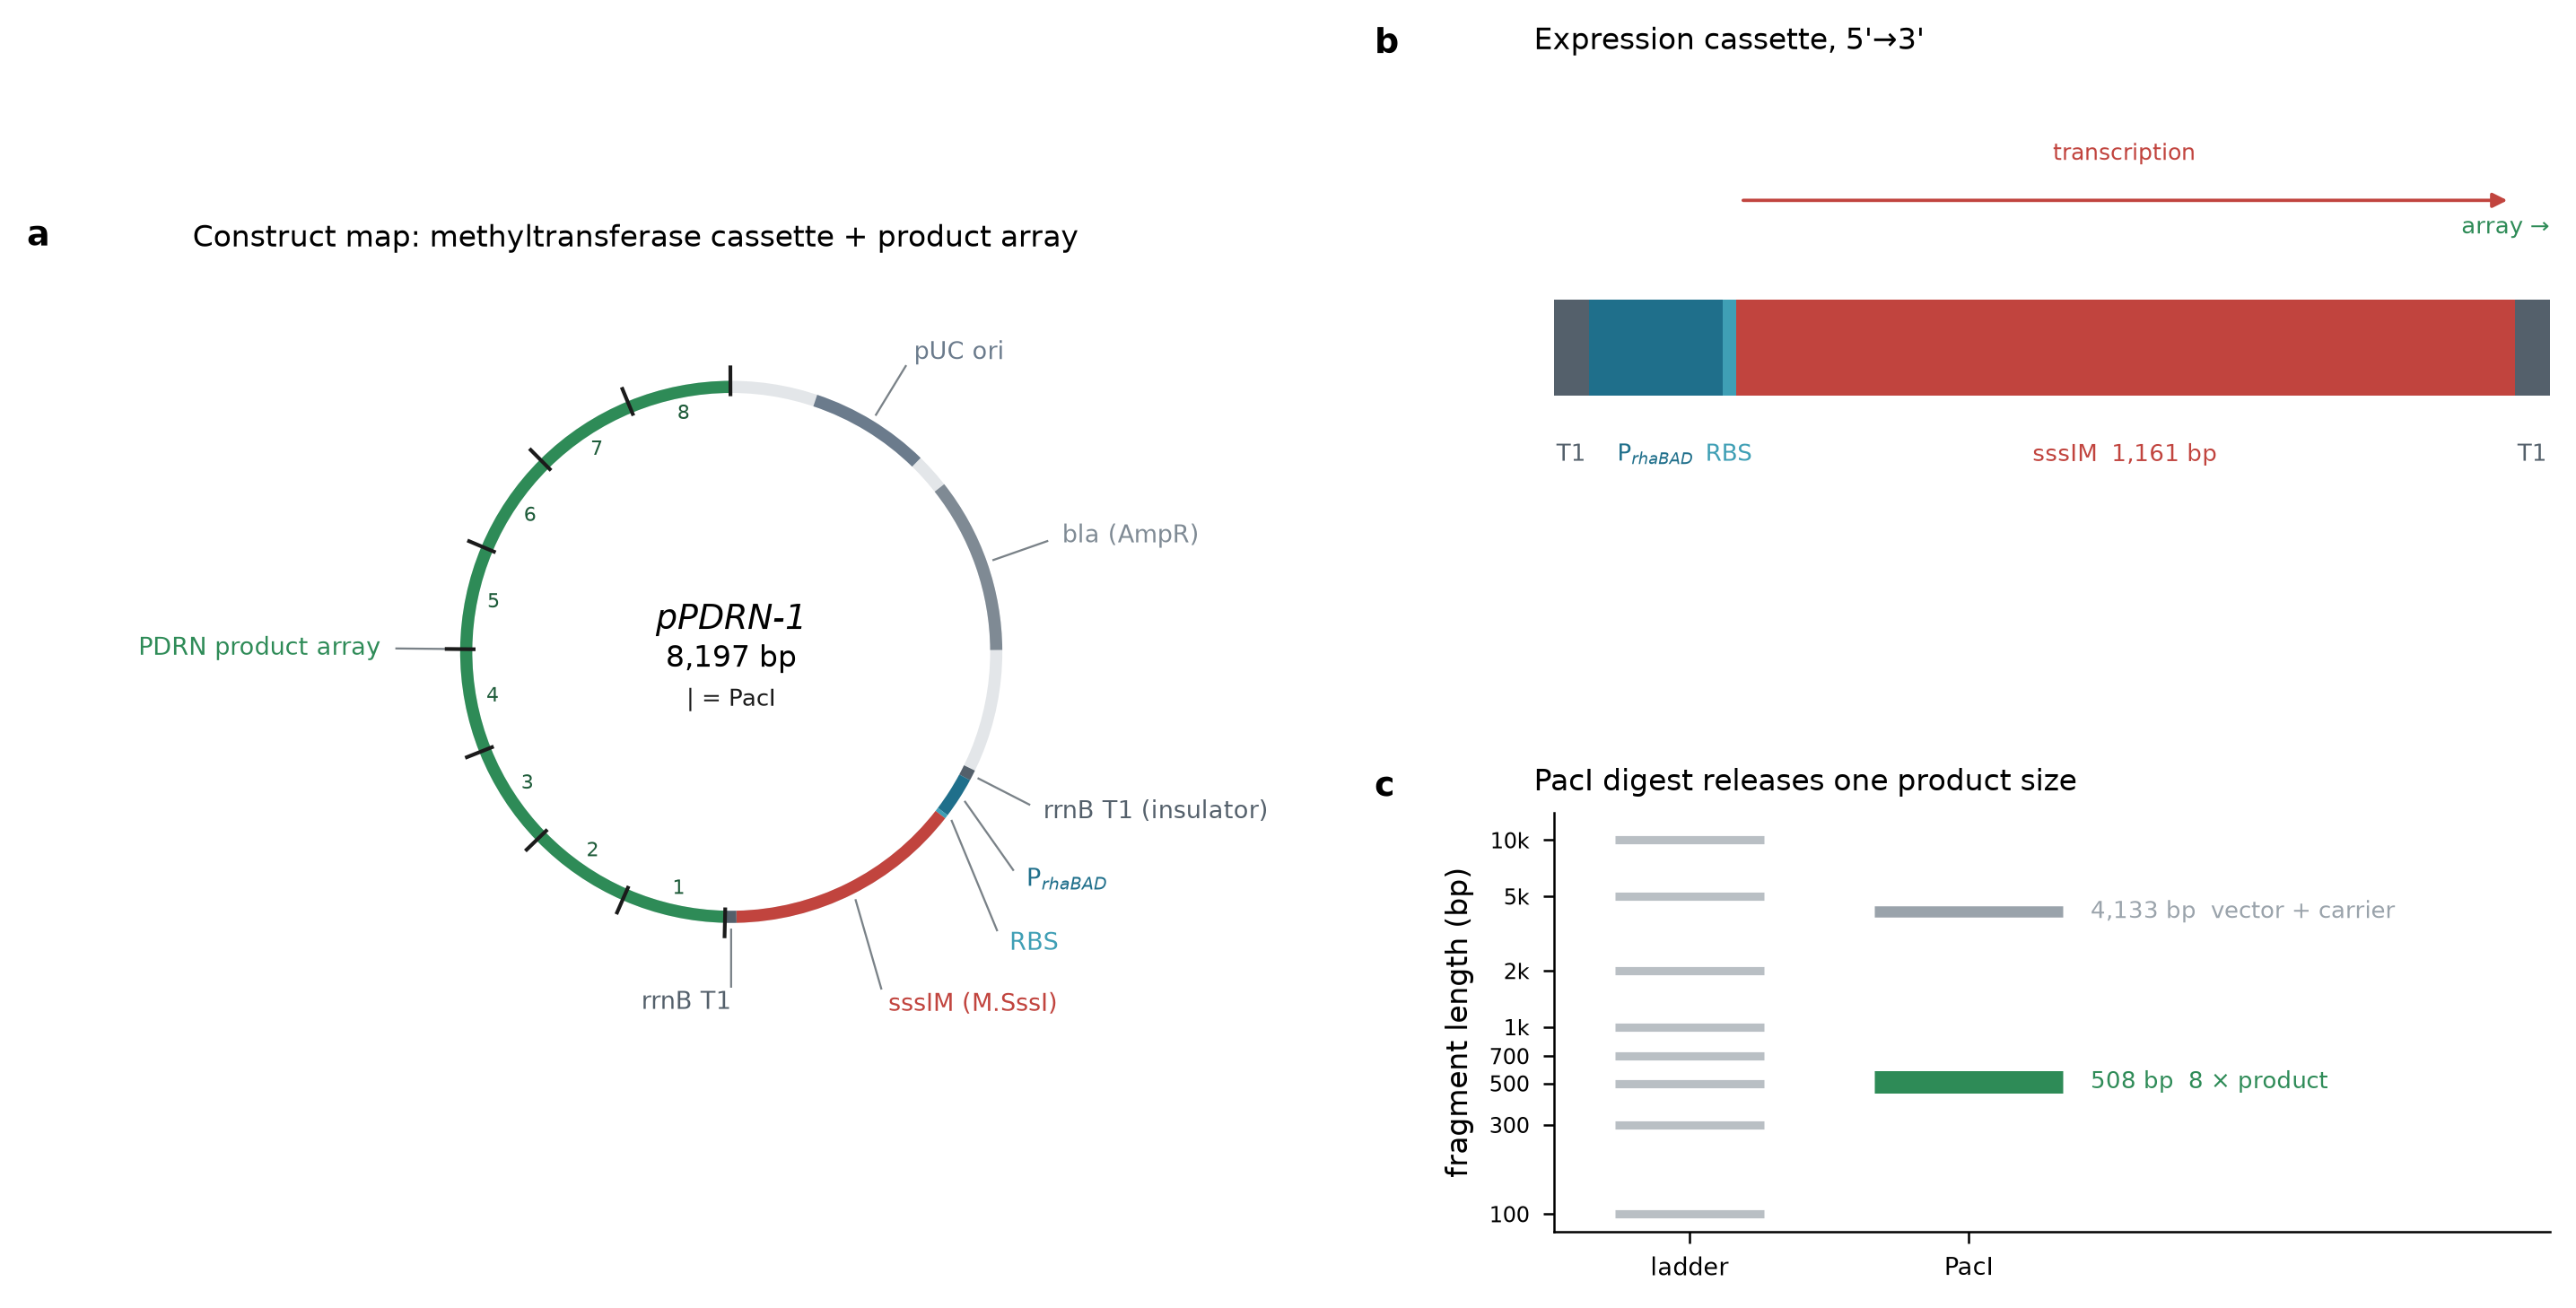
Order of parts, start to finish:
backbone → stop sign → on switch → start signal → spacer → gene → stop sign → [cut site + segment] × 8 → cut site
Why this order: the stop sign before the on-switch blocks stray signals from the backbone. The stop sign after the gene means the cell stops reading before it reaches the product segments — which is what I want, because the product is just DNA sitting there. Reading it would waste the cell’s energy for no benefit.
Checks I ran on the sequence
- Gene length is 1,161 bp — divisible by 3, as a gene must be ✓
- Begins with ATG (start) and ends with TAA (stop) ✓
- No accidental stop codons in the middle ✓
- The protein it codes for matches the database entry exactly, all 386 amino acids ✓
- 9 cut sites, which is correct for 8 segments ✓
- Whole plasmid: 8,197 bp
What happens when you cut it
I simulated the cut. It produces:
- 8 pieces of 508 bp each — all exactly the same size. This is the product.
- 1 piece of 4,133 bp — the leftover backbone, which gets discarded.
(508 rather than 500 because each piece keeps a few letters of the cut site on its ends.)
This is the whole point of the design. In HW1 I couldn’t work out how to control the fragment size — I was planning to break the DNA up mechanically, which gives a messy range of sizes. Cutting with an enzyme at designed positions gives one exact size every time.
Honest trade-off: HW1 showed that harvesting the bacteria’s own chromosomal DNA gives about 2.5 g/L, while a plasmid-based route gives only 0.24–0.8 g/L. So this design buys uniform size at the cost of yield. The saving grace is that the methylation gene is useful in both routes, so this one plasmid works either way.
Part 4 — Optimize and quality-check
Codon optimization
Built the reference from real data rather than a generic table: all 4,318 E. coli MG1655 coding sequences,7 then 77 highly expressed genes (ribosomal proteins, translation factors, chaperones) as a codon-adaptation-index reference set, following Sharp & Li.12 Optimized by simulated annealing against explicit constraints.
| Native | Recoded | |
|---|---|---|
| GC | 28.0% | 47.0% |
| CAI | 0.225 | 0.854 |
| Rare codons | 97 | 0 |
| TGA read as stop | 4 | 0 |
| Identity to native | — | 72.8% |
Why codon usage matters — three reasons:
- Genetic-code mismatch (the decisive one) — the 4 TGA codons truncate the protein at codon 43. No promoter fixes this.
- tRNA supply — 97 of 386 codons are rare in E. coli; rare codons stall ribosomes, lowering yield and giving truncated protein.
- Synthesizability — 28% GC with long A/T runs is hard to synthesize; the native gene dips below 10% GC near position 830.
Constraints applied: removed PacI (critical — an internal site would chop the CDS during product release), plus EcoRI, HindIII, NdeI, XhoI, BamHI and Golden Gate sites; GC held 40–62% per 50 bp window; no base run > 4. Zero violations.
BLAST
blastn of the recoded CDS vs NCBI nt.13
| Hit | Description | Identity | Coverage |
|---|---|---|---|
| X17195 | Spiroplasma M.SssI gene | 72.8% | 99.6% |
| CP025543 | S. monobiae MQ-1 genome | 72.8% | 99.6% |
| rest | 30–56 bp, E 0.025–3.8 | — | — |
Conclusion: it is the right gene (top two hits are the native gene and its source genome), but my version is novel at the DNA level — 72.8% identity over 99.6% coverage. Protein is 386/386 identical while ~1 nucleotide in 4 changed. That’s exactly what codon optimization looks like. Everything below the top two is background noise.
I will need to submit the BLAST search to NCBI to verify the accuracy — it’s designed from AI assistant
Safety screen
What it checks: compares each region against databases of sequences of concern — select agents, toxins, regulated pathogens, virulence factors — usually under the International Gene Synthesis Consortium Harmonized Screening Protocol,14 which synthesis companies run on orders. Scans DNA and all translation frames.
Part 5 — From design to build
How I’d build it: order synthetic DNA in three pieces, join by Gibson assembly.15
| Fragment | Length | Difficulty | Route |
|---|---|---|---|
| Backbone | 2,641 bp | trivial | PCR from existing pUC19 |
| Cassette | 1,484 bp | routine (47% GC) | one synthetic fragment |
| Product array | 4,072 bp | hard (32.7% GC, 8 similar units) | 8 separate ~508 bp fragments |
Why Gibson, not restriction cloning: Gibson joins fragments by overlapping ends and needs no restriction sites. That matters because PrhaBAD contains an internal EcoRI site and the finished plasmid has two — so classical cloning would cut inside my own promoter. Bonus: because the 8 units are all different, each junction is unique, so they assemble in a defined order. Identical repeats would scramble.
Not a chip-synthesized oligo pool16 — pools are economical for many different constructs; I want one construct with a hard repetitive region, which is where pools struggle most.
What synthesis constrains — two hard features, both designed against:
- Repetitive array — repeats cause template switching in synthesis, mispriming in PCR, and recombination in the host.17 Mitigated: units share no exact stretch over 11–12 bp.
- AT-rich (32.7% GC) — weak base pairing, and long A/T runs are where insertions and deletions concentrate. Mitigated: no base run over 4, every 100 bp window 24–40% GC, no 10 bp inverted repeats.
Error correction changes the approach: a 4 kb repetitive AT-rich fragment probably won’t come back perfect. Ordering 8 short fragments turns one low-probability synthesis into eight high-probability ones, and a failed unit gets re-ordered alone. Verify with long-read sequencing (Nanopore/PacBio), not Sanger — only long reads span the repeats and can confirm unit count and order.
Prototype vs scale:
| Prototype | Manufacturing (750 kg/yr) | |
|---|---|---|
| DNA made by | synthesis company + Gibson, ~2–3 weeks | not synthesized — replicated by the cells |
| Cost | ~$0.07–0.10/bp, a few hundred dollars | glucose + salts (HW1: media ≈ 4% of ~$8/g) |
| Selection | bla / ampicillin | antibiotic-free — no residue in a skin product |
| Amount | micrograms | ~1,000 kg/yr |
Core idea: synthesis is how you build the design once; biology is how you manufacture it. At $0.07/bp a single gram of synthetic DNA would cost more than the annual media bill.
Part 6 — What I don’t know yet
1. Will methylation be complete, and will the cells survive it? Partial methylation may leave enough unmethylated CpG to trigger TLR9, breaking the main quality claim. Full methylation may be lethal. There may be no induction level that satisfies both — the most serious failure mode. How to find out: rhamnose dose series in parallel micro-bioreactors; measure % 5-methylcytosine by LC-MS/MS, plus growth rate and DNA yield → a methylation-vs-yield curve. Run a TLR9 reporter assay on the product vs salmon PDRN in the same experiment. Fallback: methylate in vitro after purification instead.
2. Is 508 bp the right size — does size even matter? The conventional PDRN spec is 50–1500 bp, the salmon comparator was 200–800 bp, and the precedent paper’s microbial material was under 100 bp yet performed better.5 So nothing supports a target size, or the premise that tight control is worth the yield penalty. How to find out: build 150, 500 and 1000 bp unit variants → three uniform products differing only in length; dose–response in the precedent paper’s assays with an adenosine-receptor antagonist as control. If size doesn’t matter, the array route is unnecessary and HW1’s genomic-DNA route wins — so this is a go/no-go.
3. Will the array survive fermentation? The ~20–25 bp recombination threshold11 is a generalization, not a guarantee, and there are 500–700 plasmid copies per cell. A partly collapsed array still gives correctly sized product, just less of it — so it shows up as slow titre decline and is easy to miss. How to find out: serial passage to 40–60 generations, long-read sequencing to count units per plasmid, PacI digest + capillary electrophoresis for product-to-carrier ratio. If it declines: fewer units, more divergence, lower-copy origin, or fall back to ΔrecA.
Appendix (AI Prompts)
Anthropic. (2026). Claude Science (Opus 5)
- Pasted my HW1 submission on animal-free PDRN and asked for review and expansion.
- “Follow up on homework 2, I am required to design the DNA, these are the following questions I need to answer. Include relevant sources to back up your statements.
How figures were made
- Figure 1 (construct map, cassette schematic, digest) — feature coordinates come from the assembled sequence; the fragment sizes in the gel panel come from a simulated PacI digest run with Biopython’s restriction module.
Sources
UniProt P15840 — orphan methyltransferase M.SssI, Spiroplasma monobiae strain ATCC 33825 / MQ-1; 386 aa, 44.3 kDa, EC 2.1.1.37. Annotated as acting “completely and exclusively on CG residues in DNA.” ↩︎ ↩︎
Krieg AM et al. (1995) CpG motifs in bacterial DNA trigger direct B-cell activation. Nature 374:546–549. ↩︎
Hemmi H et al. (2000) A Toll-like receptor recognizes bacterial DNA. Nature 408:740–745. (TLR9.) ↩︎
GenBank X17195.1 (protein CAA35058.1) — Spiroplasma sp. M-SssI gene for CpG DNA methylase, CDS 103..1263. Confirmed to translate to exactly the P15840 protein, but only under NCBI translation table 4. Primary reference: Renbaum P, Abrahamove D, Fainsod A, Wilson GG, Rottem S, Razin A (1990) Cloning, characterization, and expression in Escherichia coli of the gene coding for the CpG DNA methylase from Spiroplasma sp. strain MQ1 (M.SssI). Nucleic Acids Research 18(5):1145–1152. PMID 2181400. ↩︎ ↩︎
Chae D, Oh S-W, Choi Y-S, Kang D-J, Park C-W, Lee J, Seo W-S (2025) First report on microbial-derived polydeoxyribonucleotide: a sustainable and enhanced alternative to salmon-based polydeoxyribonucleotide. Current Issues in Molecular Biology 47(1):41. doi:10.3390/cimb47010041. Full text reviewed — L. rhamnosus, genomic DNA, fragments <100 bp vs 200–800 bp for salmon. ↩︎ ↩︎
Raleigh EA, Wilson G (1986) Escherichia coli K-12 restricts DNA containing 5-methylcytosine. PNAS 83:9070–9074. (The McrBC constraint.) ↩︎
NCBI NC_000913.3 — Escherichia coli K-12 MG1655 reference genome. PrhaBAD from the rhaS–rhaB intergenic region (4,097,536–4,097,735, minus strand); rrnB T1 terminator located by hairpin-core search and verified at position 4,171,772; all 4,318 coding sequences used for the codon-usage reference set. ↩︎ ↩︎ ↩︎ ↩︎
iGEM Parts Registry, part BBa_B0034 (ribosome binding site). ↩︎ ↩︎
GenBank L09137.2 — cloning vector pUC19, 2,686 bp. The bla gene located by open-reading-frame search at 1,625–2,486 (minus strand), 286 aa, beginning MSIQHFRVALIPFFAAFCLPVFA — not taken from a vector map. ↩︎ ↩︎
Giacalone MJ et al. (2006) Toxic protein expression in Escherichia coli using a rhamnose-based tightly regulated and tunable promoter system. BioTechniques 40:355–364. ↩︎
Shen P, Huang HV (1986) Homologous recombination in Escherichia coli: dependence on substrate length and homology. Genetics 112:441–457. (Source of the ~20–25 bp minimum efficient processing segment.) ↩︎ ↩︎
Sharp PM, Li W-H (1987) The codon adaptation index — a measure of directional synonymous codon usage bias, and its potential applications. Nucleic Acids Research 15:1281–1295. ↩︎
NCBI blastn, recoded CDS vs the
ntdatabase, request ID BNJECKKN014, 22 hits. Results inblast_optCDS_hits.csv. ↩︎International Gene Synthesis Consortium, Harmonized Screening Protocol. ↩︎
Gibson DG et al. (2009) Enzymatic assembly of DNA molecules up to several hundred kilobases. Nature Methods 6:343–345. ↩︎
Tian J et al. (2004) Accurate multiplex gene synthesis from programmable DNA microchips. Nature 432:1050–1054. ↩︎
Kosuri S, Church GM (2014) Large-scale de novo DNA synthesis: technologies and applications. Nature Methods 11:499–507. ↩︎