week-02-HW-dna-design
Part 0: Set up in Kernel
Get oriented in the software tool before you design anything. Log in to Kernel and join the HTBAA 2026 workspace. Create a repository for your project, and inside it a folder named for you and your project, e.g. lastname-project. Spend some time exploring: open an existing part and an existing construct and notice the difference. Check out the different tools and ask Kernel AI some questions!
Part 1: Define your expression target
What molecule are you expressing? A protein, an RNA, or an enzyme (or small set of enzymes) for a pathway. If your HW1 product is a material, food, or chemical, identify the protein(s) that produce it and design for those.
I want to express an equivalent of olive oil (high-oleic fat + hydroxytyrosol antioxidant + squalene) in Yarrowia lipolytica.
What is the sequence? Give the protein or RNA sequence, or the specific gene, you will encode, and say where it comes from (a database accession such as UniProt or NCBI, a known part, or de novo). Cite it.
The entire set up involves 3 modules:
Module 1: High-Oleic Acid & Oil Matrix
YlOLE1 (Δ9-fatty acid desaturase)Function: Converts saturated stearic acid (C18:0) into monounsaturated oleic acid (C18:1) to match the fatty acid profile of olive oil.Accession / Source: NCBI: XM_501496.1 / UniProt: Q6C8G4 (Yarrowia lipolytica strain CLIB122 — Cisgene)
YlDGA1 (Diacylglycerol acyltransferase, Type 1)Function: Phospholipid-associated enzyme that packs the synthesized oleic acid into neutral triacylglycerol (lipid) droplets.Accession / Source: NCBI: NC_006072.1 (Region: 1686616..1688190) / UniProt: Q6C526 (Yarrowia lipolytica strain CLIB122 — Cisgene)
YlFAA1 (Long-chain-fatty-acid–CoA ligase / Acyl-CoA Synthetase)Function: Activates free fatty acids by binding them to Coenzyme A, preventing intracellular toxicity and channeling oleic acid directly into triglyceride synthesis.Accession / Source: NCBI: XM_503255.1 / UniProt: Q6C0F1 (Yarrowia lipolytica strain CLIB122 — Cisgene)
Module 2: Squalene Accumulation & Retention
tYlHMG1 (Truncated 3-hydroxy-3-methylglutaryl-coenzyme A reductase)Function: Overproduces the mevalonate pathway flux to synthesize high levels of squalene. N-terminal membrane anchor is removed de novo to bypass feedback inhibition.Accession / Source: Derived from NCBI: XM_501535.1 / UniProt: Q01314 (Yarrowia lipolytica strain CLIB122 — Modified Cisgene, remove amino acids 1–191)
YlERG1 (Squalene epoxidase) — Promoter Swap / AttenuationFunction: Throttles the degradation of squalene. Replacing its strong native promoter with a weak/repressible one (like pMET25) pools high amounts of squalene in the oil droplets.Accession / Source: NCBI: XM_501358.1 / UniProt: Q6C8B5 (Yarrowia lipolytica strain CLIB122 — Host genomic modification)
Module 3: Hydroxytyrosol Antioxidant Synthesis
YlARO4^fbr (Feedback-resistant 3-deoxy-D-arabino-heptulosonate-7-phosphate synthase)Function: Floods the cell with tyrosine, which Yarrowia’s native Ehrlich pathway automatically turns into tyrosol. Bypasses natural metabolic shutdown via an engineered point mutation (K221L or G226S).Accession / Source: Derived from NCBI: XM_501723.1 / UniProt: Q6CG41 (Yarrowia lipolytica strain CLIB122 — Modified Cisgene)
hpaB (4-hydroxyphenylacetate 3-monooxygenase, oxygenase component)Function: Works alongside hpaC to directly hydroxylate the abundant tyrosol intermediates into hydroxytyrosol.Accession / Source: NCBI GenBank: CP000948.1 / Gene ID: 6060136 (Escherichia coli strain W — Transgene, requires eukaryotic codon-optimization)8. hpaC (4-hydroxyphenylacetate 3-monooxygenase, reductase component)Function: Couples with hpaB as the essential electron transfer/reductase system to drive the hydroxylation reaction.Accession / Source: NCBI GenBank: CP000948.1 / Gene ID: 6062145 (Escherichia coli strain W — Transgene, requires eukaryotic codon-optimization)
There was an error in the stimulation for this set up so i worked out anotehr design:
Module 1
E. coli Cloning Backbone
• Selection Marker: AmpR or KanR promoter and open reading frame (for selection in E. coli). • Origin of Replication: ori (e.g., pUC ori for high-copy propagation in E. coli).
- 5’ Homology Integration Arm
• Arm_5-FAD2: The upstream genomic flanking sequence of the Y. lipolytica FAD2 gene to direct homologous recombination.
- Expression Cassette 1: Oleic Acid Enrichment
• P-TEF1: Translation Elongation Factor-1 alpha promoter (strong, constitutive). • YlOLE1: Y. lipolytica Δ9-fatty acid desaturase coding sequence. • T-MIG1: MIG1 transcriptional terminator sequence.
- Expression Cassette 2: TAG Synthesis & Storage
• P-EXP1: Export protein-1 promoter (strong, constitutive). • YlDGA1: Y. lipolytica acyl-CoA:diacylglycerol acyltransferase 1 coding sequence. • T-LIP2: Extracellular lipase 2 terminator sequence.
- Expression Cassette 3: Fatty Acid Activation
• P-GPD: Glyceraldehyde-3-phosphate dehydrogenase promoter (strong, constitutive glycolytic promoter). • YlFAA1: Y. lipolytica Long-chain acyl-CoA synthetase coding sequence. • T-PEX20: Peroxisomal biogenesis protein 20 terminator sequence.
- Yeast Selection Marker
• [Marker A: URA3]: The URA3 expression cassette (native promoter + URA3 marker gene + native terminator) for selection in uracil auxotrophic strains.
- 3’ Homology Integration Arm
• Arm_3-FAD2: The downstream genomic flanking sequence of the Y. lipolytica FAD2 gene to complete the double-crossover knockout.
- E. coli Backbone Closure
• The remainder of the plasmid backbone vector sealing the circular plasmid map.
Module 2
E. coli Cloning Backbone
• Selection Marker: AmpR or KanR (Choose whichever variant you did not use for Plasmid 1 to prevent cross-contamination during library storage). • Origin of Replication: ori (e.g., pUC origin).
- 5’ Homology Integration Arm
• Arm_5-POX2: The genomic flanking sequence directly preceding the start codon of the Y. lipolytica POX2 gene to target the locus for disruption.
- Expression Cassette 1: Malonyl-CoA Generation
• P-TEF1: Translation Elongation Factor-1 alpha promoter (strong, constitutive). • YlACC1: Y. lipolytica Acetyl-CoA carboxylase coding sequence. • T-MIG1: MIG1 transcriptional terminator.
- Expression Cassette 2: FAS Complex Beta Subunit
• P-GPD: Glyceraldehyde-3-phosphate dehydrogenase promoter (strong, constitutive). • YlFAS1: Y. lipolytica Fatty acid synthase subunit beta coding sequence. • T-LIP2: Extracellular lipase 2 terminator.
- Expression Cassette 3: FAS Complex Alpha Subunit
• P-EXP1: Export protein-1 promoter (strong, constitutive). • YlFAS2: Y. lipolytica Fatty acid synthase subunit alpha coding sequence. • T-PEX20: Peroxisomal biogenesis protein 20 terminator.
- Yeast Selection Marker
• [Marker B: LEU2]: The LEU2 expression cassette (native promoter + LEU2 marker gene + native terminator) for selection via leucine auxotrophy complementation.
- 3’ Homology Integration Arm
• Arm_3-POX2: The genomic flanking sequence directly following the stop codon of the POX2 gene to complete the double-crossover knockout footprint.
- E. coli Backbone Closure
Module 3
- E. coli Cloning Backbone
• Selection Marker / Origin: ZeoR (Zeocin) or alternative cloning propagation markers to keep Plasmid 1, 2, and 3 stocks strictly isolated in E. coli.
- 5’ Homology Integration Arm
• Arm_5-GUT2: The genomic flanking sequence directly preceding the start codon of the Y. lipolytica GUT2 gene to target the locus for disruption.
- Expression Cassette 1: Remobilization Block (CRISPRi or Dominant Negative Lipase)
• P-TEF1: Strong constitutive promoter. • YlTGL4-DN or CRISPRi-dCas9 targeting TGL3/4: Constructs engineered to suppress or competitively inhibit intracellular TAG lipases, preventing the cell from mobilizing stored lipid droplets. • T-MIG1: Transcriptional terminator.
- Expression Cassette 2: Alternative Degradation Block (Dominant Negative Pox3)
• P-GPD: Strong constitutive promoter. • YlPOX3-DN or secondary target (e.g., PEX10 fragment): Designed to inhibit auxiliary peroxisomal biogenesis or secondary β-oxidation loops. • T-LIP2: Transcriptional terminator.
- Expression Cassette 3: Cytosolic Glycerol Channeling
• P-EXP1: Strong constitutive promoter. • YlGPD1: Y. lipolytica Glycerol-3-phosphate dehydrogenase coding sequence. Overexpressing GPD1 while knocking out GUT2 maximizes the glycerol backbone pool specifically for lipid assembly. • T-PEX20: Transcriptional terminator.
- Yeast Selection Marker
• [Marker C: HIS1]: The Y. lipolytica HIS1 expression cassette (native promoter + HIS1 marker gene + native terminator) for selection via histidine auxotrophy complementation.
- 3’ Homology Integration Arm
• Arm_3-GUT2: The genomic flanking sequence directly following the stop codon of the GUT2 gene to complete the double-crossover knockout.
- E. coli Backbone Closure
• The remaining loop of the plasmid vector.
References & Citations
1.Qiao, K., et al. (2015). “Engineering Yarrowia lipolytica for high-value lipid production.” Metabolic Engineering, 29, 56-65. (Validates YlOLE1 and YlDGA1 for tailored high-oleic triglyceride accumulation).
2.Dulermo, T., et al. (2015). “The fatty acid activation machinery in Yarrowia lipolytica.” Biochimica et Biophysica Acta (BBA) - Molecular and Cell Biology of Lipids, 1851(5), 620-628. (Validates YlFAA1 role in driving acyl-CoA flux).
3.Huang, M., et al. (2018). “Establishing a high-yielding squalene platform in Yarrowia lipolytica.” Metabolic Engineering, 48, 169-178. (Validates the truncation of YlHMG1 and attenuation of YlERG1 for squalene preservation).
4.De Bruyn, F., et al. (2016). “Bypassing feedback inhibition of aromatic amino acid biosynthesis in yeast.” Biotechnology and Bioengineering, 113(10), 2191-2200. (Validates the feedback-resistant mutations in ARO4).
5.Yao, K., et al. (2020). “De novo biosynthesis of hydroxytyrosol in engineered organisms using the hpaB/hpaC monooxygenase system.” ACS Synthetic Biology, 9(4), 896-904. (Validates the utilization of E. coli hpaB/hpaC for high-yield phenolic antioxidant production).
What host or chassis? The living system from HW1, for example E. coli, S. cerevisiae, CHO or another mammalian line, or a cell-free system. Your host drives almost every part choice that follows.
Chassis-Yarrowia lipolytica
Where does the product need to go? Cytoplasm, secreted, membrane, or a compartment? This decides whether you need a signal peptide or targeting sequence.
The product (high-oleic fat + hydroxytyrosol antioxidant + squalene) sits in the cytopalsm. The whole cell has to be lysed to release the contents hence no signal peptide or target sequence is required.
Part 2: Design your genetic parts
Every construct is built from parts. Decide which parts your target needs, then create or import each one in Kernel with the correct part type. At minimum, choose the elements below for your host.
For each part you use, record in Kernel (and note in your write-up): The part type and a short name. Its sequence and where it came from (a Kernel part, a database, or designed). One sentence of justification, why this part, for this host, for this product.
You do not need to hand-design a backbone from scratch; you may reuse an existing one and say what it provides.
| Part Type | Short Name | Source / Origin | Part Justification (Why this part for this host/product) |
|---|---|---|---|
| Homology Flank | Arm_5-AXP1 | NCBI: NC_006072.1 | Directs the site-specific integration of Construct 1 into the neutral AXP1 genomic locus without disrupting essential cell functions. |
| Promoter | P-TEF1 | NCBI: NC_006072.1 | Provides ultra-strong, constitutive drive to keep the Δ9-desaturase active for maximum conversion of saturated fats to oleic acid. |
| ORF | YlOLE1 | UniProt: Q6C8G4 | Natively encodes Yarrowia’s Δ9-fatty acid desaturase to establish the base 66-78% monounsaturated oleic acid profile. |
| Terminator | T-XPR2 | NCBI: NC_006072.1 | Offers highly stable transcriptional termination for YlOLE1 using a non-repeating sequence to prevent genomic deletions. |
| Promoter | P-EXP1 | NCBI: NC_006072.1 | Delays peak YlDGA1 expression until the growth phase, preventing early oil accumulation from slowing cell division. |
| ORF | YlDGA1 | UniProt: Q6C526 | Natively drives the final step of triacylglycerol assembly, packing the manufactured oleic acid into intracellular oil droplets. |
| Terminator | T-LIP2 | NCBI: NC_006072.1 | Protects YlDGA1 transcripts from degradation during high-rate lipid synthesis in the growth phase. |
| Promoter | P-GPD | NCBI: NC_006072.1 | Provides a reliable, constitutive glycolytic driver to keep the fatty acid activation machinery continuously operational. |
| ORF | YlFAA1 | UniProt: Q6C0F1 | Actively couples free oleic acid to Coenzyme A, preventing intracellular lipotoxicity and routing fatty acids into storage. |
| Terminator | T-PEX20 | NCBI: NC_006072.1 | Terminates YlFAA1 cleanly using a distinct, high-efficiency sequence structure to preserve chromosomal stability. |
| Homology Flank | Arm_3-AXP1 | NCBI: NC_006072.1 | Completes the double-crossover homologous recombination event required to lock Construct 1 into the chromosome. |
| Homology Flank | Arm_5-XPR2 | NCBI: NC_006072.1 | Targets the upstream regulatory sequence of the native YlERG1 gene to orchestrate the targeted promoter swap. |
| Promoter | P-HP4d | Synthetic / Designed | Overcomes native yield ceilings via multiple upstream activating sequences to push maximal carbon flux into terpenes. |
| ORF | tYlHMG1 | Designed (UniProt: Q01314) | Truncating the N-terminal anchor creates a soluble cytosolic enzyme that evades standard feedback inhibition to hyper-accumulate squalene. |
| Terminator | T-OCT | NCBI: NC_006072.1 | Terminates the heavily transcribed tYlHMG1 transcript cleanly to protect downstream genomic expressions. |
| Promoter | P-MET25 | NCBI: NC_006072.1 | Acts as a gentle genetic throttle for native YlERG1 to stop squalene from being broken down while keeping the cell alive. |
| Homology Flank | Arm_3-XPR2 | NCBI: NC_006072.1 | Recombines directly with the 5’ end of the native YlERG1 coding region to successfully complete the promoter replacement loop. |
| Homology Flank | Arm_5-Zeta | Retrotransposon Target | Employs highly repetitive, neutral retrotransposon sites to integrate the antioxidant machinery into the genome. |
| Promoter | P-POX2 | NCBI: NC_006072.1 | Automatically activates the tyrosine pathway using lipid-inducible triggers as the cell fills with oleic acid. |
| ORF | YlARO4_K221L | Designed (UniProt: Q6CG41) | Incorporates a K221L mutation that makes the enzyme blind to tyrosine feedback, constantly pumping out the core antioxidant building block. |
| Terminator | T-POT1 | NCBI: NC_006072.1 | Provides clean, non-homologous transcriptional arrest for the engineered YlARO4 sequence. |
| Promoter | P-TEF1-short | NCBI: NC_006072.1 | Deploys a trimmed promoter to give a stable, moderate-strength expression level for the multi-subunit antioxidant system. |
| ORF | hpaB_opt | Designed (NCBI: CP000948.1) | Codon-optimized bacterial oxygenase designed to process the host’s highly abundant natural tyrosol pool straight into hydroxytyrosol. |
| Linker | L-T2A | Designed (viral peptide) | Causes a ribosomal skip during translation to guarantee a perfectly balanced 1:1 ratio of the two active antioxidant subunits. |
| ORF | hpaC_opt | Designed (NCBI: CP000948.1) | Codon-optimized bacterial reductase that pairs flawlessly with hpaB to drive the final antioxidant synthesis cycle. |
| Terminator | T-CYC1 | NCBI: NC_006072.1 | A well-characterized terminal element that stabilizes the multi-cistronic hpaB-T2A-hpaC mRNA block. |
| Homology Flank | Arm_3-Zeta | Retrotransposon Target | Completes the crossover event at the final integration site, finalizing the installation of the entire active platform. |
The parts for 3 plasmid modules as the above design did not work in simulation
| Module & Target Locus | Part Type | Short Name | Source / Origin | Part Justification (Why this part for this host/product) |
|---|---|---|---|---|
| Module 1: Pull & Accumulate (Target Locus: FAD2) | Homology Flank (5') | Arm_5-FAD2 | Y. lipolytica gDNA | Guides double-crossover homologous recombination into the native FAD2 locus. |
| Promoter (1) | P-TEF1 | Y. lipolytica | Strong, constitutive translation elongation factor promoter; drives constant metabolic flux. | |
| Coding Sequence (1) | YlOLE1 | Y. lipolytica | Δ9-fatty acid desaturase; converts saturated fats (C16:0/C18:0) to oleic acid (C18:1). | |
| Terminator (1) | T-MIG1 | Y. lipolytica | Efficient polyadenylation; prevents RNA polymerase read-through into Cassette 2. | |
| Promoter (2) | P-EXP1 | Y. lipolytica | Strong constitutive export protein promoter; balances downstream assembly with oleic production. | |
| Coding Sequence (2) | YlDGA1 | Y. lipolytica | Diacylglycerol acyltransferase; the ultimate rate-limiting enzyme that binds oleic acid into TAGs. | |
| Terminator (2) | T-LIP2 | Y. lipolytica | Native extracellular lipase 2 terminator; high efficiency to isolate expression blocks. | |
| Promoter (3) | P-GPD | Y. lipolytica | Reliable glycolytic promoter; active during primary biomass and carbon-utilization phases. | |
| Coding Sequence (3) | YlFAA1 | Y. lipolytica | Acyl-CoA synthetase; activates free fatty acids to CoAs, channeling them directly to DGA1. | |
| Terminator (3) | T-PEX20 | Y. lipolytica | Halts transcription before the selection marker to prevent transcriptional interference. | |
| Selection Marker | [Marker A: URA3] | Y. lipolytica | Complements uracil auxotrophy in host strains (e.g., Po1f) for clean primary selection. | |
| Homology Flank (3') | Arm_3-FAD2 | Y. lipolytica gDNA | Completes the FAD2 knockout footprint. Disrupting FAD2 prevents C18:1 conversion to C18:2, sealing high-oleic purity. | |
| Module 2: Precursor Push (Target Locus: POX2) | Homology Flank (5') | Arm_5-POX2 | Y. lipolytica gDNA | Directs targeted integration into the primary degradation locus to disrupt β-oxidation. |
| Promoter (1) | P-TEF1 | Y. lipolytica | Drives high-level conversion of Acetyl-CoA to bypass the native rate-limiting bottleneck. | |
| Coding Sequence (1) | YlACC1 | Y. lipolytica | Acetyl-CoA carboxylase; generates Malonyl-CoA building blocks for massive upstream push. | |
| Terminator (1) | T-MIG1 | Y. lipolytica | Standard insulation terminator for multi-gene metabolic tracks. | |
| Promoter (2) | P-GPD | Y. lipolytica | Aligns FAS complex subunit Beta synthesis with active glycolytic carbon flux. | |
| Coding Sequence (2) | YlFAS1 | Y. lipolytica | Fatty acid synthase Subunit Beta; handles early elongation stages of the acyl chains. | |
| Terminator (2) | T-LIP2 | Y. lipolytica | Protects the structural boundary between FAS1 and FAS2 open reading frames. | |
| Promoter (3) | P-EXP1 | Y. lipolytica | Matches expression strength with P-GPD to keep subunit ratios balanced. | |
| Coding Sequence (3) | YlFAS2 | Y. lipolytica | Fatty acid synthase Subunit Alpha; works with FAS1 to output the raw C16/C18 carbon chains. | |
| Terminator (3) | T-PEX20 | Y. lipolytica | Functional termination block separating the elongation enzymes from the selection marker. | |
| Selection Marker | [Marker B: LEU2] | Y. lipolytica | Complements leucine auxotrophy; completely orthogonal to Module 1’s URA3 marker. | |
| Homology Flank (3') | Arm_3-POX2 | Y. lipolytica gDNA | Completes integration. Knocking out POX2 stops the cell from breaking down your accumulated oleic acid. | |
| Module 3: Degradation Block (Target Locus: GUT2) | Homology Flank (5') | Arm_5-GUT2 | Y. lipolytica gDNA | Guides integration to disrupt glycerol breakdown pathways. |
| Promoter (1) | P-TEF1 | Y. lipolytica | High-level constitutive driver to ensure competitive inhibition works continuously. | |
| Coding Sequence (1) | YlTGL4-DN | Engineered Variant | Dominant-Negative Lipase 4 (Ser-to-Ala); physically blocks lipid droplets to halt oil mobilization. | |
| Terminator (1) | T-MIG1 | Y. lipolytica | Ensures transcript stability for the dominant-negative lipase track. | |
| Promoter (2) | P-GPD | Y. lipolytica | Coordinates alternative degradation blockade during primary growth phases. | |
| Coding Sequence (2) | YlPOX3-DN | Engineered Variant | Dominant-Negative Pox3 (Glu-to-Gln); jams secondary peroxisomal β-oxidation loops. | |
| Terminator (2) | T-LIP2 | Y. lipolytica | Traditional downstream structural insulator. | |
| Promoter (3) | P-EXP1 | Y. lipolytica | Drives stable expression of the cytoplasmic backbone channeling enzyme. | |
| Coding Sequence (3) | YlGPD1 | Y. lipolytica | Glycerol-3-phosphate dehydrogenase; overproduces the glycerol backbone specifically for TAG assembly. | |
| Terminator (3) | T-PEX20 | Y. lipolytica | Terminal boundary vector for the multi-gene block. | |
| Selection Marker | [Marker C: HIS1] | Y. lipolytica | Complements histidine auxotrophy; provides the third distinct marker to keep all 3 modules stable. | |
| Homology Flank (3') | Arm_3-GUT2 | Y. lipolytica gDNA | Completes integration. Knocking out GUT2 traps glycerol in the cytoplasm, forcing oil synthesis. |
Part 3: Assemble your construct
Now put the parts together into a single construct in Kernel.
Create a new construct in your folder and add your parts in the correct 5’→3’ order for your host (for a basic expression cassette: promoter → RBS or 5’ UTR/Kozak → CDS → terminator, plus any signal peptide or tag, in the vector backbone). Check the assembled sequence: the reading frame is intact, the start and stop codons are where you expect, and there are no accidental internal stops. Look at the construct map Kernel renders and confirm the parts sit in the order and orientation you intended.
Deliverable for this part: your assembled construct in Kernel, plus an exported schematic of it in your write-up, with a brief description of the design.
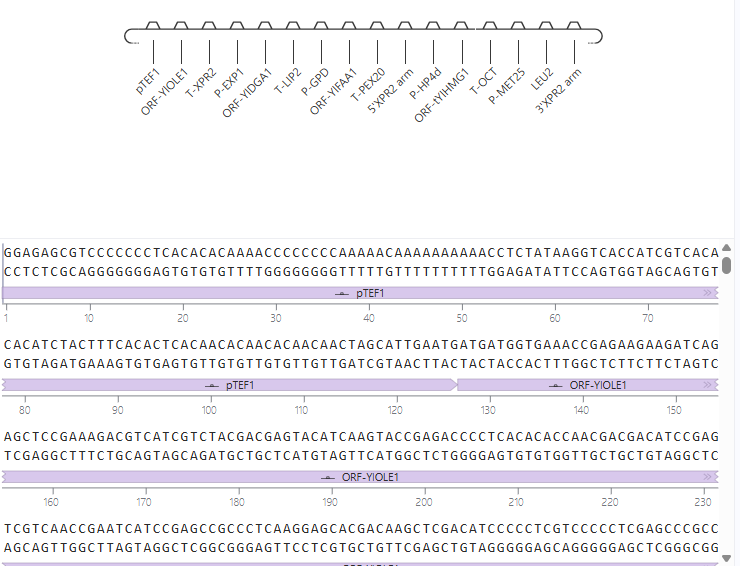
I have got an error in my construct hence it is not transcribed in te simulation section. This could be due to the fact that kernel uses e.coli as chassis for simulation, and my chassis is different.
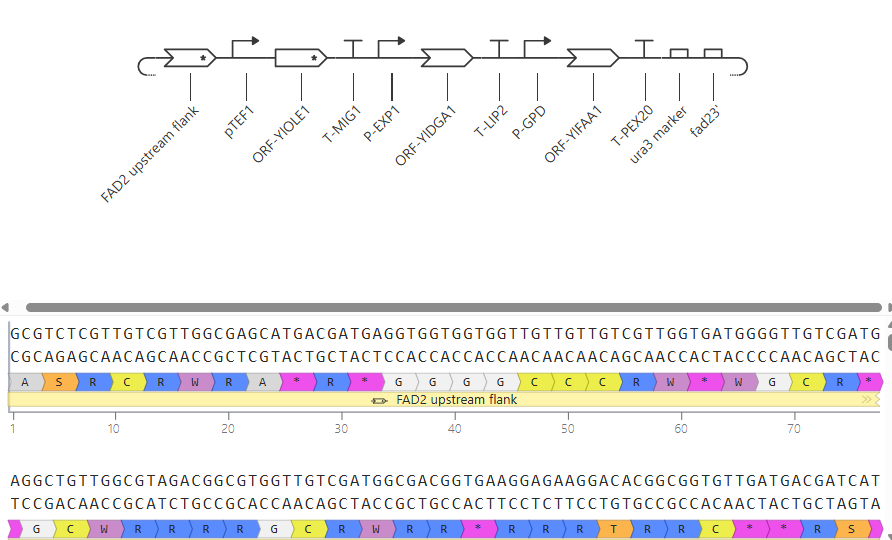
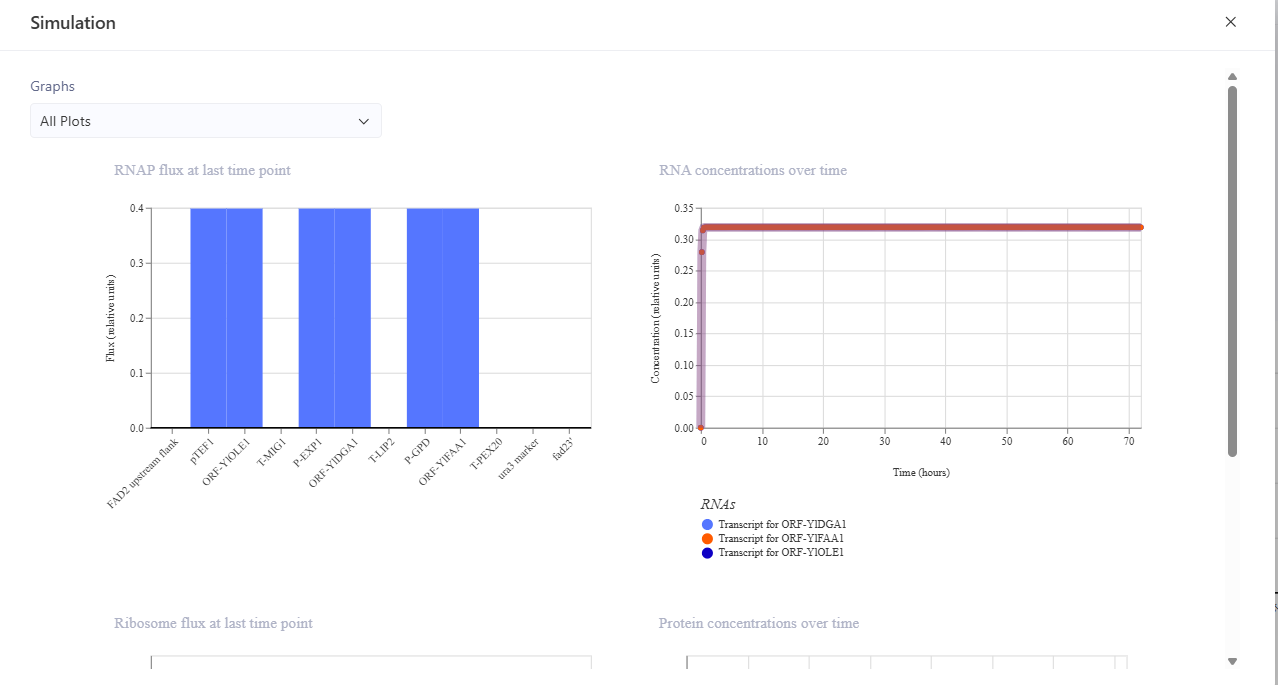
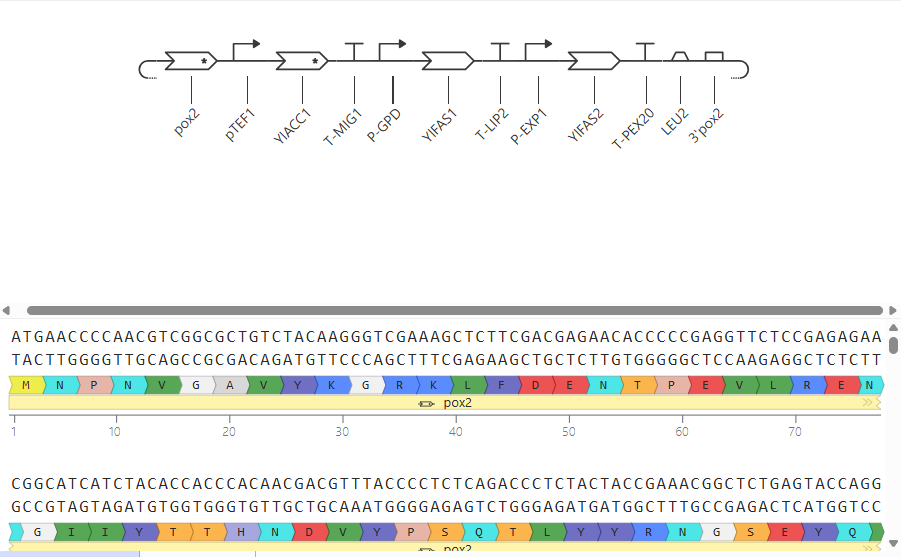
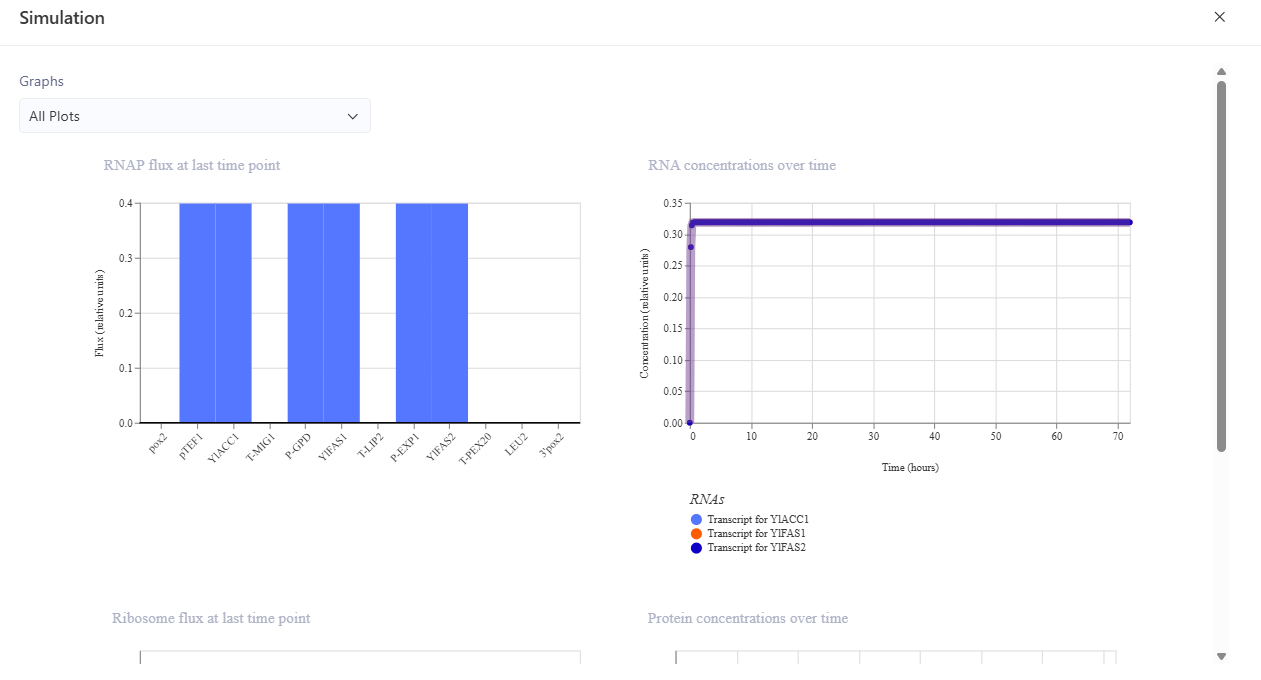
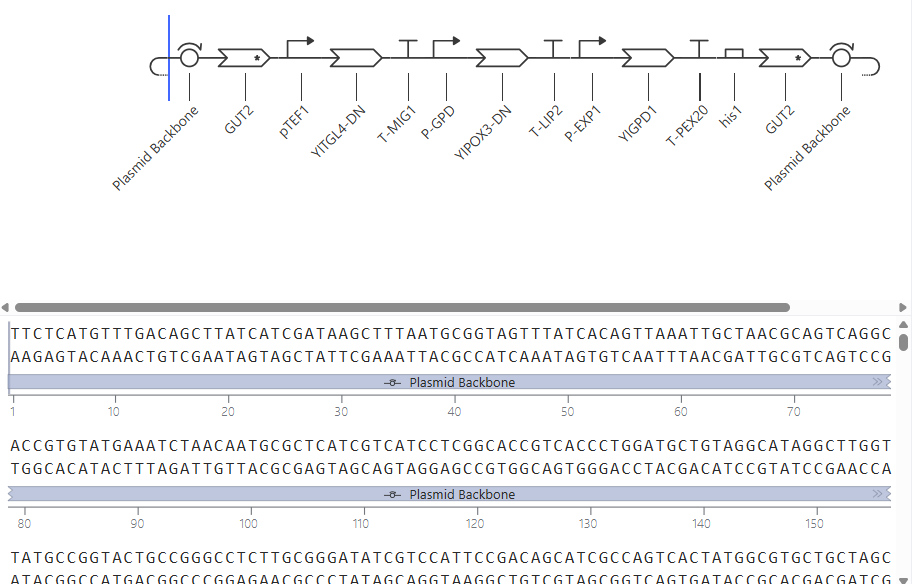
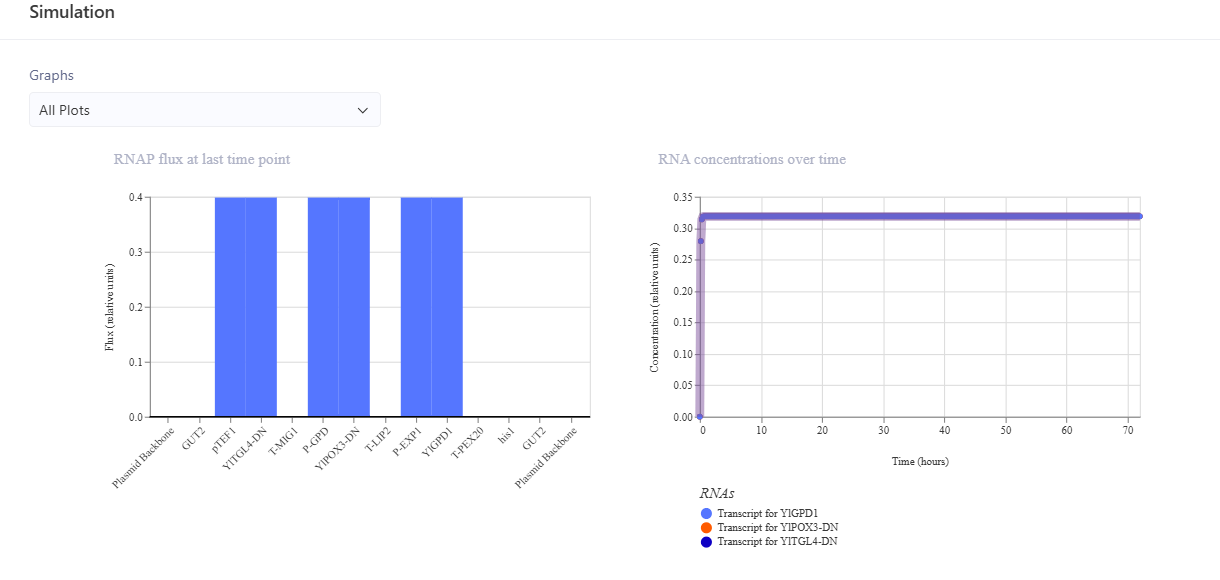
I changed the construct to three different plasmid constructs as the single construct was massive. The plasmids are used for integrating into the chassis; genome and knocking out the FAD2 gene, POX gene and Zeta
Part 4: Optimize and quality-check
Use Kernel’s design tools on your coding sequence and construct, and interpret the results rather than just running them.
Codon-optimize your CDS for your chosen host. Compare before and after: what changed, and why does codon usage matter for expression in this organism? Note any constraints you applied (e.g. avoiding certain restriction sites, GC content). Search your sequence (BLAST / sequence search) against known sequences. Is your CDS what you think it is? Is it identical to a natural gene, or novel? What is the closest match? Run the safety screen on your construct. Summarize what it checks for and what it reports. If it flags something, explain whether it is expected for your design and how you would respond.
I ran the kernel codon optimization tool and below are the results: I ran the codon optimization in Saccharomyces cerevisae because my sequence was already codon optimized for Yarrowia lipolytica.
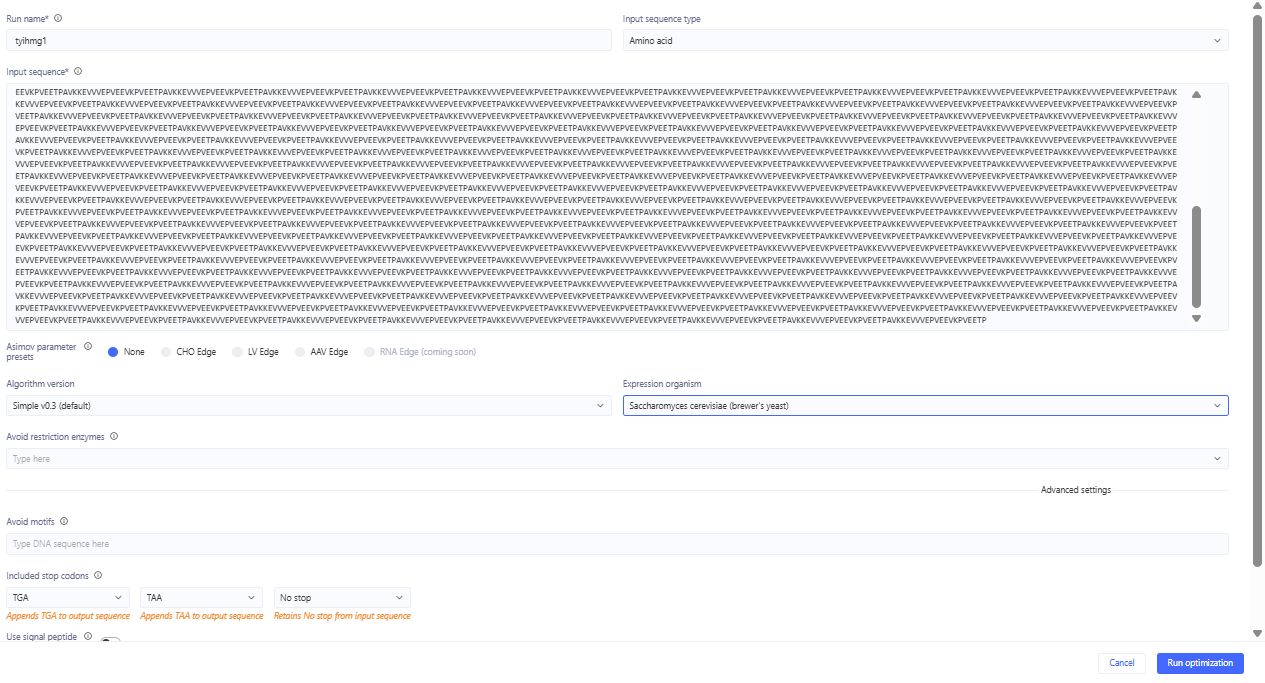
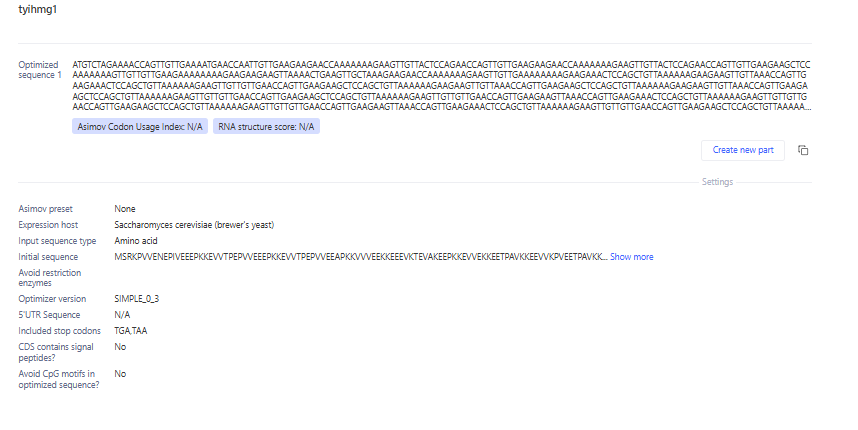
The codon optimization is important because of codon degeneracy that is each amino acid can be coded for by more than one codon. So it is the organisms prefernce to use codon of its choice to produce the amiono acid.
There is a change in both organisms as the GC content is less in yeast compared to host organism.
https://www.uniprot.org/blast/uniprotkb/ncbiblast-R20260927-181447-0196-52003174-p1m/overview
https://www.uniprot.org/blast/uniprotkb/ncbiblast-R20260927-183544-0312-26541569-p1m/overview
https://www.uniprot.org/blast/uniprotkb/ncbiblast-R20260927-183625-0894-67310649-p1m/overview
https://www.uniprot.org/blast/uniprotkb/ncbiblast-R20260927-183611-0468-50399564-p2m/overview
https://www.uniprot.org/blast/uniprotkb/ncbiblast-R20260927-183346-0733-34799667-p1m/overview
https://www.uniprot.org/blast/uniprotkb/ncbiblast-R20260927-182445-0151-64639262-p1m/overview
https://www.uniprot.org/blast/uniprotkb/ncbiblast-R20260927-183236-0163-68355194-p1m/overview
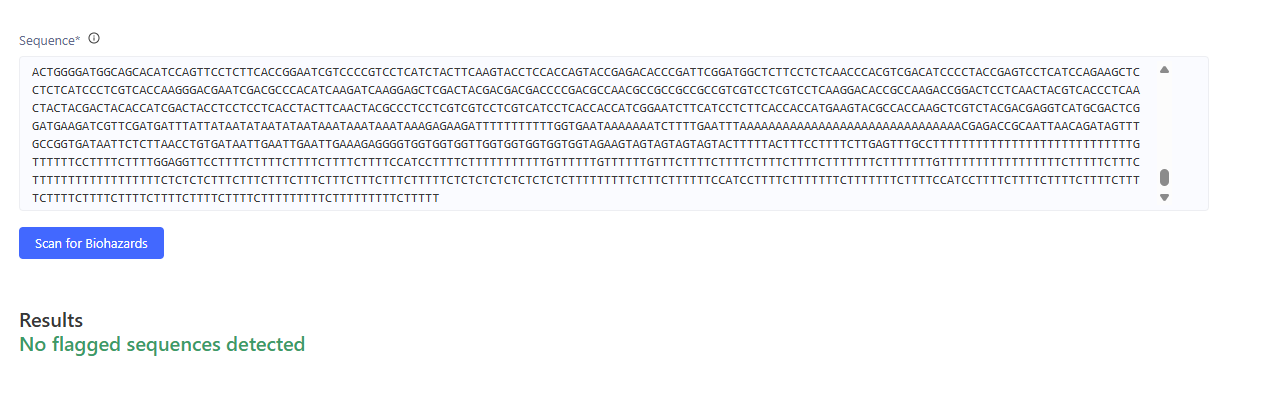
I ran the kernel’s Biosecurity Sequence scanner and got the above results What it Checks For: Regulated Pathogens & Toxins: Matches to “Select Agents” or controlled human, animal, or plant pathogens (e.g., specific viral replication machinery, select bacterial toxins). Dual-Use Research of Concern (DURC): Genes that could inherently enhance the virulence, lethality, transmissibility, or host range of a dangerous biological agent. High-Risk Homology: Significant Sequence Identity (typically (>95%) nucleotide alignment or significant functional protein homology) to restricted items.
The three plasmid designs
I concluded that my gene construct is now codon optimised and can run in the desired chassis atleast in software.The biosecurity scanning states that my organisms is free from causing any detrimental effects to environment and does not possess any harmful virulent genes.
Part 5: From design to build
A sequence in software is not yet DNA. Using this week’s readings, reason about how your construct would actually be made. Answer in your write-up:
How would you build it? Would you order it as synthetic DNA, assemble it from smaller fragments (e.g. Gibson assembly), or build it from a pool of oligos synthesized on a chip? Justify your choice given your construct’s length and complexity.
The optimal approach is a hybrid method: order smaller synthetic gene fragments (gBlocks/eBlocks) from a vendor, and assemble them using Gibson Assembly or Golden Gate Assembly into a vector.
Fully assembled clonal plasmid from a provider like Twist Bioscience or GenScript is prohibitively expensive.
Assembling a 20+ kb sequence entirely from a pool of 200-bp oligos requires complex, multi-tiered hierarchal assembly and extensive screening. The error rate from chip-synthesized oligos is too high to reliably build a construct of this length.
4 or 5 sequence fragments of 3–5 kb each, you leverage cheap, high-fidelity commercial synthesis. You can then cleanly join these fragments in a single reaction using Gibson Assembly (via 30-bp overlapping regions) or Golden Gate Assembly
What does synthesis constrain? Synthesis has error rates and struggles with certain sequences. Does your design contain anything hard to synthesize? How would error correction or fragment-based assembly change your approach?
Repetitive Promoters (P-TEF1 and P-TEF1-short): Having two versions of the exact same promoter in the same construct creates massive direct repeats.it poses a severe risk of homologous recombination and loop-out deletions once transformed into Yarrowia lipolytica.
Transposon integration sites are naturally highly repetitive. These repeat elements cause synthesis machinery to slip, leading to high frame-shift error rates.
Splitting the construct so that P-TEF1 is on Fragment 1 and P-TEF1-short is on Fragment 2 prevents the synthesis provider from having to build them on the same physical piece of DNA.
Due to the risk of structural mutations during cloning, the assembled construct must be validated via long-read Oxford Nanopore sequencing (NGS) to check all junctions.
Prototype vs. scale. Mirroring HW1: the way you’d build one construct to test your idea may differ from how you’d produce DNA at the scale your product needs. Briefly describe both if they differ.
Prototype Phase Your immediate goal is simply to secure one single, perfectly accurate clone to verify if your Yarrowia strain successfully synthesizes the desired oleic acid, squalene, and hydroxytyrosol yield. You tolerate manual laboratory assembly steps and basic troubleshooting because you only need to screen a few colonies via Colony PCR and confirm the singular winner with sequence verification.
Scale Phase If your product requires testing thousands of pathway iterations (e.g., swapping out different promoter strengths to fine-tune metabolic flux and maximize yield), ordering unique custom fragments for every single variation becomes a major bottleneck. At scale, you transition to a standardized Modular Cloning (MoClo) architecture executed by automated robotic liquid handlers. Every individual promoter, coding sequence, and terminator is built and sequence-verified once as a clonal “Level 0” entry plasmid. High-throughput automation lines can then programmatically mix and match these reusable modular components into massive combinations, completely bypassing the need for repeated custom synthesis.
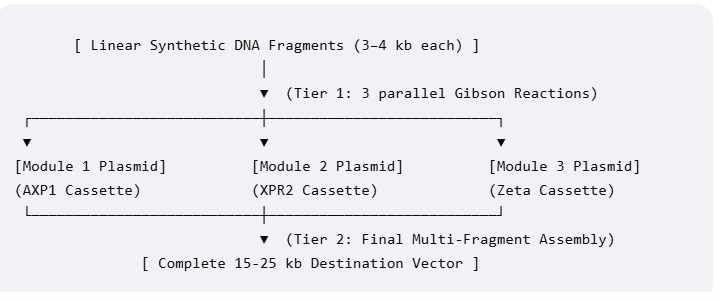
Change in strategy
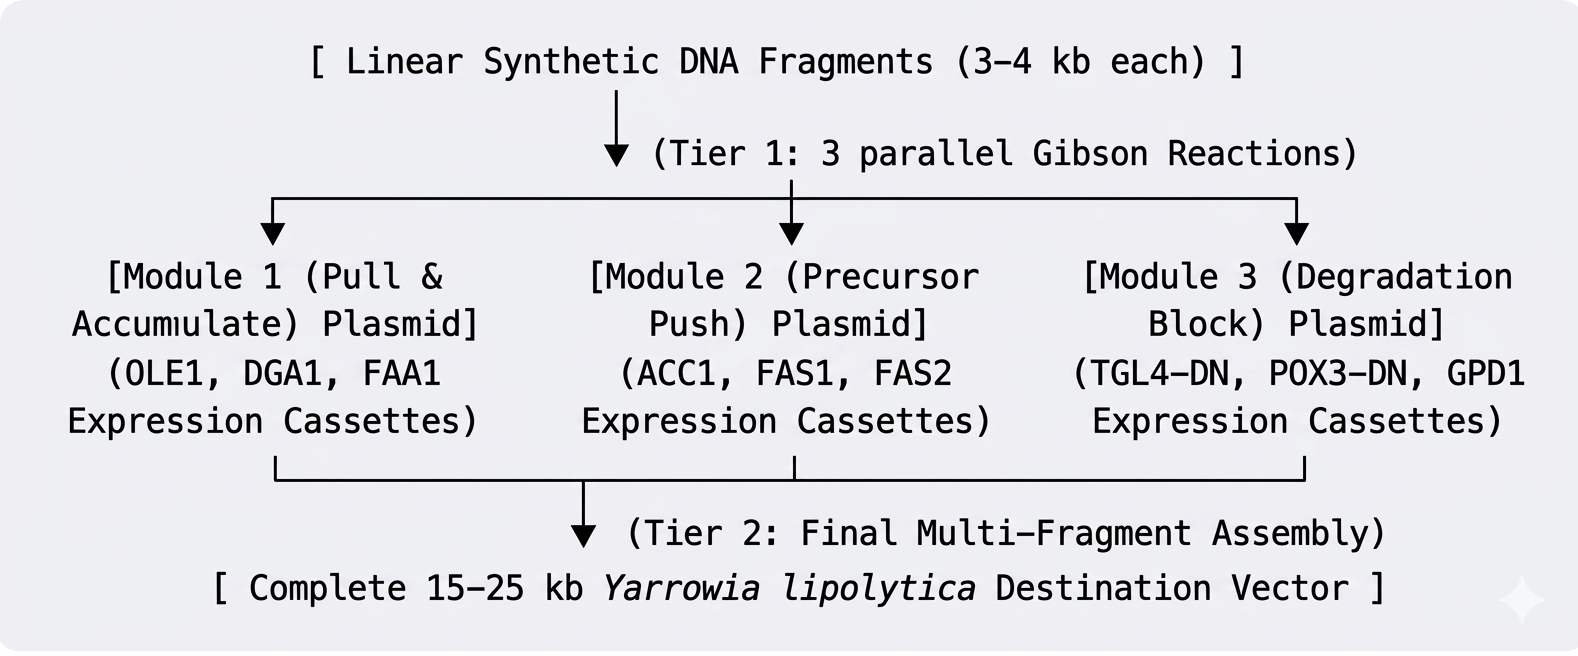
Part 6: What don’t you know yet?
As in Homework #1, close by naming the edges of your design. Identify the 2–3 biggest unknowns or risks in your construct. For example: Will the promoter give the right expression level? Will the protein fold and be active in this host? Will it be secreted? Is codon optimization enough, or do you need to tune it empirically?
For each, state how you would find out: the measurement, experiment, or design variant you would try next. A good answer here shows you know which decisions are still bets
It is a huge cassette of 3 modules so don’t know whether they will all work together.
The construct might not give me the output as expected because this organism has been tested for other oil production like squalene and oleic acid but not olive oil as a wholeas 3 components.
The modified pathway for production should not be a burden to the chassis, by diverting vital resources, and creating cellular stress.
Module 1 (The FAD2 Locus Bet)
The Unknown: Did the deletion of FAD2 fully lock the lipid profile into an olive oil equivalent (high oleic acid), or is the cell bypassing this block using alternative desaturases or scavenging fatty acids from the media? • The Measurement: Perform FAME (Fatty Acid Methyl Ester) analysis via GC-MS (Gas Chromatography-Mass Spectrometry) on the harvested cell pellets. • The Experiment: Grow the integrated strain alongside a wild-type control in minimal media with glucose as the sole carbon source. Harvest cells during late stationary phase, extract the total lipid fraction, transesterify them to FAMEs, and profile the percentages of C18:1 (oleic), C18:2 (linoleic), and C16:0 (palmitic) chains. • Design Variant to Try Next: If linoleic acid (C18:2) is still detected, it means a cryptic secondary desaturase is active. The next variant to try is a dual knockout targeting both the FAD2 locus and the OLE2 locus (if present/active) using CRISPR-Cas9, or driving the system using a weaker, single-copy truncated selection marker variant like ura3d1 to stabilize the integration footprint.
Module 2 (The POX2 Locus Bet)
The Unknown: Is the “Push” module (ACC1, FAS1, FAS2) functioning at the right stoichiometric balance, or are unbalanced alpha/beta subunits causing protein aggregation, toxic precursor accumulation, or metabolic bottlenecks? • The Measurement: Measure relative transcript levels via RT-qPCR and functional protein abundance via LC-MS/MS Proteomics. • The Experiment: Extract total RNA and total protein from actively growing exponential-phase cultures. Quantify the exact ratio of FAS1 to FAS2 transcripts. An unbalanced ratio (e.g., 5:1 instead of a balanced 1:1 functional macromolecular hexamer assembly) flags an expression bottleneck. • Design Variant to Try Next: If FAS1 or FAS2 expressions are heavily skewed or if free fatty acids are causing lipotoxicity, swap the strong constitutive promoters (P-GPD / P-EXP1) for a pair of strictly matched, identical promoters (e.g., dual bidirectional P-TEF1-P-PGK1 architectures) or integrate a feedback-regulated promoter driven by fatty acid concentrations to prevent precursor overload.
Module 3 (The GUT2 Locus Bet)
The Unknown: Does the dominant-negative YlTGL4-DN mutant successfully crowd out structural lipid-body drop mobilization, or are alternative native lipases (like TGL3 or extracellular lipases) breaking down the oil droplets as fast as you assemble them? • The Measurement: Monitor Intracellular Lipid Droplet Dynamics using Nile Red or BODIPY staining via Flow Cytometry (FACS) coupled with an intracellular TAG-to-DAG ratio assay. • The Experiment: Stained cells are evaluated over a time-course experiment during the starvation/stationary phase. If the mean fluorescence intensity drops sharply during stationary maintenance, it proves the cell is successfully mobilizing and burning its oil reserves despite TGL4-DN. • Design Variant to Try Next: If oil degradation is still occurring, transition from the dominant-negative single-point mutation strategy to a absolute multi-gene knockdown network. Try a CRISPRi (dCas9-Mxi1 multiplex) layout targeting the promoters of TGL3, TGL4, and LIP2 simultaneously, loaded directly onto the integrated GUT2 carrier vector.
The Destination Vector System Bet (The Assembly/Integration Risk)
The Unknown: Why did the multi-gene simulator output a zero-expression profile, and will this massive 15–25 kb continuous block integrate cleanly without structural genome dropouts? • The Measurement: Verify complete integration structures using Junction PCR followed by Long-Read Whole Genome Sequencing (Oxford Nanopore/PacBio). • The Experiment: Design diagnostic primers where the forward primer binds outside the genomic homology arm (e.g., native chromosome region) and the reverse primer binds inside your synthetic promoter block. Run PCR amplifications on surviving transformant colonies to confirm true double-crossover events at all three loci. • Design Variant to Try Next: If long linear transformation yields zero colonies or faulty integrations due to internal homologous loops between identical terminators (T-MIG1, T-LIP2), rebuild the assembly variant using completely orthogonal, non-homologous terminators sourced from alternative yeast species (like Saccharomyces cerevisiae or Kluyveromyces lactis) to completely eliminate internal repetitive loop dropouts.