Hey :)
I’m Wanqi (Yuki) Fang, a first-year MDes Ecologies student at the Harvard Graduate School of Design. I am coming from a culture, technology, and sustainable business background, with a focus on sustainability and the relationship between technological innovation, business, and environmental change.
My current interests are in biomaterials, manufacturing, and how sustainable materials can move beyond small-scale experimentation toward real-world production. I’m especially interested in how biology and new manufacturing technologies might create materials that can compete with conventional ones in performance, cost, and scalability.
See the nav bar on the left to look through my work for How To
Biomanufacture Almost Anything (Fall 2026)!
Subsections of <Wanqi(yuki) Fang> — HTBAA Fall 2026
Week 1 HW: Final Project Ideas
(1) What would you like to biomanufacture and why?
Can we program biology to manufacture a fiber with a specific mechanical function that apparel currently relies on petrochemical elastane to provide?
I would like to explore a biomanufactured elastic material for stretch and performance apparel, with the long-term goal of replacing or reducing conventional elastane (spandex) in products such as leggings and sportswear. I am interested in performance apparel because the challenge is reproducing a very specific mechanical function. Elastane can stretch substantially, return toward its original shape, and repeat this process many times while helping a garment maintain its fit. At the same time, conventional elastane relies on fossil-derived inputs, which motivates me to explore whether its function could be produced through a different manufacturing pathway.
There are already developments that make me think this is an interesting moment to explore a different approach. Spiber’s Brewed Protein™ materials show that proteins produced through microbial fermentation can be processed into fibers and used in commercial garments. However, I would like to push this idea toward a different question: could biology produce a fiber not only because it can become a textile, but because it can provide a specific mechanical function?
At the same time, the elastane industry is beginning to explore renewable alternatives. The LYCRA Company, for example, has been developing bio-derived LYCRA fiber using renewable feedstocks. This reduces reliance on fossil-derived inputs, but it still produces elastane through a version of the existing polymer-manufacturing pathway. I am interested in a different possibility: could the elastic material itself eventually be produced by a living system?
I do not yet know exactly what protein, microorganism, or manufacturing process would be best for making this material. That is part of what I want to explore through this project. This is also different from the way I have previously worked with biomaterials. In experiments with materials such as gelatin, I started with existing ingredients and changed how they were mixed or processed to change the final material. It felt closer to cooking because the ingredients already existed, and I was learning how their different properties interacted. I have never designed a material by working at the level of DNA or engineering cells to produce it. I am interested in learning whether some of the material’s properties could instead come from what a living system is designed to produce.
More broadly, this project connects to a question that has shaped my interest in sustainable materials: can a sustainable material eventually compete with an existing material without asking consumers to accept much lower performance or much higher prices? Performance apparel is an interesting case for me because it still relies heavily on synthetic, petrochemical-derived materials, while also demanding very specific material performance. Elastane captures both sides of this problem: it is conventionally produced from fossil-derived inputs, but it also performs its function extremely well. For this project, I therefore want to ask whether biomanufacturing could eventually offer a different way of producing that elastic function without sacrificing the performance that makes elastane so useful in clothing.
(2) What living system would you use?
I would initially explore a microbial system, such as engineered E. coli or yeast, to produce the elastic protein through fermentation.
The basic idea would be to introduce DNA with instructions for producing the target protein into a microbial host. As the microorganisms grow, they would use those instructions to produce the protein (Zhang et al., 2017). At a high level, the inputs would include the engineered cells, a carbon source such as glucose, nutrients, water, and oxygen if needed.
The process I am imagining is:
Inputs → engineered microbial cells + nutrients → cell growth and protein production → elastic protein → recovery/purification → fiber processing
After fermentation, the protein would need to be separated and purified. It would then enter a separate material-processing stage, where I would explore whether it could be turned into a continuous fiber.
I do not yet know whether E. coli, yeast, or another microbial system would be the best choice. I am starting with microbial fermentation because it provides a relatively simple way for me to think about using living cells as a manufacturing system for proteins. As I learn more, I would need to compare different microbial hosts based on how well they can produce the protein and how easy it is to recover the protein afterward.
I am also making two major assumptions at this stage: first, that a microorganism can produce enough of the selected elastic protein, and second, that the protein can actually be processed into a usable elastic fiber. Both are things I would need to test rather than assume are already possible.
(3) How would you use automation?
I would use an automated liquid-handling and screening platform, potentially through a Cloud Lab, during the early development of the material.
The main reason I would use automation is that I do not expect the first attempt to immediately produce the elastic material I want. There are many things I may need to change, such as the protein design, the microorganism being used, and the conditions in which the cells are grown. Testing all of these possibilities manually would take a long time.
I would therefore use automation to test multiple possibilities in parallel. For example, an automated system could prepare small cultures, add media and other reagents, grow different samples under controlled conditions, and collect samples for measurement. I could then compare which conditions produce more protein and identify promising candidates for further material testing.
At a high level, I imagine the process as:
different protein designs and growth conditions → automated small-scale experiments → sampling and measurement → compare results → choose promising candidates → test again
This is where the Design-Build-Test-Learn (DBTL) cycle discussed in the course becomes useful to me (Petzold & Mukhopadhyay, 2025). Rather than expecting to know the correct biological design from the beginning, I could use each round of experiments to learn what should be changed in the next round.
At this stage, I would mainly use automation for R&D and screening rather than manufacturing the final fiber. I would want to learn two basic things: Can the cells produce enough of the protein? And can that protein eventually give me the material properties I want? A protein that is very elastic but extremely difficult to produce may not be practical, while a protein that is easy to produce but does not provide enough elasticity would also not solve the problem.
If the project eventually moved toward larger-scale manufacturing, the role of automation would change. Instead of testing many small variations, automation could be used to help consistently control and monitor the production of the selected material at a larger scale.
(4) How much would you need to make, and how long would it take?
(a) How much?
For an initial meaningful manufacturing scale, I would estimate the amount of biomanufactured elastic protein fiber required to produce 1,000 pairs of performance leggings.
Commercial leggings commonly blend a primary fiber such as nylon or polyester with an elastic fiber. A study of commercial leggings reported elastic-fiber contents ranging from approximately 13% to 20% by fiber composition (Lee & Do, 2023). For this back-of-the-envelope calculation, I will assume that my biomanufactured protein fiber replaces the elastic component of a conventional legging at 15% by mass.
I will also assume that one pair of leggings weighs approximately 250 g. This is a simplifying assumption for an initial estimate; actual garment weight varies with size, fabric construction, and fabric weight.
Elastic protein required per pair:
250 g leggings × 15% elastic fiber = 37.5 g elastic protein fiber/pair
For 1,000 pairs:
37.5 g/pair × 1,000 pairs = 37,500 g = 37.5 kg
Therefore, an initial manufacturing target would be approximately 37.5 kg of finished elastic protein fiber to supply the elastic component of 1,000 pairs of leggings. This estimate does not yet account for material lost during protein recovery, purification, or fiber processing. In practice, the microbial system would need to produce more than 37.5 kg of protein. Since I do not yet know the recovery efficiency of the proposed process, I will treat 37.5 kg as the minimum target for this initial calculation.
(b) How long?
For this estimate, I will use 4.3 g of recombinant protein per liter of culture as an approximate benchmark. A published study of a related silk-elastin-like protein produced in E. coli reported a production level of 4.3 g/L (Martin et al., 2014). Since the actual production rate of my proposed protein is not yet known, I am using this value only as a benchmark from a related system.
From the previous calculation, my minimum target is 37.5 kg of protein fiber for 1,000 pairs of leggings.
37.5 kg = 37,500 g
37,500 g ÷ 4.3 g/L ≈ 8,721 L
Assuming 1,000-L bioreactors:
8,721 L ÷ 1,000 L/reactor = 8.721 ≈ 9 bioreactors
This gives me a minimum estimate of approximately 8,700 L of microbial culture. The actual volume would likely be higher because some material would be lost during protein recovery, purification, and fiber processing, but I do not yet know what those losses would be.
Estimating the time is more difficult because I do not yet know the actual growth and protein-production rate of the microbial system. For this initial calculation, I will assume that one fermentation cycle takes approximately 2 days. This is a simplifying assumption rather than a known production time for my proposed material. For a simple estimate, I will imagine that the required 8,700 L of culture could be divided across approximately nine 1,000-L bioreactors operating in parallel. If all nine bioreactors could complete fermentation at the same time, the fermentation stage would therefore take approximately 2 days rather than requiring multiple sequential batches.
Additional time would then be required for protein recovery, purification, and fiber processing. I do not yet have enough information to estimate these downstream steps reliably, so the two-day estimate only represents the assumed fermentation stage rather than the complete manufacturing process.
The automation used at this scale would also be different from the automation I proposed for prototyping. During the R&D stage, I would use a Cloud Lab or liquid-handling robot to test many protein designs and growth conditions in small volumes. At manufacturing scale, the goal would instead be to produce a large amount of one selected protein consistently. Automation could therefore shift toward monitoring and controlling the fermentation process, such as temperature, pH, nutrient feeding, and sampling.
This calculation is highly approximate because the actual protein yield, production time, downstream recovery, and fiber-processing efficiency are still unknown. However, it suggests that even producing enough elastic fiber for only 1,000 pairs of leggings could already require fermentation at the scale of thousands of liters.
(5) What don’t you know yet?
After working through this proposal, I realized that several of my calculations depend on things that I do not yet know. In particular, I see three major technical unknowns that would determine whether this idea could actually work.
1. Can a biologically produced protein provide enough elasticity and recovery?
The most fundamental unknown is whether a protein-based material could provide the mechanical behavior needed to replace or reduce elastane. I do not yet know what kind of protein would be appropriate or how close its performance could come to conventional elastane. I would need to test how far candidate materials can stretch, how well they return to their original shape, and what happens after many repeated cycles of stretching.
2. Can a microbial system produce enough of the material?
My scale calculation currently depends on an assumed production yield based on related protein systems, rather than my proposed material itself. I do not yet know whether E. coli, yeast, or another microbial system would be most appropriate, or how much protein it could actually produce. This would need to be measured experimentally because the production yield would directly affect how much fermentation volume, time, and eventually cost would be required.
3. What happens between producing the protein and having an actual textile fiber?
This is probably the part of the process I currently understand the least. Producing a protein does not automatically mean that I have a usable fiber. I still need to understand how the protein could be recovered, processed, and spun into a continuous fiber, and whether it would retain its elasticity after those steps. Eventually, the resulting fiber would also need to be tested for repeated stretching, washing, and compatibility with other textile fibers.
These three questions represent different stages of the same problem: can the material provide the function I want, can biology produce enough of it, and can it actually become a usable textile? Until these questions are tested, the scale and manufacturing-time calculations in this proposal should be understood as initial estimates rather than predictions.
Petzold, C. J., & Mukhopadhyay, A. “From Bench to Biofactory: High-Throughput Technologies and Automated Workflows to Accelerate Biomanufacturing.” 2025. Course reading.
Zhang, Y. H. P., Sun, J., & Ma, Y. “Biomanufacturing: History and Perspective.” 2017. Course reading.
AI Use
I used ChatGPT (OpenAI) during the development of this assignment to brainstorm and refine the project idea, identify relevant examples and literature, work through the back-of-the-envelope calculations, and edit the writing for clarity. I reviewed and revised the final responses and checked the sources and assumptions used in the assignment.
Representative prompts included:
“What living system could be used to biomanufacture an elastic protein fiber?”
“How could automation be used to test different protein designs and growth conditions?”
“Help me estimate how much elastic fiber would be needed for 1,000 pairs of leggings.”
“What are the biggest technical unknowns in this proposed biomanufacturing system?”
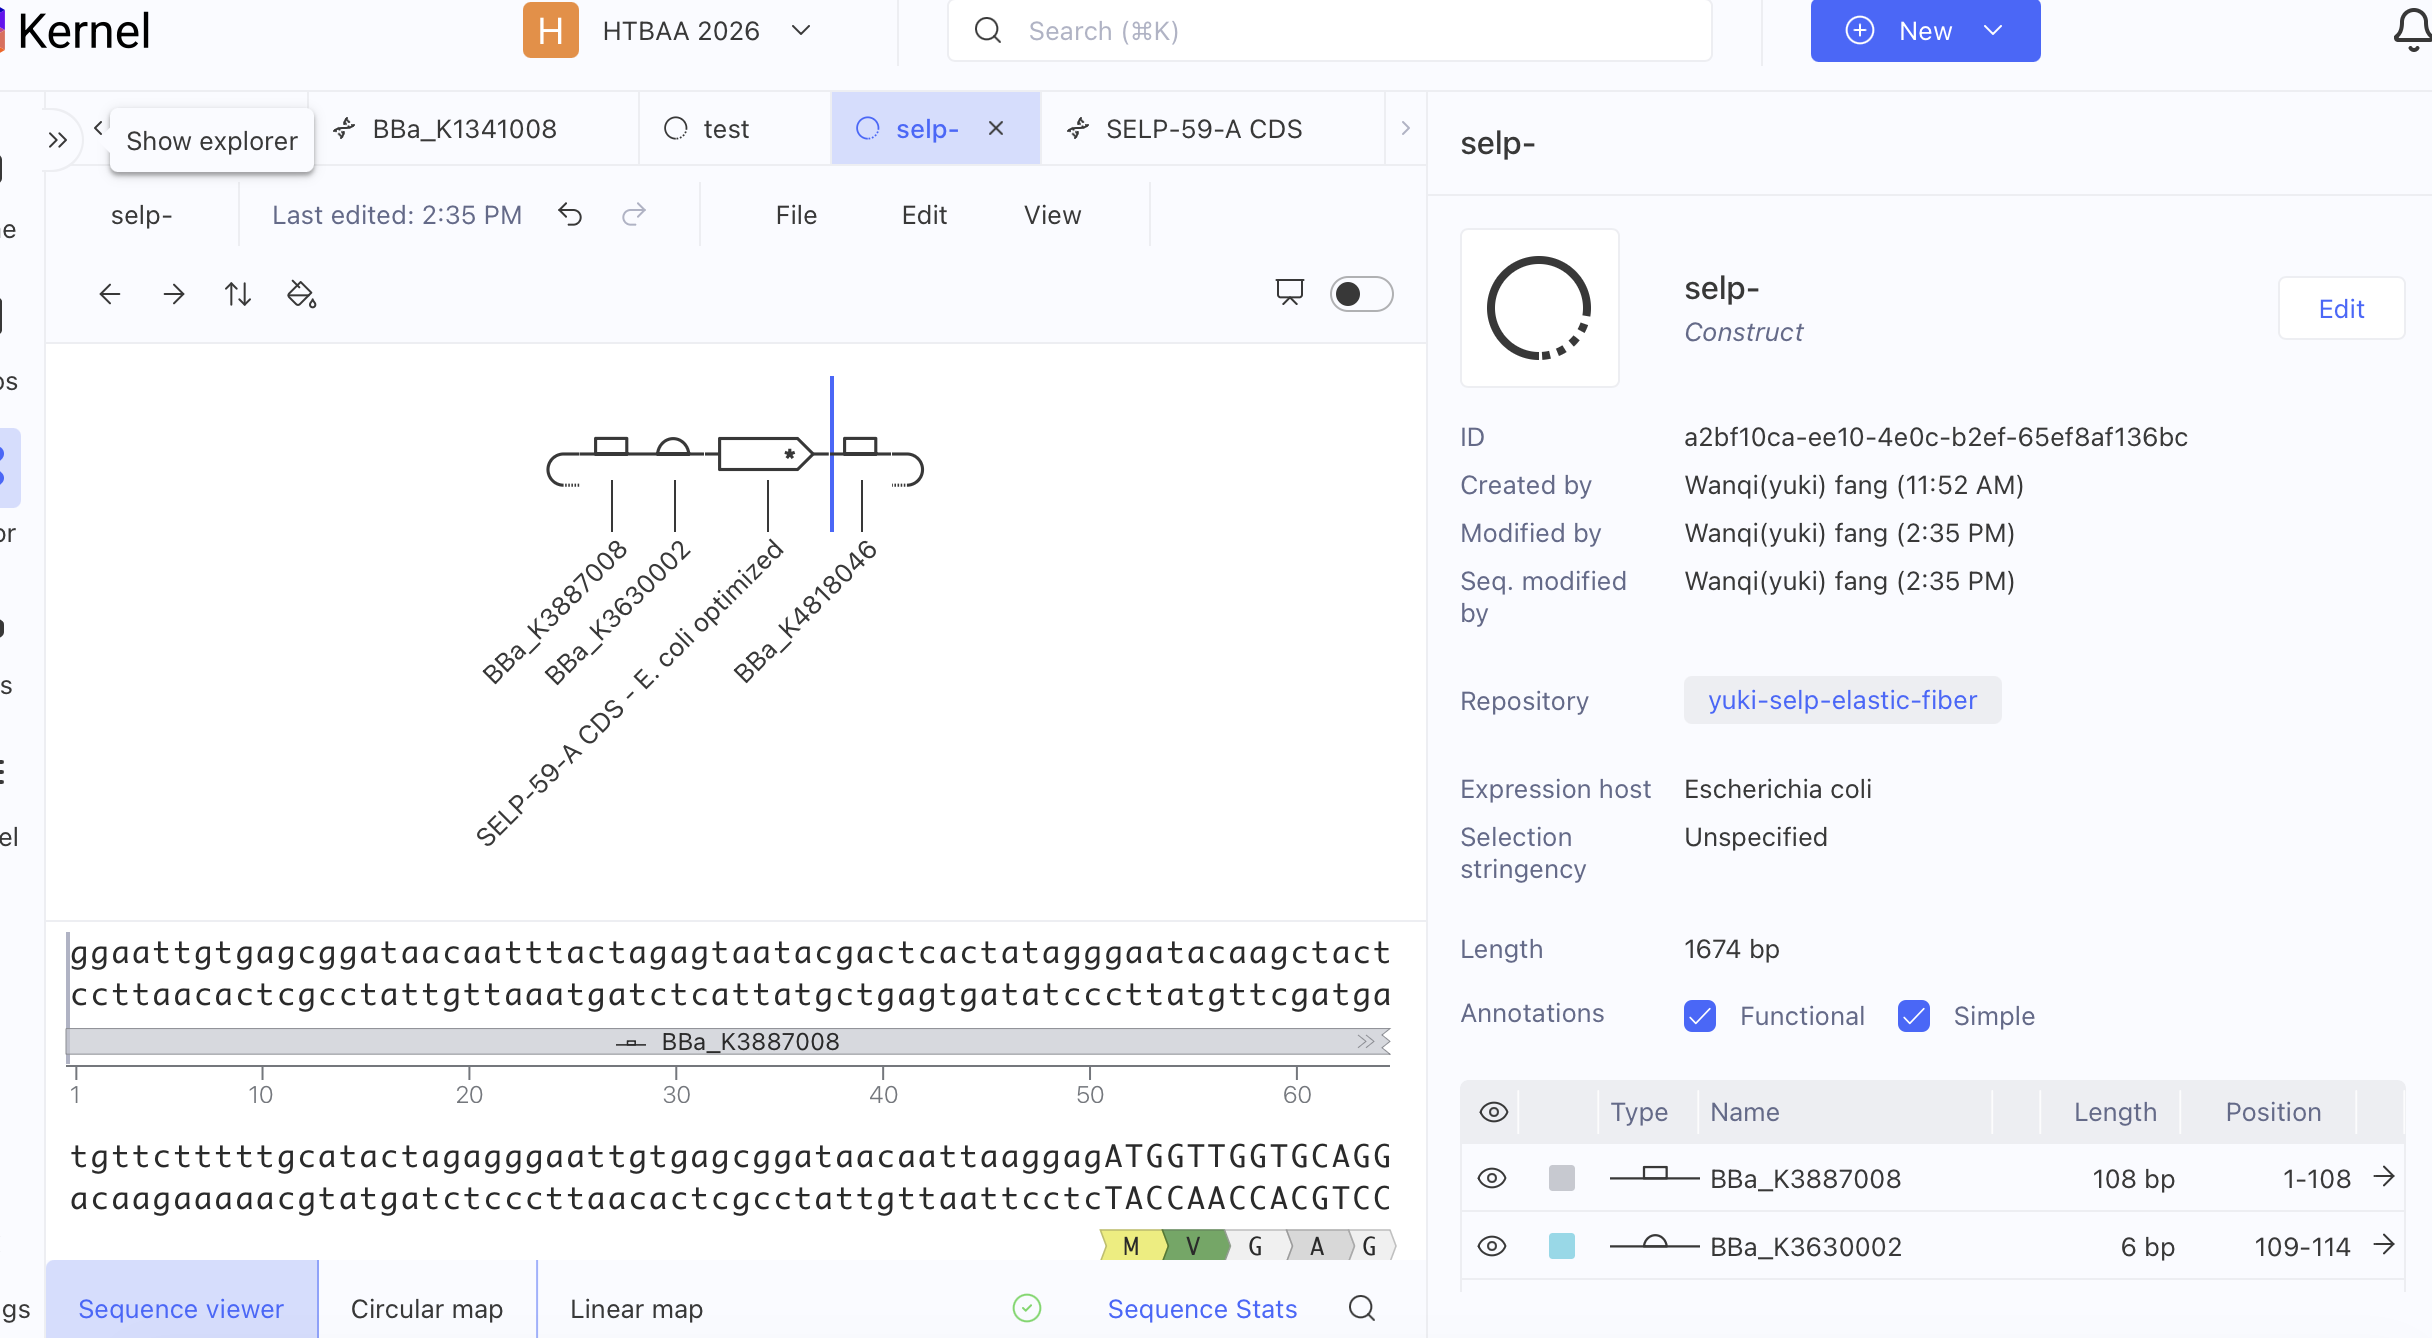
I created a Kernel repository named yuki-selp-elastic-fiber, with a project folder named selp.
Part 1 — Expression Target
For this project, I am designing an expression system for SELP-59-A—a recombinant silk-elastin-like protein. I chose SELP-59-A as a starting point because my longer-term project asks whether a biologically produced protein could eventually provide some of the elastic function currently provided by elastane in performance textiles. At this stage, I am not assuming that SELP-59-A itself can replace elastane. Instead, I am using an existing and experimentally demonstrated protein as a baseline that I could later modify and test.
The SELP-59-A sequence comes from previously published work by Machado et al. (2013) and Collins et al. (2014). SELP-59-A consists of nine repeats of a monomeric unit containing five repeats of the silk-like sequence GAGAGS and nine repeats of the elastin-like sequence VPAVG. Collins et al. expressed this protein in E. coli BL21(DE3), which is why I selected E. coli as the host for my initial design.
For this first design, I am treating SELP as an intracellular product. The protein would therefore be produced inside the cells and recovered and purified after expression. I am keeping this first construct relatively simple rather than adding a signal peptide before I know whether the basic expression system works.
Part 2 — Genetic Parts
Part
Choice
Why I chose it
Promoter
T7 promoter (BBa_K3887008)
T7 provides strong, controllable expression in an E. coli system containing T7 RNA polymerase, consistent with the BL21(DE3)-based expression strategy used in the published SELP work (Collins et al., 2014).
RBS
BBa_K3630002
The ribosome binding site provides the translation-initiation signal needed for E. coli to begin translating the SELP coding sequence.
CDS
SELP-59-A CDS
This is the protein I want the cells to produce. The sequence was based on the published SELP-59-A design and entered into Kernel with start and stop codons.
Terminator
BBa_K4818046
The terminator provides a defined end to transcription after the SELP coding sequence.
Backbone
modified pET25b(+)
I chose this as the intended expression-vector context because the published SELP-59-A work expressed the protein in E. coli BL21(DE3) using a modified pET25b(+) vector (Collins et al., 2014).
I assembled the expression cassette itself in Kernel. I specify modified pET25b(+) as the intended vector backbone based on the published SELP-59-A expression system, rather than substituting an unrelated backbone simply because it was available in Kernel.
Part 3 — Construct Assembly
I assembled the final expression cassette in Kernel in the 5′→3′ order:
T7 promoter → RBS → E. coli-optimized SELP-59-A CDS → terminator
I checked that the SELP-59-A CDS contains the expected start and stop codons and that the parts are in the intended orientation. The expression cassette is intended to be placed in a modified pET25b(+) vector for expression in E. coli BL21(DE3), following the general expression system used in the published SELP-59-A work.
Part 4 — Optimization and Sequence Checks
Codon Optimization
I used Kernel’s codon optimizer to redesign the SELP-59-A coding sequence for expression in E. coli. I used the amino acid sequence as the input and selected Escherichia coli as the expression organism, with TAA as the stop codon. I did not add a signal peptide or additional motif constraints.
The optimization changed the DNA sequence while preserving the SELP-59-A amino acid sequence. This is possible because multiple codons can encode the same amino acid. Different organisms have different patterns of codon usage, so the goal was to generate a DNA sequence better suited to expression in E. coli without changing the protein I am trying to produce.
BLAST
I used NCBI Protein BLAST (blastp) to search the SELP-59-A amino acid sequence against the ClusteredNR database. The search did not return an exact SELP-59-A match. The top result covered 99% of my query and had an E-value of 2e-76, but only 30.89% sequence identity. Other results included repetitive and structural proteins, including collagen-like proteins.
I therefore would not interpret the BLAST result as identifying SELP-59-A as a natural protein. Instead, the result is consistent with the sequence being an engineered repetitive protein whose repeated amino acid patterns share similarity with other repetitive or structural proteins.
Biosecurity Screening
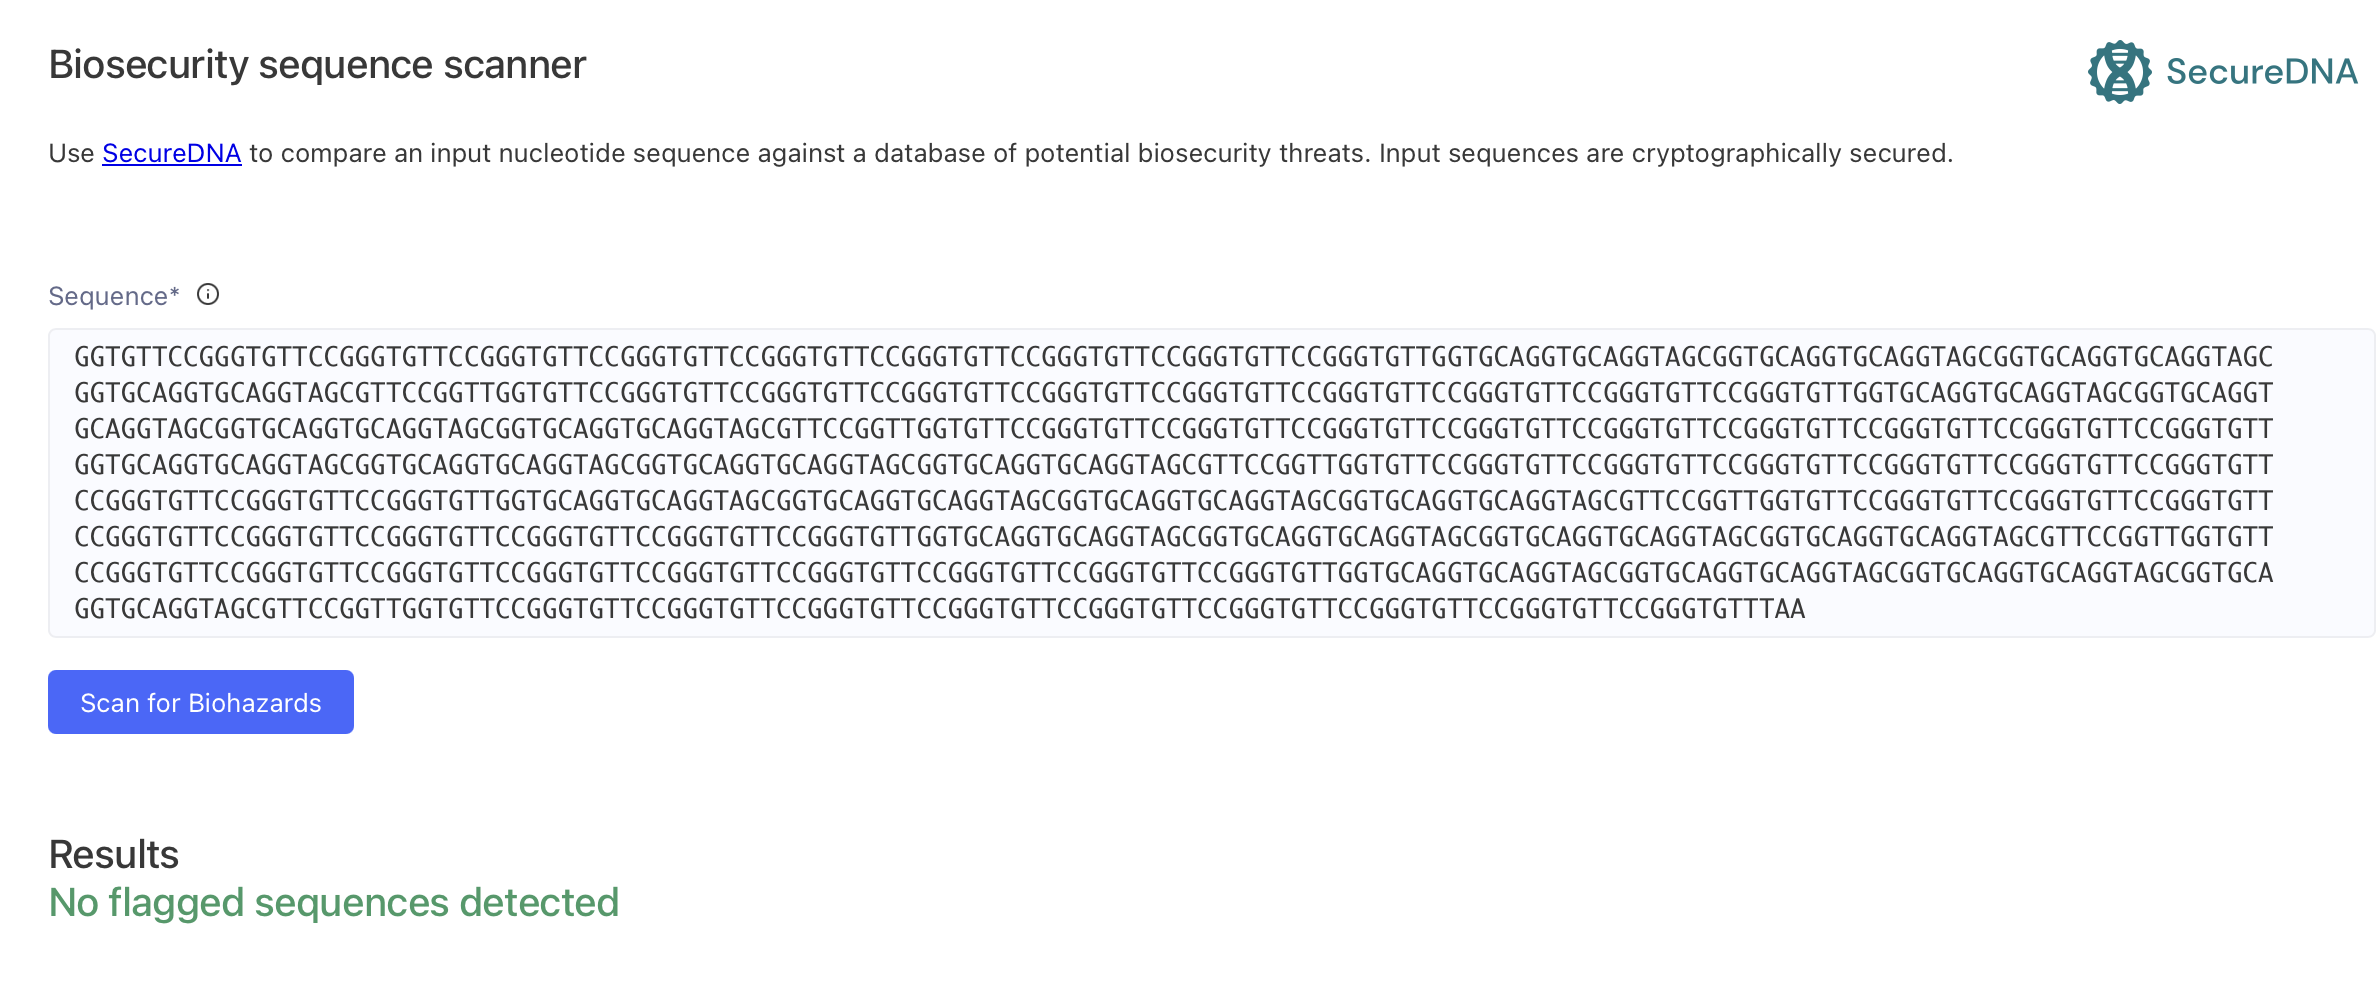
I ran the E. coli-optimized SELP-59-A coding sequence through Kernel’s SecureDNA biosecurity sequence scanner. The tool screens nucleotide sequences for matches associated with potential biosecurity concerns. The result was “No flagged sequences detected.”
I therefore did not identify any biosecurity flags for this sequence through the screening tool. This result only describes what the scanner detected and does not by itself establish that a biological construct is risk-free in every context.
Part 5 — From Digital Sequence to Physical DNA
Building the Construct
For the first prototype, I would order the E. coli-optimized SELP-59-A coding sequence as synthetic DNA rather than synthesizing the entire plasmid myself. Because SELP-59-A is highly repetitive, the sequence could be divided into smaller fragments if synthesizing it as one piece is difficult. I would then use Gibson Assembly to join these fragments with the expression vector. Gibson et al. (2009) showed that DNA fragments with overlapping ends can be joined in a single isothermal reaction. The assembled construct would then be sequence-verified before expression in E. coli.
Synthesis Constraints
The biggest issue for my design is probably repetition rather than length. SELP-59-A contains repeated silk-like and elastin-like motifs, which means large sections of the DNA look very similar. That can create problems during synthesis and assembly because similar sequences may hybridize or assemble incorrectly. Errors can also come from the shorter oligonucleotides used to build synthetic genes, as discussed by Kong et al. (2007). Kosuri et al. (2010) also shows how sequence similarity and increasingly complex oligonucleotide pools can make reliable assembly more difficult.
If synthesizing SELP-59-A as one sequence did not work reliably, I would split the CDS into smaller fragments, assemble them afterward, and sequence-verify the final construct. Error-correction methods could also become more important if I later tested multiple SELP variants. Tian et al. (2004) and Kosuri et al. (2010), for example, show approaches for reducing errors introduced during DNA synthesis.
Prototype versus Scale
At the prototype stage, I would first need to know whether the genetic construct works and whether E. coli can produce the designed SELP protein. But producing the protein is not the final goal of this project. The larger goal is to turn that protein into an elastic material that could eventually perform some of the functions of conventional elastane in textiles.
Moving from laboratory to commercial scale would therefore involve more than increasing fermentation volume. The cells would need to produce SELP reliably at larger scale, but the protein would also need to be recovered, purified, processed into fibers, and tested for properties such as stretch and recovery. At this stage, Homework 2 focuses mainly on designing and building the biological production system. If that system works, the next question would be whether the material itself can still be produced consistently and perform as intended as the manufacturing process scales.
Part 6 — Biggest Unknowns
1. Can the SELP be produced reliably in E. coli?
The first unknown is whether my genetic design will actually produce SELP reliably in E. coli. The previous SELP-59-A study shows that this protein can be produced in E. coli (Collins et al., 2014), but my construct and codon-optimized sequence are not identical to the system used in that study.
I would therefore first test whether the cells express the expected protein and measure how much protein is produced. If expression is low, I could compare different genetic designs, such as different promoters or expression conditions.
2. Will the produced protein have the material properties I actually need?
Even if the protein can be produced successfully, I still do not know whether it can provide the kind of elastic performance I am interested in. Previous work has already shown that another silk-elastin-like protein, SELP-47K, can be wet-spun into fibers with high deformability. Fully hydrated fibers reached strains to failure as high as 700%, and crosslinked hydrated fibers reached tensile strengths up to 20 MPa (Qiu et al., 2009).
However, high strain-to-failure does not necessarily mean the material has the elastic recovery and repeated-cycle performance required of elastane. I would therefore test properties such as stretch, recovery, and repeated loading. If the material does not recover well enough after stretching, I could compare SELP variants with different silk-like and elastin-like motif ratios or sequences.
3. Would scaling this process actually provide an environmental advantage?
A third unknown is whether this material would actually be environmentally preferable once the whole manufacturing process is considered. I do not want to assume that a biologically produced material is automatically more sustainable. Fermentation, temperature control, aeration, water use, feedstocks, purification, and fiber processing can all require resources.
If the project moves beyond the initial biological prototype, I would compare the energy, water, material inputs, and emissions of producing a functional amount of SELP-based elastic fiber with those of conventional petroleum-based elastane. This comparison would help determine under what production conditions, if any, the biological route provides a meaningful environmental advantage.
I used ChatGPT (OpenAI) as a learning and writing assistant during this assignment. Since I am new to molecular biology and DNA design, I used it mainly to help explain unfamiliar concepts, understand the assigned readings, and clarify the steps of the Kernel workflow. I also used it to help organize and edit my writing for clarity and Markdown formatting.
I used Kernel’s AI assistant while exploring available biological parts and constructing the initial expression system. All final design choices, interpretations, and project decisions were reviewed and made by me.
Homework 3 – Designing a Cell-Free Reaction Composition
A. COMPARE CELL-FREE REACTION COMPOSITIONS (20 minutes)
Why does the concentration of potassium glutamate and magnesium glutamate differ between
compositions? Which is more sensitive?
The concentrations of potassium glutamate and magnesium glutamate differ between formulations because CFPS performance depends on the chemical environment, so reagent concentrations need to be optimized together. Magnesium appears to be more sensitive because its concentration may need to be re-optimized for different lysate batches, and the reading also notes that protein synthesis depends nonlinearly on free Mg²⁺ and nucleotide concentrations.
Explain how a PEP+NTP reaction formulation is different from a Ribose+NMP reaction formulation.
A PEP + NTP reaction uses PEP as an energy source and NTPs as the building blocks for producing RNA. NTPs have three phosphate groups, which makes them a more ready-to-use form, but they also come with a higher reagent cost. In comparison, NMPs serve a similar role but have only one phosphate group, so they are not as ready-to-use as NTPs. Ribose is a sugar that can be used as a more basic starting material. Since the lysate still contains metabolic machinery from the original cells, it can help convert these simpler starting materials into the forms needed for protein synthesis.
Choose two cell-free reaction compositions from the literature, compare and contrast the choice ofreagents and the concentration of reagents.
I compared PANOx-SP and RFopt. For the reagents that they both use, RFopt has 8 mM magnesium glutamate, 362 mM potassium glutamate, and 5 mM amino acids, while PANOx-SP has 20 mM magnesium glutamate, 175 mM potassium glutamate, and 2 mM amino acids. They also use different reagents for energy and nucleotides. PANOx-SP uses 33 mM PEP and NTPs, while RFopt uses 50 mM ribose and NMPs. overall, i would claim PANOx-SP relies more on directly supplied, ready-to-use energy and nucleotide components, while RFopt uses more basic starting materials and relies more on the metabolic activity remaining in the lysate.
B. DESIGN ONE REACTION COMPOSITION FOR EACH OF THE THREE PROTEINS (40 minutes)
I reduced PEP(from 30 to 20) from the reference condition and supplemented the reaction with glucose(5.55) to test whether sfGFP production can be maintained while lowering reliance on the more expensive PEP energy system. I wasn’t assuming a stoichiometric replacement between PEP and glucose. I reduced PEP by one-third and added a moderate amount of glucose as a first screening condition to see whether glucose can partially support energy regeneration while reducing PEP use.
I kept the PETase reference formulation and added GSSG and GSH because PETase needs to fold into the correct shape to work properly. These reagents may help create a better chemical environment for that folding process, while DsbC helps the protein form the right internal bonds. I want to test whether this improves PETase activity.
I chose GSSG and GSH(they work as a redox pair) because PETase needs to fold correctly to be active, and this glutathione pair is commonly used in cell-free systems to create a chemical environment that supports disulfide-bond formation. I kept DsbC as the folding helper and used GSSG/GSH to adjust the surrounding folding environment.
I kept the established Reteplase folding system unchanged and instead modified the energy source. I reduced PEP from the reference condition and added sodium pyruvate to test whether part of the more expensive PEP system could be replaced while maintaining Reteplase activity.
I upvoted FkpA because Reteplase is the most difficult of the three target proteins to fold, with nine disulfide bonds. The proposed rationale suggests that FkpA could provide additional folding support together with DsbC. I thought this was especially relevant because the current Reteplase formulation already includes DsbC.